Write Python from a Spreadsheet Using Mito - Converting Spreadsheet Actions to Python Code
Discover how to seamlessly integrate spreadsheet operations with Python using Mito - generate Python code automatically while working with familiar spreadsheet functions like filtering, pivoting, and graphing.
Shinylive - Running R and Python Dashboards Without a Server Using Web Assembly
Master browser-based deployment of R and Python Shiny Dashboards using Web Assembly, eliminating server dependencies while maintaining interactive data visualization capabilities.
Data Analysis in Python - From Descriptive Statistics to Advanced Analytics
Master data analysis fundamentals in Python, from environment setup and data cleaning to advanced statistical methods like T-tests, ANOVA, and regression, with practical business applications and visualization techniques.
Introduction to Orchestrating ETL Processes with Apache Airflow
Master Apache Airflow's workflow management capabilities for ETL processes through practical examples. Learn core concepts like DAGs, Tasks, Variables, and XComs while building efficient data engineering pipelines.
Mastering AI Issue Debugging - A Data Scientist's Guide
Discover efficient AI debugging techniques through a unified system that streamlines troubleshooting processes, reduces resolution time, and improves product quality for data science teams.

DuckDB: Crunching Data Anywhere - From Laptops to Servers
Discover how DuckDB enables efficient data analysis across devices, from processing hundreds of gigabytes on laptops to terabytes on servers, with native support for SQL and popular file formats.
Building Reporting Services Using Quarkus and AI
Discover how to leverage LLMs and Quarkus to build innovative reporting services that transform data into meaningful insights, revolutionizing traditional API development approaches.
Apache HBase on Ozone - Data Storage and Computing
Discover how Apache HBase integrates with Ozone for enhanced distributed storage capabilities, exploring architecture, deployment strategies, and performance optimization techniques.
How Data Hub Flies Above the Clouds - Building a Centralized Social Media Analytics Platform
Discover how to build a centralized data platform using Azure services, integrating social media data through Data Lake, Databricks, and Power BI for comprehensive analytics and reporting.
Eye-tracking and AI: Unveiling the Limitations and Synergies
Explore the fascinating convergence of eye-tracking technology and AI, examining their limitations and potential for collaboration in advancing technological innovation.

Benchmarking Storage with AI Workloads - Performance Analysis and Optimization
Explore how storage systems impact AI/ML workload performance through comprehensive benchmarking analysis, focusing on data ingestion, training patterns, and inference workload optimization.
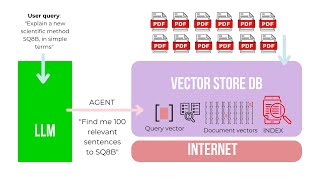
How to Import and Query Large PDF Collections in Language Models
Discover practical techniques for integrating and querying thousands of PDF documents with large language models to enable efficient corporate data analysis and Q&A capabilities.
Indexify Unveiled: A Scalable Content Extraction Engine for Multimodal Data
Discover how Indexify enables scalable content extraction and real-time knowledge base creation for AI workflows, focusing on unstructured data processing and hybrid search capabilities.
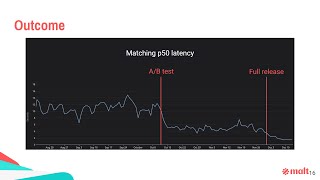
Superpower Your Semantic Search Using Vector Database - From Model Architecture to Deployment
Discover how to enhance matching systems using vector databases, focusing on implementation, deployment, and optimization for improved search performance and scalability in production environments.
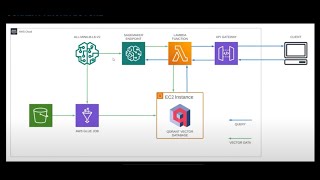
High-Performance Entity Matching Solution Using Vector Embeddings and AWS
Discover how to build a high-performance hotel matching system using vector embeddings, AWS infrastructure, and Qdrant for efficient data processing and improved accuracy in the travel industry.
Building a Semantic Search App for Music Using Qdrant Cloud
Learn to develop a semantic search application using Qdrant Cloud's Python SDK to efficiently search through thousands of songs across different music genres.
Natural Language Processing with Qdrant for Vector Similarity Search
Master vector similarity search using Qdrant to create embeddings from text data, perform contextual searches, and build recommendation systems for enhanced natural language processing applications.
Getting Started with Qdrant - Introduction to Vector Database and Similarity Search
Master vector similarity search using Qdrant to build semantic search and recommendation systems through hands-on practice with sample datasets and practical implementations.
Qdrant Vector Database and Search Engine Implementation in Rust
Dive into vector database technology with Qdrant, exploring its architecture, implementation in Rust, and applications in similarity search, matching, and recommendations systems.
Embeddings and Similarity Search with Qdrant Vector Database
Explore vector embeddings and similarity search concepts through hands-on demonstrations using Qdrant database, with practical examples for implementing efficient search solutions.
AI on the Edge with Eclipse Kura - From Data Collection to Model Deployment
Discover how to build and deploy machine learning applications on edge devices using Eclipse Kura, from data collection through Kura Wires to model training and inference with Nvidia Triton Server.