Stability and Performance Optimization Practices of HBase at Xiaomi
Discover key stability and performance optimization techniques for HBase systems, drawing from real-world implementations at Xiaomi's large-scale infrastructure.
Python Physics - Modeling Motion of a Porsche on Quarter Mile Track
Explore Python-based physics modeling to simulate a Porsche 911's quarter-mile acceleration, using real data to analyze power, friction, and motion dynamics.
Serverless Scaling with BigQuery - Overview, Architecture and Real-World Applications
Discover BigQuery's enterprise data warehouse capabilities, from its serverless architecture to real-time streaming, machine learning integration, and practical marketing applications.
Unlocking Financial Data with Real-Time Pipelines Using Apache Technologies
Discover how to build powerful real-time data pipelines using Apache Flink, NiFi, Kafka, and Iceberg for processing financial data efficiently, enabling swift decision-making and regulatory compliance.
QuestDB - Building Blocks of a Fast Open-Source Time-Series Database
Dive into the architecture of QuestDB and discover how this open-source time-series database achieves high-speed performance through specialized timestamp handling, efficient data ingestion, and SQL extensions.
DuckDB: Features, Architecture, and Use Cases in Analytics
Dive into DuckDB's powerful analytics capabilities, architecture, and key features while exploring its unique syntax, connectors, and practical use cases in modern data analysis.
Unlocking Advanced Log Analytics With ClickHouse and Kafka
Discover how to build a scalable, cost-effective log analytics solution using ClickHouse and Kafka. Learn JSON handling, data compression, and materialized views for processing billions of log events efficiently.
Building a Fully-Managed OSS-Compatible Lakehouse with BigLake Managed Tables
Discover how BigLake Managed Tables enhances open lakehouse formats by combining BigQuery infrastructure with OSS compatibility for improved data management, access control, and high-throughput streaming.
Introduction to DuckDB: An In-Process Analytical Database Management System
Discover DuckDB's powerful analytical database system, featuring in-process execution, multi-language support, and efficient data processing capabilities for handling large datasets on a single laptop.
Reinventing Kafka in the Data Streaming Era
Explore Apache Kafka's evolution in modern data streaming, from core architecture to cloud-native innovations and exactly-once semantics for real-time enterprise applications.
Apache Airflow 2.x - Modern Workflow Orchestration Features and Improvements
Discover the modern evolution of Apache Airflow 2.x, exploring new UI features, orchestration methods, and testing capabilities while maintaining backward compatibility for workflow management.
The Future of Analytics is Open Source and Cloud Native
Explore how cloud-native technology and open-source solutions are reshaping modern analytics platforms, driving innovation and enabling flexible data applications.
Optimizing Content Delivery Networks Through Simulations
Discover how to optimize CDN performance through modular simulation techniques, exploring configuration variations and real-world trace analysis for faster, more efficient system development and testing.
From Zero to Superset Hero - Data Visualization as Code with Terraform
Master data visualization automation with Terraform and Superset, learning to streamline dashboard creation, metric management, and chart configurations for enhanced efficiency at scale.
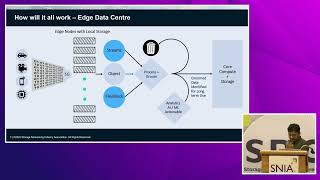
Cloud Native Storage Services for Edge Computing - Understanding Data Sources and Architectures
Explore cloud-native storage architectures for edge computing, covering data types, storage services, and operating models across far edge, enterprise edge, and network edge environments.
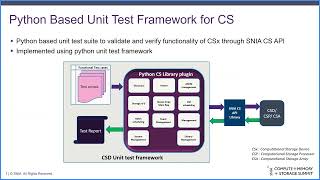
Python Interface for Computational Storage Devices - Implementation and Use Cases
Explore Samsung's Python library framework for computational storage, enabling efficient data processing with SmartSSD and demonstrating real-world applications like geo-location using PostgreSQL.
AWS EMR Demystified - Part 3
Master AWS EMR's integration with Glue, Athena, and PySpark while learning essential data transformation techniques and architectural considerations for optimizing your data lake implementation.
AWS EMR, Hadoop, and Data Lake Architecture - Part 2
Master AWS EMR's core components, including networking, storage types, and integration with AWS Glue and Athena. Learn to execute PySpark jobs and understand data transformation challenges in EMR-based data lakes.
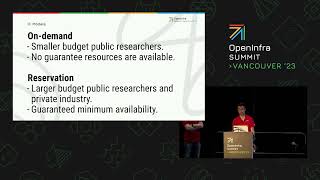
One Nova Cluster to Serve Multiple Computing Needs - Managing On-Demand and Dedicated Instances
Discover how San Diego Supercomputer Center efficiently manages a unified nova cluster serving diverse user needs, from on-demand instances to dedicated hosts, using OpenStack, Ceph, and custom Python solutions.
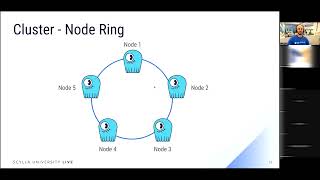
Filtering and Denormalizing Data in NoSQL Databases
Master data denormalization techniques in NoSQL databases, exploring materialized views, indexing strategies, and filtering options for optimal database performance and efficiency.
A Journey of Audit Logs from Kafka to Elasticsearch - Building a Centralized Logging Platform
Discover how to build a scalable audit logging platform using Kafka and OpenSearch, focusing on tracking data modifications across multiple users and data models in business-critical systems.