
Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB: A powerful database system integrating seamlessly with Python, offering efficient data processing and easy-to-use SQL capabilities for data scientists and analysts.

Speed is Not All You Need for Data Processing
Exploring data processing frameworks beyond Pandas, challenging assumptions about speed, and emphasizing practical considerations for choosing tools that best serve data practitioners.
Thinking in Parallel
Learn techniques for parallel programming in Java, including array programming and stream operations, to create efficient and easily parallelizable code from Java experts Stuart Marks and Brian Goetz.
The Pipes Library - How Plumbing Can Make Your Code More Expressive
Discover pipes, a powerful approach to writing expressive code for collection operations. Learn to efficiently transform, filter, and manipulate data with improved flexibility and composability compared to traditional methods.
Hyper Speed - When Big Data Blooms
Explore high-speed data processing techniques, focusing on Bloom Filters for efficient handling of massive data volumes in web security and content delivery applications.
Hyper Speed - When Big Data Blooms
Explore high-speed data processing techniques, including Bloom Filters, to handle massive volumes of telemetry data efficiently. Learn infrastructure strategies for processing 65,000 JSON payloads per second.
Calculating the Value of Pie - Real-Time Survey Analysis With Apache Kafka
Learn to create real-time survey bots using Apache Kafka® and ksqlDB. Explore data processing, schema usage, and Kafka architecture while building an interactive Telegram bot for pastry preference polling.
Deep Dive into Delta Lake and UniForm on Databricks
Explore Delta Lake's architecture, innovations, and use cases for reliable data lake management. Learn how it enhances performance, governance, and quality across various industries.
Open the Paths - Translating Experiences to Data
Explore innovative methods for converting real-world experiences into meaningful data, enhancing decision-making and problem-solving across various fields and industries.
Master Power Query M Code and Data Shaping for Data Analysis
Master Power Query M Code for advanced data shaping and analysis. Learn M Code values, expressions, data types, operations, custom functions, and key functions like Table.AddColumn and Table.Group.
Fall in Love with Data Transformation - Using DBT for Effective Data Workflows
Master data transformation with DBT, exploring its integration with SQL and Python. Learn fundamental use cases and workflows to streamline data processes and enhance efficiency in modern data engineering practices.
Towards Unified Compute Engines - Opportunities and Challenges
Explore the future of unified compute engines through an in-depth analysis of opportunities, challenges, and architectural innovations in modern database systems.
Building a High-Performance Real-Time Analytics Database with Apache Kafka and Druid
Master building a real-time analytics database using Apache ecosystem tools including Kafka, Druid, and Superset. Learn data streaming, processing, and containerization with hands-on implementation.
Building a Production Grade Document Understanding System with LLMs
Discover how to build scalable document understanding systems using LLMs, Metaflow, and open-source tools for efficient text processing and pattern recognition in production environments.
Visualization for Data Science - Filtering, Aggregation, and Clustering
Master data visualization techniques through filtering, aggregation, and interactive queries, exploring real-world applications like gerrymandering analysis and clustering methods including K-means and DBScan.
Building Your First Petabyte-Scale Architecture - Part 1
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
Building Your First Petabyte-Scale Architecture - Part 2
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
Building Your First Petabyte-Scale Architecture - Part 3
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
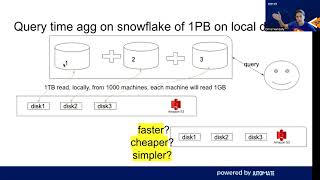
Building Your First Petabyte-Scale Architecture - Part 4
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
Importing Data from CSV Files
Explore techniques for importing data from CSV files, covering parsing methods, error handling, and efficient data processing in C++.
Python 101 - Introduction to Python for Data Science
Learn Python basics for data science: explore versatile programming tools, efficient data computation, and knowledge extraction techniques.