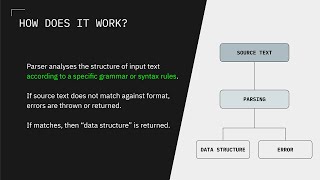
Comparing Libraries to Parse JSON Data in C++
Explore the fastest and simplest C++ libraries for parsing JSON data, comparing their performance and ease of use for efficient data handling in various applications.
Throwing Tools at C++ Ranges - Runtime Performance and Memory Usage Analysis
Explore C++ Ranges with tools for deep analysis, focusing on runtime performance and memory usage. Gain insights through practical examples and tool demonstrations.
Introduction to Apache Kafka - Core Concepts and Use Cases
Explore Apache Kafka's fundamentals, history, key concepts, and real-world applications. Learn how to deploy and manage Kafka using Canonical's Charmed Kafka solution.
A Data Lake on Your Cloud with Spark, Kubernetes and OpenStack
Explore data lake architecture using Spark, Kubernetes, and OpenStack for flexible, scalable, and cost-effective large-scale data processing on private cloud platforms.
Preparing Fineweb - A Finely Cleaned Common Crawl Dataset for Language Models
Explore Common Crawl data processing, comparing datasets like C4 and RefinedWeb. Learn about quality filters, deduplication strategies, and LLM-assisted filtering for creating high-quality datasets like Fineweb Edu.
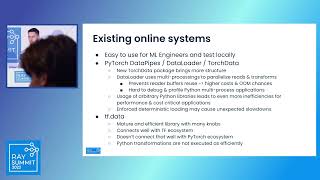
Cruise.data - A New Dataset Processing Pipeline for Cruise ML
Explore Cruise.data, a novel ML data pre-processing framework combining tf.data, PyTorch, and large-scale processing capabilities for efficient and scalable dataset handling in autonomous vehicle development.
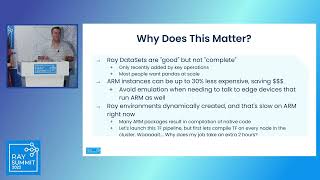
A Cross-Platform, Cross-Tool Ray on Kubernetes Deployment
Deploy Ray, Spark, Dask, and Jupyter on mixed-architecture Kubernetes clusters. Learn cross-building containers, handling Ubuntu versions, and glibc versioning for heterogeneous Ray clusters.
A Cloud-Native Parallel Data Processing Application in Julia
Explore cloud-native parallel data processing in Julia, covering design, debugging, and profiling techniques for high-performance applications. Learn AWS integration, containerization, and performance optimization strategies.
How to Increase the Throughput of Kubernetes Scheduler by Tens of Times
Explore advanced techniques to significantly boost Kubernetes scheduler performance, including algorithm optimization, parallel computation, and batch scheduling for improved cluster scalability and resource utilization.
Become a Power Query Master in Excel in Less Than One Hour
Master Power Query in Excel: Learn to gather, clean, and transform data efficiently. Streamline your workflow, automate tasks, and optimize data preparation for analysis.
Exploring Anomalies in Authentication Logs with Autoencoders
Discover how autoencoders can enhance cybersecurity by detecting anomalies in authentication logs, overcoming limitations of traditional rule-based models and improving threat detection capabilities.
From Excel to Real-Time Insights Using Databricks, ThoughtSpot and Power BI
Transforme relatórios estáticos em insights em tempo real usando Databricks, ThoughtSpot e Power BI. Aprenda a construir uma plataforma de análise avançada para capacitar gerentes e analistas com dados atualizados.
A Practical Introduction to Machine Learning with Databricks Mosaic AI
Explore Databricks' real-time inference capabilities for AI models, featuring strategies for deploying APIs and leveraging feature serving for instant data processing and decision-making.
Building a Multi-Petabyte Data Platform on Delta Lake at Zalando
Zalando's journey transforming multi-petabyte data platforms: challenges, strategies, and lessons learned in migrating to modern data-mesh architectures using Databricks and AWS ecosystems.
Building File-Based Applications with Unity Catalog Volumes
Discover Unity Catalog Volumes for managing diverse data formats, enabling scalable file-based applications with unified governance and versatile APIs for AI and ingestion use cases.
Designing a Copilot for Data Transformation with Spark and SQL
Explore the design of an AI copilot for data transformation, focusing on unique challenges and solutions to enhance productivity. Includes demos and insights on LLM applications in programming.
Architecture Explained: Generative AI-Based Complex Data Processing
Explore interoperability between Databricks and AWS for generative AI, covering intelligent document processing, real-time and batch processing patterns, and a live demo of end-to-end offerings.
What's Next for the Upcoming Apache Spark 4.0
Explore key enhancements in Apache Spark 4.0: Spark Connect, Structured Logging, PySpark updates, expanded SQL capabilities, improved connectivity, and real-time data processing advancements for optimized analytics.
Driving Transformative Analytics with Domo's Integration in Databricks
Explore the synergy between Domo and Databricks, unlocking data interoperability and accelerating business intelligence through scalable data processing and AI/ML capabilities.

Filter Variables with Python - Python Part 15
Learn to filter variables in Python, covering names, ages, phone numbers, and email addresses. Understand the importance of filtering and explore alternatives like RegEx.

Pandas and Dask DataFrame 2.0 - Comparison to Spark, DuckDB and Polars
Explore Dask DataFrame 2.0's improvements, comparing its performance to Spark, DuckDB, and Polars using TPC-H benchmarks. Learn about new features enhancing speed, efficiency, and usability in big data processing.