Large-Scale Distributed Processing in Google Cloud - 7 Lessons
Explore large-scale distributed processing challenges in Google Cloud, learn monitoring techniques, and discover solutions for efficient big data handling through real-world examples.
Online Machine Learning Based on Kafka Streams - Pollution Prediction System
Explore a system predicting pollution levels using Kafka Streams, based on historical and current weather data. Learn from WorldRemit's open-source project for practical machine learning applications.
Event Streaming for the Best of All Worlds
Explore event streaming's potential to revolutionize data processing and integration across diverse systems, enhancing real-time decision-making and operational efficiency.
OpenLineage: An Open Standard for Data Lineage
Explore OpenLineage, an open framework for data lineage metadata collection. Learn its purpose, data model, and integration with tools like Apache Airflow and Spark to enhance pipeline understanding and management.
Building a Lakehouse on the Microsoft Intelligent Data Platform
Explore Lakehouse architecture on Microsoft Intelligent Data Platform. Learn Synapse Analytics, Delta format, and Spark-based engines for efficient big data processing and analytics.
Driving Alerts and Actions on Your Data Using Microsoft Fabric's Data Activator
Learn to drive actions on data using the new Data Activator experience in Microsoft Fabric. Discover how to create alerts and automate responses based on real-time data insights.
Load Testing Fabric: Determining Hold Capacity for Large Datasets
Discover techniques for testing Fabric's capacity to handle large-scale data processing, from ingestion to PowerBI visualization, for enterprise-level workloads.
Roche's Maxim of Data Transformation - By Example
Explore Roche's Maxim through practical examples, learning to optimize data transformation processes for improved efficiency and effectiveness in data management.
New Features in Power Query for Power BI, Fabric, and Excel
Discover the latest Power Query features in Power BI Desktop, Fabric Dataflows, and Excel, enhancing data transformation capabilities.
Data Quality Revolution: The Fabric-OpenAI Approach
Master data cleaning techniques using Fabric and OpenAI to transform chaotic datasets into valuable insights, enhancing your data quality skills for improved analysis and decision-making.
Apache Flink for Sales Analytics - End-to-End Data Engineering Project
Develop an end-to-end sales analytics project using Apache Flink. Learn data ingestion, processing, complex transformations, and custom output formats for big data processing.
Building a Real-Time AI Data Platform with Apache Kafka
Explore building a real-time AI data platform using Apache Kafka, focusing on migrating from batch to stream processing without stateful components. Learn about Forecasty.ai's journey and innovative solutions.
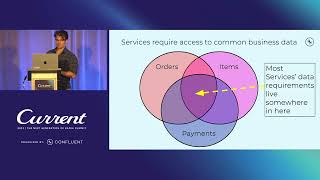
Off-Label Data Mesh - A Prescription for Healthier Data
Explore data mesh application beyond analytics, using event streams for real-time and batch operations. Learn practical guidelines, overcome hurdles, and implement a minimally viable data mesh for improved data management.
Side Effects: The Hidden Complexity in Software Development
Explore how side effects impact software complexity and learn industry solutions. Discover connections between microservices, immutable data, functional languages, and event streaming in tackling this fundamental problem.

Tutorial DuckDB: La Base de Datos Rápida y Ligera para Analítica, ETL, Scripting y Microservicios
Explora DuckDB, una base de datos veloz y liviana para análisis, ETL, scripting y microservicios. Aprende sus ventajas y aplicaciones prácticas.
Pandas and Dask DataFrame 2.0 - Comparison to Spark, DuckDB and Polars
Explore Dask DataFrame 2.0's improvements and performance compared to Spark, DuckDB, and Polars. Learn about new features, benchmarks, and future developments in distributed computing with Python.
Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB's integration with Python for efficient data processing, combining SQL and dataframe capabilities to handle large datasets with ease and speed.
The End of History? Convergence of Batch and Realtime Data Technologies
Explore hybrid approaches like Lambda and Kappa architectures for combining batch and real-time systems. Learn about SaaS platforms and managed services that simplify implementation of these powerful data technologies.
When to Move from Batch to Streaming and How to Do It Without Hiring an Entirely New Team
Demystify the transition from batch to real-time processing. Learn arguments, architectures, pitfalls, and open-source tools for stream processing without overhauling your team.
Ten Years of Building Open Source Standards in Data Engineering
Explore a decade of open-source standards development, from Parquet to Arrow. Gain insights into community-driven innovation and the evolving landscape of data engineering.
Building a Unified Feature Platform with DuckDB and Arrow
Explore ML feature platform development using DuckDB and Arrow. Learn scaling strategies, DuckDB extension implementation, DeltaLake interoperability, and performance comparison with Spark.