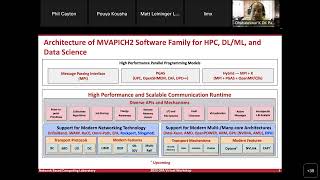
High Performance Scalable Support for Big Data Stacks with MPI - Leveraging MPI4Spark and MPI4Dask
Discover how MPI4Spark and MPI4Dask enhance big data frameworks by leveraging high-speed networks and HPC systems for improved performance and scalability in distributed computing environments.
Time Series Analytics with Apache Arrow, Pandas and Parquet - A Beginner's Guide
Discover how to build high-performance time series analytics applications using Apache Arrow Flight, Parquet, and Pandas, focusing on efficient data processing and querying techniques for columnar databases.
Azure OpenAI Deployment Types and Resiliency - Understanding Models, Capacity, and High Availability
Master Azure OpenAI deployment strategies, focusing on types, resiliency patterns, capacity management, and high availability considerations for optimal service implementation.

Introduction to Data Build Tool (DBT) - Features and Project Creation
Master data transformation techniques with DBT (Data Build Tool) to effectively analyze and engineer warehouse data through hands-on project creation and fundamental features.
DocETL: AI Agents for Complex Document Processing and Data Transformation
Discover how DocETL framework leverages AI agents and LLMs to transform complex document processing, featuring innovative operators and optimization techniques for enhanced data extraction and analysis.

Accelerating Near Real-time Analytics with High Performance Object Storage
Discover how computational storage enhances object storage applications through in-situ processing, improving system performance, reducing data movement, and enabling efficient real-time analytics in disaggregated environments.
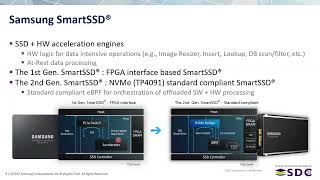
RETINA: Exploring Computational Storage with SmartSSD for Key-Value Storage and Deep Learning
Discover how Computational Storage and Samsung SmartSSD accelerate key-value storage engines and deep learning workloads through RETINA's cross-layered approach to near-data processing and performance optimization.

Envisioning a Computational Storage Architecture with SDXI Data Mover - Early Efforts
Explore the integration of SDXI data mover technology with Computational Storage architectures, focusing on efficient data movement and host offloading strategies for enhanced storage performance.
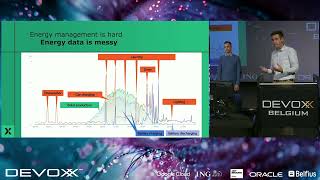
Outsmarting the Energy Grid with AI
Discover how AWS Lambda powers AI-driven household energy management, optimizing schedules based on real-time data, pricing, and forecasts for efficient, cost-effective solutions.
Filling the Core Language Gaps - Proposed New Primitives in APL
Explore three proposed APL primitives enhancing function composition, generalization, and indexing, completing the language's core functionality.
Network Observability at LinkedIn - Scaling Flow Data Processing with Erlang
Explore LinkedIn's Erlang-based network observability system for processing millions of data points per second, addressing scalability challenges in large-scale infrastructure.
Build ML-Enhanced Event Streaming Apps with Python Microservices - Conf42 Python 2023
Develop ML-enhanced event streaming applications using Python microservices, exploring real-time data processing and machine learning integration.
A Gentle Introduction to Vector Databases
Explore vector databases, semantic search, and machine learning models for unstructured data processing. Learn about Weaviate and see a practical demo of vector search in action.
Working with Relational Databases in the Wolfram Language
Explore relational databases using Wolfram Language's Entity framework. Learn key concepts, querying techniques, and advanced features for efficient data management.

Working with BigQuery and DataForm - Streamlining Data Management and Transformation
Streamline data management with BigQuery and DataForm. Learn setup, optimization, and automation for efficient, scalable data pipelines and transformations.
Building a Scalable Search Engine for Consumer Needs
Explore the creation of a scalable search engine using online machine learning systems for improved consumer experience and intent matching.
Data Preprocessing and Feature Engineering for Machine Learning
Master data preprocessing and feature engineering techniques for effective machine learning. Explore imputation, encoding, transformations, and more to maximize value from your data and improve model performance.
Reproducible ML Experimentation with Rubicon-ML
Explore reproducible ML experimentation using rubicon-ml, an open-source Python library for capturing and storing model training information in a searchable way, ensuring full reproducibility and audit-ability.
Deploying Transformers at Scale - Addressing Challenges and Increasing Performance
Explore challenges and solutions for deploying large-scale Transformer networks, focusing on improving latency, throughput, and cost-effectiveness for processing massive datasets.
Overcoming the Cold Start Problem: How to Make New Tasks Tractable
Explore strategies to overcome the cold start problem in AI, focusing on data aggregation and leveraging pre-trained models for efficient scaling of machine learning applications.
From Built-in Concurrency Primitives to Large Scale Distributed Computing
Explore asynchronous execution in Python, from basic concurrency to distributed systems. Master Future and Executor interfaces, asyncio, and frameworks like Dask for efficient large-scale data processing.