OmniCache: Collaborative Caching for Near-storage Accelerators
Innovative caching design for near-storage accelerators, combining host and device capabilities to enhance I/O and data processing performance through collaborative caching and dynamic offloading.
LoRAX - Serving Thousands of Fine-Tuned LLMs on a Single GPU
Explore LoRAX, an innovative LLM inference system enabling efficient serving of multiple fine-tuned models on a single GPU. Learn about dynamic adapter loading, heterogeneous batching, and scheduling techniques.

GPT-4 Vision and Speech Code Examples
Explore GPT-4's vision and speech capabilities through practical code examples, including video narration, website analysis, and creative storytelling using AI-generated content.
Leveraging LLMs for Enterprise Data Management - Strategies and Applications
Explore essential LLM strategies for non-public data applications, including prompt engineering, fine-tuning, and Retrieval Augmented Generation. Learn to transform enterprise data processes with practical techniques and real-world examples.
Batch Processing Tekton Pipelines in OpenShift
Explore Tekton for batch processing pipelines in OpenShift, covering design, implementation, and best practices with real-world examples from Red Hat's insights data processing.
LLMOps: Using Nvidia TensorRT SDK for GPU Inference
Optimize GPU inference using Nvidia TensorRT SDK. Convert models, compare throughput, and explore batch sizes, data precision, and runtime options for enhanced performance.
Building Your Own Bot with GPT: Harnessing the Power of AI - GeeCON 2023
Harness OpenAI's GPT to build a personalized chatbot. Learn API integration, custom dataset creation, and strategies for enhancing bot performance with individual data.
Enhancing Flexibility and Productivity with Access Patterns and Storage-Agnostic Abstractions
Explore a platform bridging data management gaps, offering storage-agnostic abstractions and ACID guarantees across streaming, batch, and random-access storages for flexible, consistent data handling.
Refactoring Organizations - Maximizing Team Productivity and Delivery Quality
Explore proven engineering methodologies to maximize team autonomy, align business boundaries, and boost productivity in product development and data processing.
The End of the Data Ice Age - Hot and Cold Data States in Modern Computing
Explore the evolution of data states in computing, examining hot and cold data paradigms and their impact on software development. Discover potential future directions for data management.
An Overview of Deep Learning Frameworks and Introduction to PyTorch
Explore deep learning frameworks, focusing on PyTorch. Learn about research workflows, data processing, and model building from Facebook AI researcher Soumith Chintala.
Machinery Fault Diagnosis Based on Deep Learning for Time Series Analysis and Knowledge Graphs
Explore deep learning techniques for machinery fault diagnosis using time series analysis and knowledge graphs. Learn data processing, model validation, and ontology modeling for industrial applications.
Streaming Aggregation on Cloud Scale Telemetry
Explore streaming aggregation techniques for cloud-scale telemetry, enhancing system observability and performance monitoring in large-scale distributed environments.
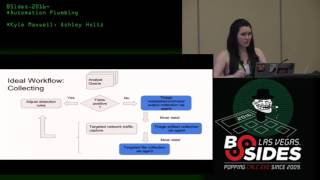
Automation Plumbing
Explore efficient automation workflows for cybersecurity, covering detection, aggregation, processing, and plumbing solutions using tools like Python, Elastic Search, Splunk, and Log Stash.
Python and Machine Learning
Explore machine learning for malware categorization using Python and scikit-learn. Learn to transform data, apply clustering algorithms, and generate YARA rules for effective malware hunting.
Meander - Declarative Explorations at the Limits of FP
Explore declarative data manipulation in functional programming using Meander, a Clojure library inspired by logic programming and term rewriting for complex data transformations.
Riding the Stream Processing Wave
Explore LinkedIn's stream processing challenges, innovations in machine learning applications, and advancements in nearline processing. Learn about state management and offline-online convergence in large-scale data systems.
Specter - Overcome Your Fear of Nested Clojure Data
Discover Specter, a library simplifying manipulation of nested data structures in Clojure. Learn to efficiently query and transform complex data, enhancing code readability and performance.
Glasfasernetze & Beton wie auch immer das zusammen passt
Entdecken Sie die Anforderungen und Herausforderungen beim Aufbau und Betrieb von Rechenzentren, von der Kellerinstallation bis zum Full-Size-Datacenter, inklusive Sicherheit, Stromversorgung und Kühlung.
Data Transforming Your Sewage into Signatures
Transforming honeypot data into valuable security insights through innovative data analysis techniques. Learn to extract meaningful patterns and create effective signatures from seemingly useless information.
Detecting Malware Even When It Is Encrypted
Innovative machine learning approach for detecting malware in encrypted HTTPS traffic using Bro IDS logs, without decryption. Focuses on behavioral features and connection 4-tuples for improved accuracy.