Enabling Cloud Workloads with the WEKA Data Platform
Discover how the WEKA Data Platform transforms data silos into dynamic pipelines, optimizing GPU performance and streamlining AI, ML, and HPC workloads in modern cloud environments.
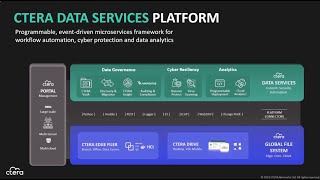
Empowering Cloud Data with CTERA Data Services - Creating Custom Data Pipeline Workflows
Discover how to leverage global file systems for seamless cloud data management, create custom data pipelines, and implement analytics workflows using CTERA's advanced data services platform.
Telemetry Data Understanding and Optimization for Cost-Effective Observability with Mezmo
Discover how to effectively manage and optimize telemetry data pipelines for enhanced observability, cost control, and faster incident response in enterprise systems.
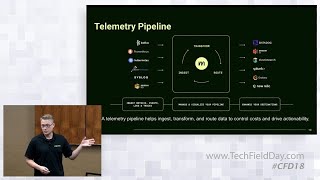
Understand and Optimize Logs, Metrics, Traces, and Events with the Mezmo Telemetry Pipeline
Master telemetry data optimization techniques for DevOps and SREs, covering data profiling, signal isolation, and dynamic pipelines to enhance observability platform performance and reduce costs.
Optimizing High Density Storage for AI and ML Applications
Discover how to optimize high-density storage systems for AI/ML workloads, focusing on data pipelines, GPU utilization, and efficient solid-state storage solutions for large-scale models.
Better Together - Unleashing the Synergy of Pandas, Polars, and Apache Arrow
Discover how to optimize data engineering workflows by combining Pandas and Polars with Apache Arrow, learning techniques to build faster, more efficient data pipelines for scalable solutions.
지하철 혼잡도: 실시간 데이터 수집부터 분석까지
실시간 지하철 혼잡도 서비스의 데이터 수집, 분석, 처리 과정을 탐구하며 실시간 데이터 처리 시스템의 구조와 구현 방법을 심층적으로 이해합니다.
Building Mobility Data Platform with EMR and Airflow
Discover how to build and optimize a mobility data platform using AWS EMR and Airflow, focusing on migration strategies, cost optimization, and infrastructure automation with Terraform.
Managed Airflow Service Vane Development Journey
Dive into the development journey of Vane, a managed Airflow SaaS platform, exploring its architecture, implementation challenges, and valuable insights gained from operating data platforms at scale.
Modern Industrial Data Platform - Technical Deep Dive
Dive into SKT's innovative approach to modern industrial data platforms, exploring on-demand data mesh architecture and active metadata management for enhanced data pipeline efficiency.
On-Premise Kubernetes and Airflow ETL Platform (Haflow) - Introduction and Implementation
Discover SK하이닉스의 클라우드 네이티브 ETL 플랫폼 Haflow의 구축 사례와 아키텍처를 통해 기존 ETL 솔루션의 한계 극복 방안과 리소스 최적화 전략을 파악하세요.
Dyalog and Apache Kafka Integration - True?
Explore Apache Kafka's potential with Dyalog APL, learning about distributed event streaming, real-time data pipelines, and practical implementation examples.
Designing Streaming Data Pipelines: Best Practices - Cloud Native 2024
Explore best practices for designing streaming data pipelines, covering key concepts, challenges, and considerations for scalability in cloud-native environments.
4 Tricks to Leverage Your Airflow Pipelines
Discover four powerful techniques to enhance Airflow pipelines: CSV-based DAG creation, sharable config utilization, entity-based autogeneration, and event-driven implementation.
Best Practices to Manage AWS Streaming Data Pipeline at Scale
Learn best practices for managing AWS streaming data pipelines at scale, covering data distribution, large record processing, schema registry, and validations.
Building a Modern Enterprise Data Ecosystem on Cloud - Conf42 Cloud Native 2024
Explore modern enterprise data ecosystems on cloud platforms, covering storage, organization, consumption, pipelines, and machine learning. Learn key components and AWS challenges.
Adding Generative AI to Real-Time Streaming Pipelines - Conf42 LLMs 2024
Explore integrating generative AI into real-time streaming pipelines, covering enterprise use cases, model selection, and implementation using tools like NiFi, Flink SQL, and cloud services.
Leveraging the Apache Flight Go Client and InfluxDB for Time Series Data Management
Explore Apache Flight Go Client and InfluxDB integration for efficient time series data management in modern pipelines. Learn writing and querying data using the InfluxDB v3 Go client library.
Go Concurrency Powering Gigabyte-Scale Real-World Data Pipeline
Explore Go concurrency techniques for building high-performance data pipelines, focusing on MongoDB to RDBMS migration and optimizing worker pools for gigabyte-scale data processing.

No JVM, No Kafka: The Future of Streaming Data Pipelines
Explore the future of streaming data pipelines without JVM and Kafka, focusing on innovative approaches for efficient and scalable data processing in cloud-native environments.
Integrating Computer Vision and NLP for Smart Property Tagging
Discover how Computer Vision and NLP create 'smart tags' for efficient property searches, enhancing user experience and streamlining data processing in real estate.