Data Pipelines with Celery: Modular, Signal-Driven and Manageable
Explore efficient data pipeline design using Celery, Redis, and signal-based triggering. Learn to segment workflows, manage API limits, and optimize data processing for improved throughput and maintainability.
Modern Data Orchestration: Best Practices and Real-World Use Cases
Elevate your data pipeline game with real-world tricks and best practices. Explore patterns, avoid dependencies, and integrate fundamental concepts for efficient data orchestration.
Gatekeeping Data Quality with Apache Iceberg, Toree, and Airflow
Leverage Apache Iceberg, Toree, and Airflow for efficient data quality validation. Customize data audits with Jupyter notebooks and orchestrate workflows at scale using open-source Apache projects.
Top 10 Azure Data Factory Tips and Tricks for Speed, Cost, and Performance
Discover 10 essential Azure Data Factory tips to enhance performance, reduce costs, and streamline data integration solutions for improved efficiency.
AI-Driven Edge to Core Data Pipelines for Retail
Automate AI/ML model deployment in retail with an opinionated solution for continuous release cycles from edge to core data pipelines.
How Curing "Kafkatosis" Can Improve Your Stream Management and Governance
Learn to recognize and overcome "Kafkatosis" in Kafka environments. Discover strategies to optimize stream management, improve application onboarding, and enhance operational efficiency in diverse cloud and on-prem setups.
Operationalizing Pluralsight's Data with Materialize
Discover how Pluralsight leverages Materialize to replace complex streaming systems, enabling real-time analytics and applications through SQL-based materialized views for faster, cost-effective data operations.
From Edge to Cloud: Creating Data Pipelines Using Open-source with Strimzi on Kubernetes
Learn to create data pipelines from edge to cloud using open-source Strimzi on Kubernetes, enabling real-time data streaming across your organization.
Squeezing the Most From Your Kafka Infrastructure
Explore challenges and clever solutions for expanding Kafka infrastructure. Learn to optimize resources, streamline pipelines, and refocus on core business objectives as your system grows.
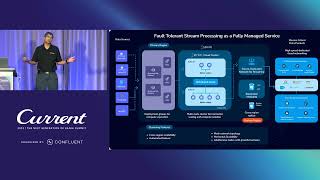
Striim: Unifying Change Data Capture, AI/ML, and Exactly-once Processing in a Managed Platform
Explore Striim's unified data streaming platform for rapid deployment of event stream pipelines, enabling real-time analytics and AI with built-in CDC and exactly-once processing.
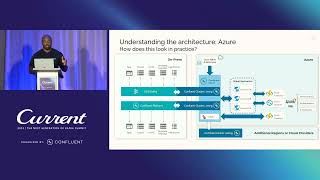
Unlocking Real-Time Data Insights: Leveraging Confluent Cloud on Azure
Leverage Confluent Cloud on Azure to build real-time data flows, capture changes instantly, and simplify data pipeline development. Boost productivity and innovate faster with streaming data pipelines and self-service access.
Continuous Data Pipeline for Real-Time Benchmarking and Data Set Augmentation
Generate datasets and real-time precision/recall splits to detect data shifts, prioritize data collection, and retrain models for improved ML system accuracy and performance.
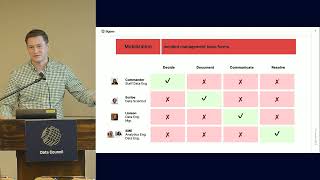
Incident Management for Data People
Learn how data teams can apply incident management practices to reduce disruptions in analytics and ML applications, improving pipeline reliability and data quality.
Building Scalable and Reliable Data Pipelines Using Debezium and Kafka
Explore building scalable, reliable data pipelines with Debezium and Kafka. Learn to capture real-time database changes, integrate with Kafka, and implement best practices for efficient data processing and distribution.
The Power of a Brownfield Mindset When Building Your Platforms
Explore techniques for building successful brownfield platforms, challenging the greenfield approach and leveraging existing systems to evolve efficient, consolidated capabilities.
What's Next for Data Engineers
Explore the future of data engineering and emerging trends in this concise overview from Google Cloud experts.
Building Next-Generation Data Pipelines with Containers - Fast Track to Modernization
Build efficient, scalable data pipelines using containers. Learn to leverage Cloud Run for streaming, batch, and on-demand data processing, enhancing your business's data management capabilities.
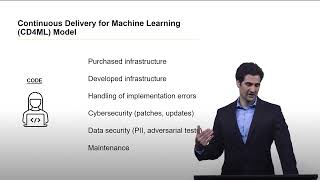
Introduction to ML Ops and Continuous Delivery for Machine Learning
Explore ML operations and the Continuous Delivery for Machine Learning Model in this concise introduction to MLOps.
Testing Data Pipelines - Techniques for Ensuring Data Flow Integrity
Explore effective techniques for testing data pipelines, ensuring smooth data flow and quick problem resolution. Learn about unit, integration, and end-to-end tests, plus unique methods like data snapshot testing.
Improve Your ML Projects - Embrace Reproducibility and Production Readiness with Kedro
Discover how Kedro framework enhances ML project management, focusing on reproducibility, flexibility, and production readiness. Learn to integrate Kedro for improved efficiency in Python-based projects.
Active Learning in Computer Vision
Discover techniques for creating active learning pipelines to leverage production data in training advanced computer vision models.