Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
From Idea to Model: Productionizing Data Pipelines with Apache Airflow
Learn to productionize data pipelines using Apache Airflow, bridging data science and engineering. Explore collaborative workflows, custom operators, and scalable solutions for efficient model deployment and iteration.
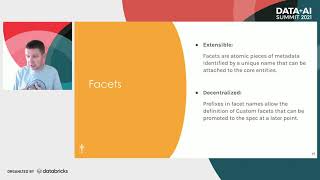
Observability for Data Pipelines with OpenLineage
Explore data pipeline observability using OpenLineage, enhancing reliability and auditability. Learn how metadata collection enables understanding of data flow and dependencies across teams and technologies.
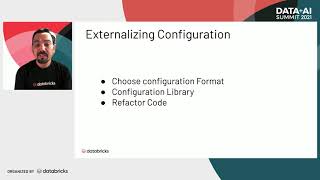
Dumb-Proofing Data Pipelines: Techniques for Configurable and Maintainable ETL - Databricks
Techniques to create configurable, maintainable data pipelines. Learn to externalize configurations, validate inputs, and leverage Scala features for robust, easily deployable ETL processes.
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
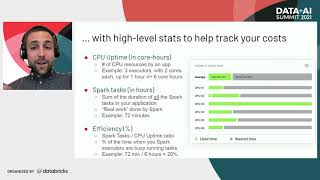
Delight - Improved Apache Spark UI for Performance Troubleshooting
Explore Delight, a free monitoring dashboard for Apache Spark. Learn to troubleshoot and optimize data engineering pipelines using system metrics and Spark information for improved performance and cost-effectiveness.
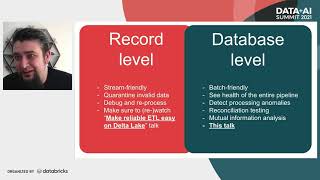
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
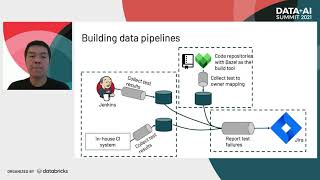
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Composable Data Processing with Apache Spark - Scaling Development and Error Handling
Learn about SIP, an extensible plugin framework for Apache Spark that enhances data processing efficiency, error handling, and scalability in Adobe's Experience Platform.
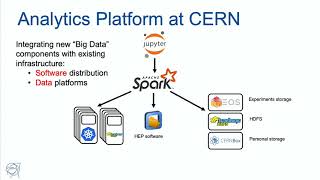
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
Best Practices for Building and Deploying Data Pipelines in Apache Spark
Learn best practices for building and deploying efficient, reproducible data pipelines in Apache Spark. Discover a toolkit that simplifies pipeline creation for non-engineers and explore deployment strategies.
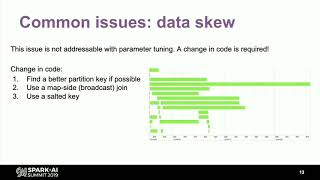
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
Best Practices for Building Robust Data Platforms with Apache Spark and Delta
Learn best practices for building robust data platforms using Apache Spark and Delta. Gain insights on optimizing performance, scaling, security, and cost-effectiveness in big data architectures from real-world experiences.
Generative Hyperloop Design - Managing Massively Scaled Simulations for Demand Modeling
Explore large-scale simulation framework for Hyperloop design, utilizing cloud computing, data pipelines, and machine learning to address key technical and business questions for safe and efficient mass transportation.
Real-Time Forecasting at Scale Using Delta Lake and Delta Caching
Explore real-time forecasting at scale using Delta Lake and Delta Caching. Learn efficient data sampling, storage, and caching techniques for handling massive datasets and achieving rapid forecast response times.
Building the Petcare Data Platform with Delta Lake and Spark ETL Pipeline
Explore Mars Petcare's data platform using Delta Lake and Spark ETL pipeline 'Kyte'. Learn about advantages over Azure Data Factory and leveraging Delta Lake for ETL configurations and data science.
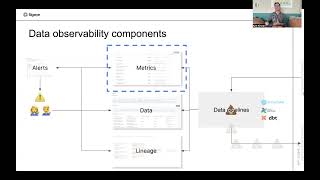
Reliable Pipelines and High Quality Data Without the Toil - Kyle Kirwan
Explore data observability's power in enhancing pipeline quality, reducing maintenance toil, and optimizing performance. Learn key components: metrics, data, lineage, and alerts for effective data management.
Fluentd - A Complete Logging Ecosystem for Kubernetes
Explore Fluentd's internals, best practices, SDKs, and sub-projects for efficient logging in cloud-native environments, with a focus on Kubernetes integration and operational challenges.
Orchestrating Data Assets Instead of Tasks, With Dagster - Sandy Ryza
Explore data orchestration with Dagster, focusing on managing data assets over tasks. Learn about pipeline development, testing, deployment, and monitoring in data engineering and machine learning.