Smart Data Pipelines to Azure - Ingesting and Migrating Data the DataOps Way
Explore StreamSets' DataOps platform for optimizing data ingestion and migration to Azure. Learn about smart data pipelines, integration with Azure services, and how to speed up cloud adoption using modern data engineering practices.
Building an Agentic Framework for Generative AI Applications
Discover how to build an agentic framework for GenAI applications, focusing on RAG-centric approaches, multilingual queries, and real-time data processing for enhanced customer assistance.
Cloud-Native Solutions and Practices for Clickstream Data Analysis
Construye un sistema de análisis de datos de flujo autónomo y rentable utilizando prácticas nativas de la nube y Apache Kafka para optimizar productos y potenciar el crecimiento empresarial.
The Challenges of Engineering Data Science
Explore the unique challenges and perspectives of engineering in data science through insights from industry experts.
Accelerating Data and AI with Spice.ai Open-Source Software
Discover how Spice.ai's open-source software accelerates data and AI development, exploring innovative approaches to streamline machine learning workflows and enhance database integration.
ETL with Meltano and Singer in the LLM Era
Explore how traditional ETL tools like Singer and Meltano can enhance data pipeline management for LLM applications, addressing production-level challenges beyond basic LangChain capabilities.
Real-Time Revolution: Kickstarting Your Journey in Streaming Data
Dive into stream processing fundamentals and learn to build real-time data applications using Python's Bytewax framework, debunking common misconceptions along the way.
Building a ChatGPT Data Pipeline with RisingWave Stream Processor and Astra Vector Search
Discover how to build real-time GenAI pipelines by combining RisingWave's stream processing with Astra's vector embedding and similarity search capabilities for ChatGPT applications.
The Real Modern Data Stack - Building ETL Pipelines with Open Source Tools
Discover how to build powerful, cost-effective ETL data stacks using open-source tools like sling, dbt, duckdb, and dagster - transforming months of implementation into rapid deployment.
ODSC West 2015 - Cloud Native Data Science
Cloud-native design principles for data science applications: creating scalable, stateless models easily deployable in modern cloud systems. Insights on open-source platforms and best practices.
Funnel Analysis with Apache Spark and Druid for Advertising Campaign Effectiveness
Learn to perform funnel analysis at scale using Apache Spark, Druid, and DataSketches. Discover techniques for measuring campaign effectiveness and analyzing user behavior in chronological order for large-scale advertising campaigns.
Introduction, Principles and Origin of Dagster
Introduction to Dagster: A data orchestrator for the entire application lifecycle. Covers principles, development, deployment, and monitoring. Includes demo and code snippets showcasing Dagit UI and Dagster programming model.
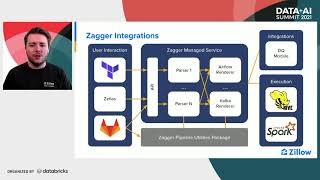
Empowering Developers with Self-Service ETL - Zillow's Approach
Zillow's self-service ETL solutions empower teams to build, maintain, and monitor data pipelines, abstracting complex processes and catering to diverse user needs while leveraging internal services for efficient implementation.
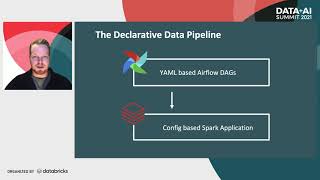
Code Once, Use Often - Declarative Data Pipelines
Learn to build efficient, reusable data pipelines using declarative approaches. Explore techniques for reducing food waste through data-driven solutions and automation in this developer-focused session.
Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
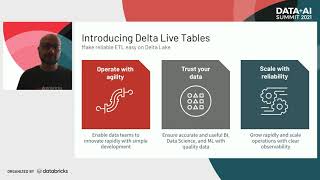
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
Getting Started with Apache Spark on Kubernetes
Learn to deploy and optimize Apache Spark on Kubernetes with hands-on demos, covering environment setup, application sizing, performance tuning, and monitoring for efficient data pipeline management.