Towards Unified Compute Engines - Opportunities and Challenges
Explore the future of unified compute engines through an in-depth analysis of opportunities, challenges, and architectural innovations in modern database systems.
The Critical Role of Storage in Optimizing AI Training Workloads
Explore how storage systems and AI frameworks interact during model training, focusing on data loading mechanisms, checkpointing, and storage solutions for optimizing AI workloads.
Personalized and Context-Aware Digital Nudging for Behavioral Change
Explore the science of digital nudging and how personalized, context-aware suggestions can effectively influence behavioral change while respecting ethical boundaries and user privacy.
Responsible Data Management - Ethics and Legal Compliance in Data-Driven Systems
Explore ethical considerations in data-driven systems, focusing on responsible data collection, preparation, and lifecycle management for building fair and interpretable AI solutions.
A Guide to Modern Data Stack - Building Efficient Data Infrastructure
Discover how to build and optimize a modern data stack with expert guidance on essential components, technologies, and best practices for efficient data management and analytics infrastructure.
From Zero to Data Hero - Take Raw Data to Curated Data in Under 90 Minutes
Discover how to efficiently manage, process, and clean data using low-code tools. Learn to connect Apache Spark, Databricks, and TimeXtender for rapid data curation and confident decision-making.
D-SOS: Dataset Shift with Outlier Scores
Explore a scalable two-sample test for dataset shift using outlier scores, focusing on low-density regions and comparing contamination rates across samples.
Clinical Informatics, AI, and Multi-modal Analyses in Healthcare - Grand Rounds 2/9/23
Explore AI, predictive biomarkers, and data integration in clinical informatics with Dr. Joel Saltz, discussing cutting-edge tools for investigators in biomedical research.
Redis, CockroachDB, Snowflake, MangoDB, and TabDB - Potpourri of Database Systems - Lecture 25
Explore Redis, CockroachDB, Snowflake, MangoDB, and TabDB in this comprehensive overview of modern database systems, covering their architectures, features, and use cases.
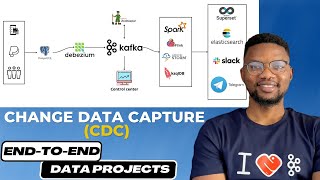
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Debezium - Building Streaming Data Pipelines with Change Data Capture
Explore Debezium's features for building streaming data pipelines using popular databases as sources, with a focus on Apache Kafka integration and alternative data sinks.
Top 6 Worst Apache Kafka JIRA Bugs
Explore six critical Apache Kafka bugs with expert Anna McDonald. Gain insights into batching, replication protocols, networking, and Scala implementation, enhancing your understanding of Kafka's inner workings.
Migrate Your Kafka Cluster with Minimal Downtime
Learn strategies and tools for migrating Kafka clusters with minimal downtime. Explore MirrorMaker, Confluent Replicator, and Cluster Linking. Gain insights on planning, execution, and overcoming challenges in Kafka migration.

Data Quality with Great Expectations
Master data validation techniques using Great Expectations to ensure high-quality inputs for AI/ML models, leading to more reliable and accurate results.
Designing for Forward Compatibility in Gen AI - MLOps Podcast
Explore forward compatibility in Gen AI, LLM deployment challenges, and practical solutions for securing and monitoring AI systems in production environments.
Data Governance and AI - Challenges and Opportunities in MLOps
Explore data governance, AI challenges, and MLOps with Alexandra Diem. Gain insights on balancing tech projects, agile methods, and integrating AI into workflows. Learn about specialized chatbots and data-driven problem-solving.
Managing Small Knowledge Graphs for Multi-agent Systems - MLOps Podcast #236
Explore knowledge graph management for multi-agent systems, focusing on structural grounding, selective improvement, and end-to-end reliability. Learn strategies to enhance RAG accuracy and repeatability in AI pipelines.
RAG Quality Starts with Data Quality - Enhancing Retrieval-Augmented Generation Systems
Explore data quality's crucial role in Retrieval-Augmented Generation (RAG) systems. Learn data prep essentials, overcome challenges, and enhance performance while ensuring privacy and governance in enterprise settings.
Research Ops - Challenges and Practical Solutions for Distributed Scientific Computing
Explore challenges and practical solutions for distributed scientific computing in research operations, focusing on advanced cyberinfrastructure.
Data Management from First Principles
Learn essential data management principles for research, including tools, metadata, and FAIR practices. Enhance project organization and efficiency.
Lab Notebooks for Computational Mathematics, Sciences and Engineering
Explore lab notebooks' adaptation to computational research, with examples addressing challenges in transitioning from experimental to computational sciences.