Data Quality Revolution: The Fabric-OpenAI Approach
Master data cleaning techniques using Fabric and OpenAI to transform chaotic datasets into valuable insights, enhancing your data quality skills for improved analysis and decision-making.
Decoupling with Event-Driven Architecture: Implementing Data Mesh Using Galapagos
Explore event-driven architecture with Galapagos, an open-source tool for Apache Kafka. Learn how to decouple teams, improve data management, and enhance business communication through event-driven thinking.
Building a Winning Data Engineering Culture
Learn to build a successful data engineering team and culture, empowering engineers and partners for efficient data systems and fruitful projects. Explore critical roles and strategies for data-driven decision-making success.
Approaching Kafka Replication at Scale - Go Big or Go Home
Explore scaling strategies for Kafka, including horizontal and vertical scaling, replication techniques, and routing events between clusters. Learn to overcome bottlenecks and manage large-scale data processing effectively.
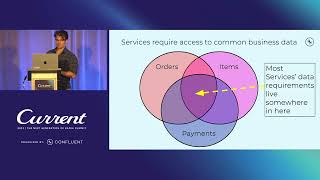
Off-Label Data Mesh - A Prescription for Healthier Data
Explore data mesh application beyond analytics, using event streams for real-time and batch operations. Learn practical guidelines, overcome hurdles, and implement a minimally viable data mesh for improved data management.
Configuring Kafka Connect for Scalability - Best Practices
Optimize Kafka Connect clusters for scalability. Learn best practices to configure and manage Kafka Connect effectively, ensuring successful integration of external systems with Apache Kafka at scale.
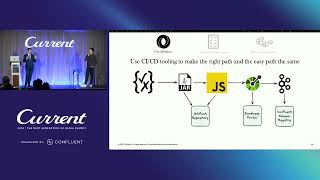
Beyond Monoliths: Thrivent's Lessons in Building a Modern Integration Architecture
Explore strategies for modernizing data architecture, from technical aspects like JSON Schema and OpenTelemetry to human factors like building trust and adopting a product-focused mindset.
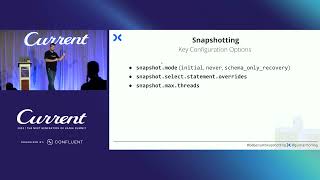
Debezium Snapshots Revisited - Incremental Snapshots for CDC Pipelines
Explore innovative incremental snapshot techniques for Debezium CDC connectors. Learn to pause, resume, and parallelize snapshots, and customize snapshot contents for efficient data pipeline management.
Dynamic Change Data Capture with Flink CDC and Consistent Hashing
Implement dynamic Change Data Capture for large databases using Flink CDC connectors and consistent hashing. Overcome challenges with incremental snapshotting and Postgres replication slots.
Analytics: The Final Data Frontier - Why Users Need Your Data and How Pinot Serves It
Explore Apache Pinot's real-time analytics capabilities for user-facing applications, leveraging streaming data from Apache Kafka to deliver rapid insights across diverse business domains.
10 Tips to Enable Data Discovery and Governance in Your Organization
Discover 10 essential tips for enhancing data discovery and governance in your organization, from establishing a common data language to implementing data contracts and fostering collaboration.
Implementando el Patrón CQRS con Debezium, PostgreSQL, Redis y Kafka
Aprende a implementar el patrón CQRS utilizando Debezium, PostgreSQL, Redis y Kafka para mejorar el rendimiento y la escalabilidad de tus aplicaciones Java con Spring Boot.

Tutorial DuckDB: La Base de Datos Rápida y Ligera para Analítica, ETL, Scripting y Microservicios
Explora DuckDB, una base de datos veloz y liviana para análisis, ETL, scripting y microservicios. Aprende sus ventajas y aplicaciones prácticas.
How CERN Serves 1EB of Data via FUSE - Kernel Recipes 2024
Explore CERN's data management strategies, including open-source projects and FUSE implementation, to handle massive datasets from LHC experiments and serve global scientific community.
Python and SQL: Better Together, Powered by DuckDB
Explore DuckDB's integration with Python for efficient data processing, combining SQL and dataframe capabilities to handle large datasets with ease and speed.
Top Excel Tips for Efficiency - Troubleshooting Common Errors
Master Excel error handling, data validation, and formula auditing to boost spreadsheet reliability and efficiency. Tackle common errors, protect data, and troubleshoot with confidence.
War Stories: Fighting the PostgreSQL Support Trenches
Dive into 20+ years of PostgreSQL support experiences, learning valuable lessons through entertaining anecdotes from the trenches.
Migration Validation Made Easy with Ora2Pg - PGConf NYC 2021
Explore Oracle to PostgreSQL migration validation using Ora2Pg. Learn schema and data validation techniques, object migration strategies, and best practices for successful database transitions.
The Very Hungry Transaction - Avoiding Dangerous Patterns in Database Transactions
Explore database transaction pitfalls and best practices to safeguard data integrity and application performance in Rails applications.
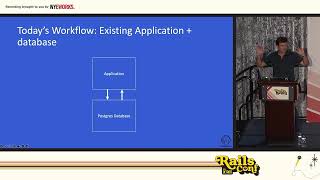
Using Postgres and OpenAI to Power Your AI Recommendation Engine - RailsConf 2024
Discover how to build and optimize an AI recommendation engine using Rails, Postgres, and OpenAI. Learn scaling techniques for handling unique AI data needs.
The Very Hungry Transaction - Avoiding Risky Database Patterns
Explore how database transactions grow into liabilities, uncover problematic patterns, and learn strategies to maintain data integrity and database health.