The Dangers of Dirty Data: Ensuring Accuracy in Classification
Explore the consequences of dirty data and learn practical techniques for ensuring data accuracy and maintenance in this insightful talk by Susan Walsh.
Exploring Stateful Microservices in a Cloud Native World
Discover how to architect stateful microservices in cloud-native systems using Open Liberty and MicroProfile, challenging conventional wisdom about stateless containers.
A Postgres Compatible DB on Kubernetes - YugabyteDB
Install and explore YugabyteDB, an open-source distributed SQL database compatible with PostgreSQL, on Kubernetes. Learn about data sharding, replication, and geo-distribution for high availability and low latency.
Dissecting Our Legacy - The Strangler Fig Pattern
Explore the Strangler Fig Pattern for modernizing legacy systems using Change Data Capture, connectors, and stream processing techniques.
Keep Your Cache Always Fresh with Debezium
Explore how to maintain synchronized read views in distributed caches using change data capture, Debezium, Apache Kafka, and Infinispan. Learn to create denormalized data views and implement cross-site replication for cache updates.
Event Sourcing With Event Store
Learn event sourcing with Event Store: implementation, challenges, and best practices for robust, scalable systems. Covers writing events, validation, migrations, and advanced topics.
Creating Event-Driven Microservices - The Why, How, and What
Explore event-driven microservices architecture, including key patterns, Apache Kafka's role, and practical implementation strategies for building scalable and resilient systems.
From Zero to Hero with Kafka Connect
Explore Kafka Connect's power in integrating data systems, from basics to advanced techniques for efficient and scalable data pipelines.
AI Use Cases - Adding and Maintaining Value
Explore AI use cases in business, focusing on identifying valuable opportunities, assessing potential impact, and considering long-term support and maturity for successful implementation.
In-Memory Data Revenge - The Substrate Between Apps and Data - An Infinispan Case
Explore in-memory data systems like Infinispan for efficient data handling, querying, and analysis. Learn about architectures and use cases to optimize app performance and data processing.
Semantic Event Sourcing - Case Study of Moving from CRUD to Log Based State Management
Explore log-based state management for robust, scalable data systems. Learn techniques for efficient multi-dimensional time series traversal and improved data utility, applicable beyond master data management.
Streaming ETL on the Shoulders of Giants
Explore configuration-based streaming ETL pipelines between MongoDB and Apache Kafka using Kafka Connect framework, focusing on data integration scenarios without coding.
Platform Building for Data Mesh - Show Me How It Is Done
Demystifying Data Mesh through practical platform building, focusing on components, patterns, and technologies for developing and reusing data products in cloud-native environments.
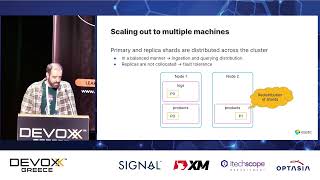
Finding Needles in Ever Increasing Haystacks - Scalability with Elasticsearch
Explore Elasticsearch's distributed architecture, efficiency, and resilience for modern data challenges. Learn about ingestion, sharding, replication, and search distribution techniques.
10 Things You Didn't Know Your Data Can Do for You
Discover 10 ways to maximize your data's potential, from simplifying infrastructure to automating workflows. Learn how modern applications can design, grow, and secure data while deriving insights and enhancing user experiences.
Data-Oriented Programming in Java
Explore data-oriented programming principles and pattern matching in Java for safe, powerful, and maintainable ad-hoc polymorphism. Compare with OOP to understand when to apply DOP effectively.
Introducing Elm to a JavaScript App
Learn techniques to incrementally introduce Elm to JavaScript projects, including interop, embedding Elm apps, using Elm for business logic, and integrating with React components.

Stream All Things - Patterns of Modern Data Integration
Explore modern data integration patterns, focusing on event streaming with Apache Kafka. Learn about microservices, compatibility, and innovative approaches to handling complex data challenges.
Inside TensorFlow- Building ML Infra
Explore research and engineering challenges in building machine learning infrastructure, focusing on TensorFlow runtime and optimization techniques for ML programs.
Reducing Complexity and Increasing Performance with Trino
Explore Trino's capabilities for efficient data querying across diverse sources, optimizing pipelines, and enhancing analytics performance in complex data environments.
Data Governance - A Data Scientist's Best Friend
Explore key aspects of data governance empowering data scientists to make informed decisions and extract value from datasets. Learn approaches fostering data trust and safeguarding against biases.