Redwood Storage Engine Update - FoundationDB's New B-Tree Based System
Explore FoundationDB's Redwood storage engine: features, performance, and future optimizations for improved I/O throughput and reduced disk footprint.
Hybrid Cloud Data Management Across Heterogeneous Storages
Explore strategies for managing data across diverse storage systems in hybrid cloud environments, focusing on challenges, solutions, and best practices for seamless integration and optimization.
Productionizing ML with ML Ops and Cloud AI
Explore ML Ops and Cloud AI for efficient machine learning productionization, covering key challenges, continuous deployment, performance optimization, and lifecycle management.
Lessons Learned: Adopting Node-RED for IoT Use Cases
Explore Node-RED for IoT: architecture, performance, integration, and practical applications. Learn from real-world examples and community insights to enhance your visual programming skills.
Apache Kafka and the Rise of the Streaming Platform
Explore streaming platforms with Apache Kafka as the core, revolutionizing data flow management. Learn how this technology acts as a central nervous system for modern digital businesses.
Pragmatic Cloud Security for InfoSec Practitioners - Track 201
Explore pragmatic cloud security strategies for InfoSec practitioners, covering encryption, service-based approaches, data management, and scalability in modern cloud environments.
The Very Hungry Transaction - Managing Growing Database Operations
Explore how database transactions can grow into liabilities, uncovering problematic patterns that risk data integrity and offering strategies to fix and prevent these issues.
PHP API Pro - Implementing API Pagination and Hypermedia
Learn to dynamically generate API hypermedia, implement pagination, and create a reusable factory class for collection resource pagination in PHP. Enhance your API development skills with practical coding examples.
Navigating the Lakehouse - Best Practices for Implementation with Apache Iceberg
Discover essential best practices and implementation strategies for Apache Iceberg in data lakehouse architectures, focusing on optimal performance and data management techniques.
Efficiently Managing and Optimizing Apache Iceberg with Apache Amoro
Discover how to optimize Apache Iceberg data lakes using Apache Amoro, exploring efficient management techniques and performance enhancements for large-scale data operations.
BanyanDB's New Column-Based Storage Engine
Discover how BanyanDB's innovative column-based storage engine enhances cloud-native data management and improves system performance for modern applications.
NextGen Data Platforms - The Data Mesh Architecture and Domain-Driven Design
Explore domain-driven data mesh architecture and its implementation for efficient data platforms, focusing on decentralized ownership, federated governance, and self-serve functionality.
Cross Generative AI: New Opportunities for AI in Customer Service
Explore how Cross-Generative AI revolutionizes customer service by combining human capabilities with AI, driving improved productivity, satisfaction, and cost optimization through integrated analytics.
Data as Code - Project Nessie and Git-like Experience for Apache Iceberg Tables
Discover how Project Nessie enables multi-table transactions and Git-like workflows for Apache Iceberg tables, revolutionizing data lakehouse management and engineering practices.

LANL's Journey Toward Computational Storage - Exploring Data Reduction Techniques for Petabyte-Scale Simulations
Explore LANL's innovative approaches to handling massive simulation data through computational storage techniques, focusing on efficient data reduction and analytics optimization for petabyte-scale operations.

Establishing Endurance and Data Retention Metrics in DNA Data Storage Systems
Explore the standardization of DNA data storage systems, focusing on metrics for endurance, reliability, and data retention, including preservation methods and labeling systems for optimal sequencing solutions.

Programming with Computational Storage - Overview and APIs
Discover how to leverage Computational Storage APIs for near-data processing, optimizing resource usage and overcoming traditional CPU architecture limitations in cloud and edge computing applications.
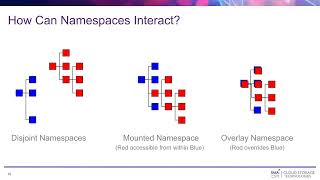
Simplified Namespace Management Using CDMI and Open Standards
Discover how to simplify complex namespace management using SNIA's CDMI open standard, covering discovery, introspection, exports, and imports across distributed systems and multiple protocols.
Hardware-accelerated Data Integrity Check on Computational Storage Devices
Discover how hardware-accelerated data integrity checks on Computational Storage Devices enhance performance, reduce data transfer overhead, and enable scalable storage solutions through practical demonstrations.
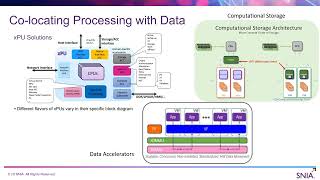
Storage Management Standards in Virtualized Environments - Managing Complexity Through Standards-Based Solutions
Explore modern storage management standards and their crucial role in navigating complex virtualized environments, from fabric technologies to open-source frameworks and RESTful interfaces.
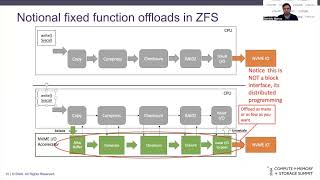
Improving Storage Systems for Simulation Science with Computational Storage
Explore how computational storage enhances HPC systems for simulation science, focusing on improved efficiency, transparent implementation, and real-world applications for petabyte-scale datasets.