Diving into Delta Lake: Understanding the Transaction Log
Explore Delta Lake's transaction log: its structure, functionality, and role in ACID transactions, metadata handling, time travel, and concurrent operations. Gain insights into this core component.
SQL Analytics and the Lakehouse Architecture - Data + AI Summit EU 2020 Keynote
Explore lakehouse architecture, Delta Lake, and SQL Analytics for unified data management. Learn how this approach combines data warehouse capabilities with data lake flexibility, enabling faster analytics and decision-making.
Designing the Next Generation of Data Pipelines with Apache Spark - Zillow's Approach
Zillow's data engineering team shares their journey in redesigning data pipelines using Apache Spark, focusing on scalability, maintainability, and robustness while reducing code complexity.
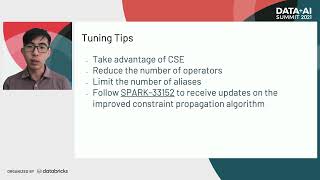
Optimizing Catalyst Optimizer for Complex Spark Plans
Optimizing Spark's Catalyst optimizer for complex plans with thousands of operators and large case statements. Techniques include memory-efficient logging, subexpression elimination, and improved constraint propagation.
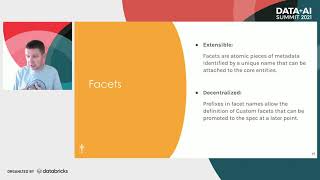
Observability for Data Pipelines with OpenLineage
Explore data pipeline observability using OpenLineage, enhancing reliability and auditability. Learn how metadata collection enables understanding of data flow and dependencies across teams and technologies.
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
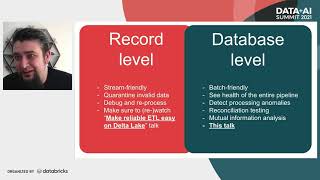
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
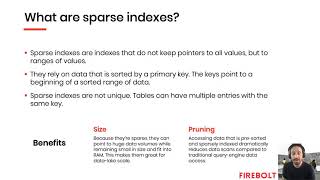
Low-Latency & High-Concurrency Analytics Over Data Lakes
Explore advanced techniques for achieving low-latency, high-concurrency analytics on large-scale data lakes. Learn about optimized storage, indexing, and practical approaches to handle massive data volumes efficiently.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
Solving Business Problems with Data - Delivering Value Through Use Case Deconstruction
Explore strategies for aligning data teams with business goals, focusing on use case deconstruction and value delivery. Learn to bridge the gap between technical expertise and practical business impact.
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Understand Slowly Changing Dimensions
Learn to handle Slowly Changing Dimensions in data warehousing, including SCD types, their implementation, and impact on star schema design. Gain expertise for interviews and practical applications.
Cyber & Data - What is Data?
Explore data types, formats, and structures in cybersecurity. Learn parsing, encoding, compression, and file analysis techniques for effective data handling and security.
Delta from a Data Engineer's Perspective - Creating Robust Big Data Solutions
Explore a data engineer's challenges in creating robust Big Data solutions, covering Delta, Spark streaming, schema enforcement, and time travel functionality in data processing.
Re-Imagining Apache Spark Development - Tools for Productivity and Standardization
Exploring next-gen tools for Apache Spark development, focusing on productivity, code standardization, metadata, lineage, and CI/CD agility to overcome limitations of traditional ETL tools.
Big Data Analytics - Ben Fountain, NCC Group
Explore big data analytics, its importance, key controls, and potential pitfalls. Learn how to leverage data for insights and decision-making in various industries.
Big Data and Cyber Security - David Stubley
Explore the intersection of big data and cybersecurity, covering data management, visualization, and key drivers in this informative talk by David Stubley.
Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
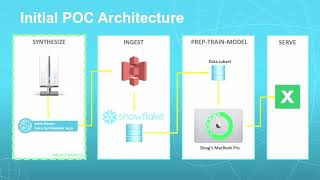
Securely Enabling Data Science in the Cloud
Explore secure cloud-based data science strategies, focusing on enabling analytics while maintaining data privacy and compliance across various cloud providers and data types.
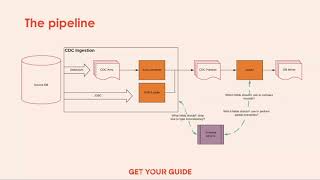
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.