Log Aggregation
Explore real-time log aggregation with Humio for efficient system monitoring. Learn about its unique features, query language, and advantages over alternatives for critical distributed systems.
Working on Cancer
Exploring whole genome sequencing for cancer treatment using Clojure, Neo4j, and domain-specific languages. Discusses challenges, solutions, and non-traditional team approaches in clinical settings.
Optimizing Speed and Scale of Real Time Analytics Using Apache Pulsar and Apache Pinot
Explore Apache Pulsar for event streaming and Apache Pinot for real-time analytics. Learn how these powerful open-source tools combine to deliver scalable, low-latency data processing and analysis in cloud-native environments.
Optimizing Speed and Scale of User-Facing Analytics Using Apache Kafka and Pinot
Explore real-time analytics optimization using Apache Kafka and Pinot. Learn how these powerful tools work together to deliver scalable, low-latency solutions for user-facing applications.
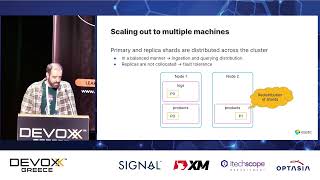
Finding Needles in Ever Increasing Haystacks - Scalability with Elasticsearch
Explore Elasticsearch's distributed architecture, efficiency, and resilience for modern data challenges. Learn about ingestion, sharding, replication, and search distribution techniques.

Streaming CDC Data from PostgreSQL to Snowflake - Challenges and Solutions
Uncover streaming ETL secrets: Postgres to Snowflake data ingestion, change data capture, dynamic tables, and Snowpipe streaming. Learn solutions for lower latency, cost savings, and enhanced scalability.

Building a Flexible Data Platform for LLM Training Data
Explore LLM training data platforms: architecture, ingestion, preprocessing, and scaling challenges. Learn from Cohere's experience in managing petabyte-scale datasets for high-quality model training.
Building a Telegram Bot with Apache Kafka and ksqlDB
Hands-on demonstration of building a Telegram bot using Apache Kafka and ksqlDB, showcasing real-time data processing, querying, and integration capabilities without additional datastores.
Solving Security's Data Problem with Cribl Stream - Building Sustainable Security Architecture
Master data pipeline optimization techniques to enhance security operations, reduce noise, and build sustainable architectures for effective threat detection and response.
Anomaly Detection with Apache Pinot and ThirdEye
Explore anomaly detection techniques using Apache Pinot and ThirdEye for efficient cloud-native data analysis and monitoring.
Using the FLiPN Stack for Edge AI
Explore the FLiPN stack for building fast IoT and AI applications. Learn how Apache Flink, NiFi, and Pulsar combine to create scalable streaming solutions for edge computing and rapid data ingestion.
Saga: Continuous Construction and Serving of Large Scale Knowledge Graphs
Explore continuous construction and serving of large-scale knowledge graphs with Saga, an end-to-end platform. Learn about challenges in industrial settings and various graph services.
Transforming the Retail Industry with Transformers
Explore how transformers and language models revolutionize retail data processing, overcoming challenges in deployment and automation for improved business outcomes.

Unlocking the Power of Multi-Protocol Messaging with Apache Pulsar
Explore Apache Pulsar's multi-protocol capability for building modern, distributed applications. Learn to design and deploy polyglot messaging systems using MQTT, Kafka, and AMQP protocols.
Building Scalable and Resilient Event-Driven Applications with Apache Pulsar
Explore Apache Pulsar's capabilities for building scalable, resilient event-driven applications. Learn key concepts, best practices, and see a live demonstration of Pulsar's power in action.
Load Testing Fabric: Determining Hold Capacity for Large Datasets
Discover techniques for testing Fabric's capacity to handle large-scale data processing, from ingestion to PowerBI visualization, for enterprise-level workloads.
Apache Flink for Sales Analytics - End-to-End Data Engineering Project
Develop an end-to-end sales analytics project using Apache Flink. Learn data ingestion, processing, complex transformations, and custom output formats for big data processing.
GenAI for Observability in the Serverless World
Harness GenAI to enhance serverless observability, leveraging vector databases and ML for improved data ingestion, log analysis, and problem resolution.

Getting Started with OpenSearch and OpenSearch Dashboards
Learn to set up and use OpenSearch for powerful search and analytics. Master cluster configuration, dashboard creation, and best practices for effective data visualization and management.
Model Blind Spot Discovery for Better Models and Ingesting Chaos - Mini Summit #2
Discover techniques for model blind spot detection and handling unstructured data at scale. Learn to build resilient AI models through data diagnosis, enhancement, and automated evaluation systems.
Feeding ML Models with Real-Time Database Data
Explore real-time data ingestion from databases to ML models using Change Data Capture. Learn about Debezium, challenges, and future improvements with a live TensorFlow demo.