Automating Machine Learning Workflow with DVC
Discover how to automate and streamline machine learning workflows using DVC, from data ingestion to model deployment. Learn to organize pipelines efficiently, regardless of project size.
Mastering a Data Pipeline with Python - 6 Years of Learned Lessons from Mistakes
Explore key insights and best practices for building robust data pipelines with Python, covering data acquisition, transformation, storage, and workflow management based on 6 years of experience.
Data Ingestion and Big Data
Learn web scraping, crawling, and API usage for data retrieval. Explore technical and ethical considerations in simulating user navigation and leveraging data APIs for analysis and business opportunities.
Azure Synapse Analytics
Unified data analytics platform for ingesting, preparing, managing, and serving data, combining enterprise data warehousing and big data analytics capabilities.
Data Virtualization is Easy with SQL Server Big Data Cluster
Explore data virtualization using SQL Server 2019 Big Data Cluster. Learn to access and analyze external data sources, implement data ingestion, and gain insights from a real project's lessons learned.
Ingesting and Managing Petabytes of Data with Azure Data Factory
Explore improvements in Azure Data Factory for simplified data integration and management, including code-free ETL/ELT and comprehensive data overview, empowering enterprises to handle petabytes of data for valuable insights.
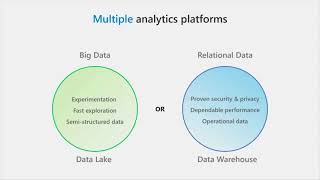
Introducing Azure Synapse Analytics - The End-to-End Analytics Platform
Explore Azure Synapse Analytics, a comprehensive platform integrating relational and big data systems for efficient data ingestion, preparation, modeling, and serving in a unified workspace.
Azure Synapse Analytics - A Data Lakehouse
Explore Azure Synapse Analytics, a unified service combining data warehousing and Big Data analytics. Learn about its features, scalability, and integration in modern data warehouses through demonstrations.
Machine Learning on Kubernetes Birds of a Feather
Explore best practices for implementing and scaling machine learning solutions on Kubernetes, covering the entire pipeline from data ingestion to production deployment.
Bootstrapping Microservices Using Akka, Kafka, and Spark
Explore real-time data platforms using Kafka, Spark Streaming, and Akka. Learn about unified data transfer protocols, topic management, and scalable ingestion for modern microservices architecture.
Akka Streams for High Throughput Data Processing
Explore high-throughput data processing with Akka Streams, comparing it to Akka Actors. Learn best practices, optimization techniques, and when to switch to Streams for improved performance in large-scale data transfer systems.
Processing Data at Scale with Rails
Strategies for handling large datasets using Rails, covering data ingestion, transformation, and storage with tools like ActiveRecord, Sidekiq, and Postgres.
Fundamentals of Azure IoT
Explore Azure IoT infrastructure, MXChip Kit, and connecting industrial equipment. Learn about SDKs, data ingestion, device management, and practical examples using various platforms.
Data Sharding and the Art of Real-Time Analytics at Scale
Discover how to implement data sharding for sub-second real-time analytics queries at scale, focusing on Apache Druid implementation, operational challenges, and performance optimization techniques.
Automating Azure Data Factory for Rapid Data Ingestion - 20-Minute Solution
Automate Azure Data Factory ingestion into Data Lake using BimlFlex accelerators in just 20 minutes. Learn efficient data loading techniques and DataOps automation.

Challenges Using Apache Kafka for Data Streaming Systems
Explore key capabilities of streaming platforms and compare self-managed Apache Kafka with Confluent Cloud's fully-managed services for efficient data streaming operations.
Beyond Kafka: Cutting Costs and Complexity with WarpStream and S3
Explore WarpStream's solution for Apache Kafka challenges, leveraging S3 for efficient streaming storage. Learn cost-saving strategies and witness live performance tests handling high-volume data ingestion.

Optimizing Time Series Data in Mixed Architectures with QuestDB
Explore time series database optimization, high-performance data ingestion, and cross-platform integration with QuestDB engineer Adam Cimarosti. Gain practical insights for handling fast-moving data in modern deployments.
Real-time Operational Data Streaming for Analytics and Generative AI Apps Using Datastream
Explore serverless data streaming for operational analytics and AI apps with Datastream, featuring insights from RocketMoney and Intuit Mailchimp.
Databricks Vector Search - What, Why and How
Explore Databricks Vector Search for enhancing GenAI applications with semantic search capabilities, addressing challenges in scalability, accuracy, and production deployment.
Building High Performance Real-time Stream Processing Microservices - GeeCON 2023
Discover best practices for real-time stream processing, addressing challenges and optimizing projects for scalability, performance, failover, reliability, and data recovery using the Hazelcast platform.