Lowering the Entry Threshold for Neural Vector Search - Applying Similarity Learning
Explore similarity learning for efficient neural search implementation, reducing data requirements and training time while addressing domain-specific challenges.
Talking to Non-Searchers about Search Relevance - Haystack US 2023
Learn effective strategies for explaining search relevance to non-technical stakeholders, from CEOs to clients. Gain insights on communicating complex search concepts and their importance.
Beyond the Known: Exploratory and Diversity Search with Vector Embeddings - Haystack EU 2023
Explore innovative strategies for exploratory and diverse search using vector embeddings, enhancing user experiences beyond traditional search paradigms.
Chat With Your Data - A Practical Guide to Production RAG Apps
Learn to build production-ready RAG applications with insights from Moody's rapid development. Gain strategies for embedding, relevance measurement, cost management, and team organization for impactful AI-driven data interaction.
CRM Platform Migration - Data Engineering Journey and Value Unlocked
Explore the data engineering journey of CRM platform migration, focusing on personalization, cross-channel messaging, and offer optimization to enhance customer engagement and product development.
Introduction to Data Engineering - Best Practices and Production-Level Infrastructure
Learn best practices for scaling data science projects from local to production, covering infrastructure, reliability, and real-world applications in data engineering.
Introduction to SQL - Basics, Schema Objects, and Querying Databases
Learn SQL basics, schema objects, tables, and key syntax for querying databases with live examples from a Mars Petcare Data Engineer.
Building Vector-Powered Products with User Embeddings
Explore vector embeddings for user modeling, learn vector ops, and discover applications in recommender systems and bot detection. Gain insights from real-world deployments.
Using the FLiPN Stack for Edge AI
Explore the FLiPN stack for building fast IoT and AI applications. Learn how Apache Flink, NiFi, and Pulsar combine to create scalable streaming solutions for edge computing and rapid data ingestion.
Advanced SQL: Top Tips for Dealing with Real-World Data
Level up SQL skills with advanced techniques for messy data, window functions, and arrays to tackle real-world analytics challenges effectively.
Saga: Continuous Construction and Serving of Large Scale Knowledge Graphs
Explore continuous construction and serving of large-scale knowledge graphs with Saga, an end-to-end platform. Learn about challenges in industrial settings and various graph services.
Transforming the Retail Industry with Transformers
Explore how transformers and language models revolutionize retail data processing, overcoming challenges in deployment and automation for improved business outcomes.
Engineering and Production Techniques for Managing Feature Drift in AI Models
Explore engineering techniques for managing feature drift in large-scale AI models, drawing insights from real-world case studies and best practices.
Fighting Pipeline Debt With Great Expectations
Learn to combat pipeline debt using Great Expectations, an open-source library for data validation, documentation, and profiling in complex data systems.
A Tale of A Thousand Pipelines: Building Scalable Deep Learning Pipelines for Time-Series Datasets
Discover scalable deep learning pipelines for massive time-series datasets, reducing costs by 80% while training hundreds of models efficiently.

Using pgvector and PostgreSQL to Find Pictures at a Party
Explore using pgvector and PostgreSQL to automate finding photos of yourself at events. Learn to extract faces, calculate embeddings, and query image data efficiently.
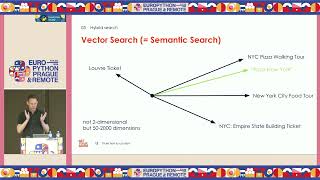
From Text to Context: How We Introduced a Modern Hybrid Search
Discover how to implement a modern hybrid search system combining BM25 and semantic vector models. Learn from real-world challenges and solutions in improving e-commerce search functionality.
OpenLineage: An Open Standard for Data Lineage
Explore OpenLineage, an open framework for data lineage metadata collection. Learn its purpose, data model, and integration with tools like Apache Airflow and Spark to enhance pipeline understanding and management.

Unlocking the Power of Multi-Protocol Messaging with Apache Pulsar
Explore Apache Pulsar's multi-protocol capability for building modern, distributed applications. Learn to design and deploy polyglot messaging systems using MQTT, Kafka, and AMQP protocols.
Building Scalable and Resilient Event-Driven Applications with Apache Pulsar
Explore Apache Pulsar's capabilities for building scalable, resilient event-driven applications. Learn key concepts, best practices, and see a live demonstration of Pulsar's power in action.
Demystifying Apache Airflow - Separating Facts from Fiction
Unpack critiques of Apache Airflow, analyze its strengths and weaknesses, debunk myths, and compare with competitors. Make informed decisions about workflow management platforms.