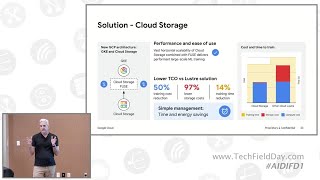
Google Cloud Storage Solutions for AI and ML Workloads - Performance Optimization and Management
Discover how Google Cloud Storage optimizes AI/ML workloads through GCS FUSE, Anywhere Cache, and Parallel Store features, enhancing performance and reducing training costs for machine learning development.
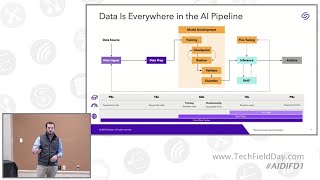
Data Infrastructure's Impact on AI Value Creation
Explore how data infrastructure shapes AI development, from training data quality to edge computing deployment, emphasizing storage solutions and performance optimization across the complete AI pipeline.

Introduction to Data Build Tool (DBT) - Features and Project Creation
Master data transformation techniques with DBT (Data Build Tool) to effectively analyze and engineer warehouse data through hands-on project creation and fundamental features.
Data Governance and Data Lake Implementation with Delta Lake
Discover how to effectively implement Data Lake with Data Governance through Microsoft's key services, featuring real SK case studies and insights on ML Studio and Power BI integration.
The Intelligent Future of Data Warehouses and Delta Lake - Structured Streaming with PySPARK
Explore the evolution of data warehousing from traditional ETL to modern Lakehouse architecture, focusing on Delta Lake, Structured Streaming, and PySpark implementation with practical code examples.
DocETL: AI Agents for Complex Document Processing and Data Transformation
Discover how DocETL framework leverages AI agents and LLMs to transform complex document processing, featuring innovative operators and optimization techniques for enhanced data extraction and analysis.
Machine Learning System Endeavors - From Design to Production
Explore the journey of implementing a video processing AI system, from initial design through production challenges, focusing on ML pipeline management, bug tracking, and real-world impact in smart buildings.
Engineers Guide for Shepherding Models into Production
Discover essential engineering practices for deploying machine learning models into production systems, from input/output definition to optimization and integration within larger infrastructures.
Overview of the Databricks Platform and Data Lakehouse Architecture
Discover how Databricks revolutionizes data processing by combining data warehouse and lake architectures through Delta Lake, Apache Spark, MLFlow, and Koalas frameworks for scalable data engineering and analytics.
Practical Kimball Data Patterns for Machine Learning Data Warehousing
Discover how dimensional modeling and Kimball patterns can streamline machine learning projects, reduce data preparation time, and improve ML model development through practical warehouse design techniques.
Airflow в кровавом энтерпрайзе
Discover how to effectively deploy and implement Airflow for enterprise automation, with step-by-step guidance on setup, configuration, and best practices for streamlining routine processes.
Airflow Distributed Workloads - ETL Architecture with AWS Lambda and Multi-Threaded Python Scripts
Master distributed workload processing with Airflow, AWS Lambda, and multithreaded Python scripts while exploring ETL architecture for third-party API integration at scale.
Architectural Evolution of Amazon's Internal Data Platform - PXT DaaS
Dive into the architectural journey of PXT DaaS, Amazon HR's serverless data platform, exploring self-service implementation, scalability solutions, and real-world engineering challenges.
Full-link Data Monitoring in Xiaomi Data Integration
Discover comprehensive data monitoring strategies and integration practices used at Xiaomi, focusing on full-link monitoring systems and DataOps implementation techniques.
A Year in Production with Machine Learning on the BEAM
Explore insights on transitioning machine learning pipelines to Elixir, leveraging the Nx ecosystem for streamlined development and swift experimentation in production environments.
Practical Pipelines: Houseplant Soil Alerting System with ksqlDB
Develop a houseplant soil alerting system using ksqlDB, exploring practical pipeline implementation for real-time data processing and monitoring.
Anomaly Detection with Apache Pinot and ThirdEye
Explore anomaly detection techniques using Apache Pinot and ThirdEye for efficient cloud-native data analysis and monitoring.
Using Frameworks to Test Apache Airflow Data Pipelines
Explore frameworks for testing Apache Airflow data pipelines, covering local development, CI/CD, validation, unit tests, and integration tests. Includes a practical demo and key takeaways.
Using Quix, Hugging Face, and InfluxDB for Anomaly Detection
Explore anomaly detection using Quix, Hugging Face, and InfluxDB. Learn about data pipelines, time series databases, and MLOps for effective machine learning implementation.

Working with BigQuery and DataForm - Streamlining Data Management and Transformation
Streamline data management with BigQuery and DataForm. Learn setup, optimization, and automation for efficient, scalable data pipelines and transformations.
Building an Open-Source Online Learn-to-Rank Engine - Haystack EU 2022
Explore Metarank, an open-source personalization service for learn-to-rank tasks. Discover how it simplifies data engineering challenges and improves search relevancy through visitor behavior analysis.