How to Define a Storage Infrastructure for AI and Analytical Workloads
Optimize AI/ML data pipelines at scale by selecting the right storage solutions for data preparation, training, inference, and serving. Integrate with Compute Engine, GKE, or Vertex workflows.
Optimizing Apache Spark and SQL for Improved Performance
Enhance Apache Spark and SQL performance through optimization techniques. Learn strategies for improved efficiency in data processing and analysis.
Handling Billions of Edges in a Graph Database
Explore techniques for managing massive graph databases with billions of edges, focusing on scalability, performance optimization, and efficient data handling in complex network structures.
Log Aggregation
Explore real-time log aggregation with Humio for efficient system monitoring. Learn about its unique features, query language, and advantages over alternatives for critical distributed systems.
Making Big Data Useful Data
Explore strategies for transforming big data into actionable insights, focusing on user-friendly tools and frameworks to empower business users in data analysis and decision-making.
The Evolution of Hadoop at Spotify Through Failures and Pain
Explore Spotify's Hadoop journey, from office closet to massive cluster, through failures and lessons learned. Gain insights on data infrastructure evolution and overcoming obstacles in large-scale systems.
Working on Cancer
Exploring whole genome sequencing for cancer treatment using Clojure, Neo4j, and domain-specific languages. Discusses challenges, solutions, and non-traditional team approaches in clinical settings.
Optimizing Speed and Scale of Real Time Analytics Using Apache Pulsar and Apache Pinot
Explore Apache Pulsar for event streaming and Apache Pinot for real-time analytics. Learn how these powerful open-source tools combine to deliver scalable, low-latency data processing and analysis in cloud-native environments.
Optimizing Speed and Scale of User-Facing Analytics Using Apache Kafka and Pinot
Explore real-time analytics optimization using Apache Kafka and Pinot. Learn how these powerful tools work together to deliver scalable, low-latency solutions for user-facing applications.
Assuring Data Quality at Scale
Explore strategies for implementing data quality at scale, covering challenges, metrics, and platform approaches for ensuring high-quality data in modern enterprises.
Keep Your Cache Always Fresh with Debezium
Explore how to maintain synchronized read views in distributed caches using change data capture, Debezium, Apache Kafka, and Infinispan. Learn to create denormalized data views and implement cross-site replication for cache updates.
Using Open Source Tech to Swap Out Components of Your Data Pipeline
Explore open-source technologies for flexible data pipelines, from Apache Kafka to BigQuery, with easy component swapping and cloud deployment options.
Platform Building for Data Mesh - Show Me How It Is Done
Demystifying Data Mesh through practical platform building, focusing on components, patterns, and technologies for developing and reusing data products in cloud-native environments.
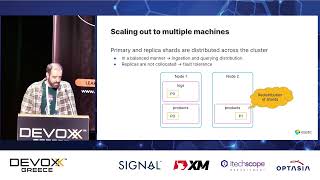
Finding Needles in Ever Increasing Haystacks - Scalability with Elasticsearch
Explore Elasticsearch's distributed architecture, efficiency, and resilience for modern data challenges. Learn about ingestion, sharding, replication, and search distribution techniques.
The Data Lakehouse for Streaming Data - A Talk for Everyone Who Loves Data
Explore data lakehouses: combining data lakes and warehouses for reliable, flexible data management. Learn about open-source projects, streaming data support, and see a live Twitter sentiment analysis demo.
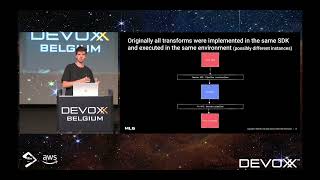
Building ML Workflows with Java, Python & Apache Beam
Learn to create multi-language ML pipelines using Apache Beam, combining Java for data processing and Python for ML modeling in batch and streaming workflows.

Apache Spark Beyond Shuffling - Why it isn't Magic - but also where there is some really cool Magic
Apache Spark performance deep dive: scaling challenges, RDD operations, key skew issues, and optimization techniques for distributed data processing. Insights from an IBM Spark engineer.
Reducing Complexity and Increasing Performance with Trino
Explore Trino's capabilities for efficient data querying across diverse sources, optimizing pipelines, and enhancing analytics performance in complex data environments.
Using Kafka at Scale - A Case Study of Microservices Data Pipelines at Evernorth Health Services
Explore a case study on implementing Kafka-based microservices data pipelines at scale in Evernorth Health Services, showcasing real-world applications and challenges.
Deeply Declarative Data Pipelines with Flink and Kubernetes
Explore declarative streaming data pipelines on Kubernetes using Flink and SQL. Learn to simplify development, integrate systems, and optimize configurations for efficient stream processing.
Working with Data Using Azure Functions
Explore Azure Functions for data interactions with Azure SQL, Cosmos DB, and Event Hubs. Learn to build lightweight, code-first APIs, integrations, ETL, and maintenance routines.