Ingesting 6.5 TB of Telemetry Data Daily Through Open Telemetry Protocol and Collectors
Learn how VTEX implemented Open Telemetry to handle 6.5TB of daily telemetry data, modernizing their observability stack while reducing costs and improving efficiency.
Feathr - An Open Source, Battle-Tested, Scalable and Enterprise-Grade Feature Store
Explore Feathr: an open-source, battle-tested feature store for machine learning. Learn its design, philosophy, and enterprise-grade capabilities, including native feature transformation and cloud-native architecture.
Categorizing Docker Hub's Public Images - End-to-End Machine Learning Pipeline with Docker Enterprise
Discover how Docker Enterprise and Kubeflow enable rapid development of production-ready machine learning pipelines for classifying container images, enhancing Docker Hub's discovery capabilities.
Building Robust ML Production Systems Using OSS Tools for Continuous Delivery for ML
Learn to build robust ML production systems using open-source tools for continuous delivery, including workflow orchestration, data versioning, and model deployment and monitoring.
Build or Buy: Observability Data Pipelines 101
Explore efficient observability data pipeline management for cloud services. Learn to handle massive data volumes, reduce costs, and optimize processing across teams and tools.
The State of Modern Data Architectures
Explore modern data architectures enabling agile, scalable solutions for IoT streaming, real-time analysis, and machine learning with large, multi-structured datasets in cloud environments.
Transforming Data Processing with Kubernetes - Journey Towards a Self-Serve Data Mesh
Explore Intuit's use of Kubernetes with Data Mesh principles to transform data processing, enabling efficient management of 100,000+ pipelines and fostering a collaborative data culture for improved decision-making.
Scaling ML Pipelines on Kubernetes Using Tekton - Overcoming Complexity
Explore scaling ML pipelines on Kubernetes with Tekton, addressing limitations and enhancing efficiency through custom tasks and integration with KubeFlow for improved scalability in production environments.
Infinite Compression, Zero Knowledge Auth and Merkle Proofs - IPFS Connect Istanbul 2023
Explore w3up: UCAN-based upload API for web3.storage, enabling verifiable end-to-end data pipelines with infinite compression, zero-knowledge auth, and Merkle proofs.
Vector Search and State-of-the-Art Retrieval for Generative AI Apps
Explore vector search, hybrid search, and reranking models for improved knowledge retrieval in Generative AI apps. Includes live code demos and evaluation insights on retrieval quality.
Building 12 Factor Streaming Data Apps on Kubernetes
Learn to build secure, resilient Kafka streaming apps on Kubernetes using 12-factor principles. Explore Lenses.io's SQL Engine and overcome deployment challenges for portable, cloud-native applications.

End-to-End Deep Learning Project: Kidney Disease Classification with MLflow, DVC, and Deployment
Comprehensive deep learning project on kidney disease classification, covering data ingestion, model preparation, training, evaluation, MLflow integration, DVC pipeline, and AWS deployment.
Building Knowledge Graphs
Explore the power of knowledge graphs in data management, their applications, and strategies for successful implementation in semantic search, recommendation systems, and data fabric.
How to Eliminate I/O Bottleneck and Continuously Feed GPU While Training in the Cloud
Optimize I/O for GPU-intensive machine learning training in the cloud. Learn a new architecture to maintain data throughput and implement it in Kubernetes for PyTorch workloads.
Optimizing Speed and Scale of Real-Time Analytics Using Apache Pulsar and Apache Pinot
Explore Apache Pulsar and Apache Pinot's synergy for high-speed, scalable real-time analytics in Cloud Native environments. Learn how these powerful tools enable efficient event streaming and ad-hoc data analysis.
Build an Event-Driven Machine Learning Pipeline on Kubernetes
Explore building event-driven ML pipelines on Kubernetes, leveraging components for automated AI workflows, including model training, validation, serving, and operations with focus on eventing and pipeline CRDs.
Enforcing Data Quality in Data Processing and ML Pipelines with Flyte and Pandera
Learn to enforce data quality in processing and ML pipelines using Flyte and Pandera, enhancing reliability and efficiency in data-driven projects.
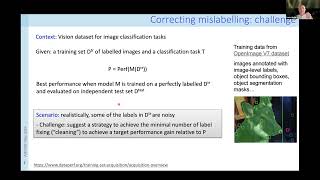
Explainable Data-Centric AI
Explore the next generation of AI systems through Data-Centric AI, focusing on data selection, engineering, and curation for robust, fair, and responsible AI with sustainable performance.
Breakdown New Data Silos in Generative AI
Explore strategies to overcome data silos in generative AI, enhancing model performance through improved data access, discovery, and integration across departments and cloud platforms.
Open Source DataOps and MLOps Strategies
Demystifying data challenges: interoperability, standardization, and vendor lock-in. Strategies for implementing DataOps and MLOps infrastructures using open source technologies.
Embracing Multi-Tenancy While Scaling MLOps
Explore multi-tenancy in MLOps: efficient resource sharing, isolation, and security for scaling ML operations. Learn implementation strategies using open-source tools like Flyte for cost-effective and secure multi-tenant environments.