
End to End NLP Project Implementation With Deployment Github Action - Text Summarization - Krish Naik
Comprehensive guide to implementing an end-to-end NLP text summarization project, covering data processing, model training, evaluation, and deployment using GitHub Actions on AWS.

Deploying and Exploring QuestDB on Kubernetes - Tutorial
Explore QuestDB deployment on Kubernetes, learn its features, and witness its impressive querying capabilities on large datasets. Hands-on demonstration with expert insights.
Demystifying Data Mesh - Tackling Common Misconceptions About Data Mesh - Wannes Rosiers
Clarifies Data Mesh principles, debunks misconceptions, and explores its potential to revolutionize data management in distributed landscapes. Provides insights for better understanding of this approach.

Feature Engineering for Web Bot Detection - Feature Engineering Tutorial
Learn to detect automated web traffic through feature engineering, exploring bot types, their impact on businesses, and extracting useful features for effective bot detection.

End to End ML Project - Data Transformation Implementation Using Pipelines
Implement data transformation using pipelines for ML projects, covering categorical and missing value handling, standard scaling, and artifact storage.
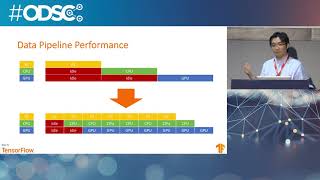
Deep Learning for Real Time Streaming Data with Kafka and TensorFlow - ODSC East 2019
Learn to process real-time streaming data using Apache Kafka and TensorFlow's KafkaDataset module for efficient machine learning applications in mission-critical scenarios.
Stream All Things - Patterns of Modern Data Integration
Explore patterns for modern data integration using Apache Kafka. Learn to build fast, scalable, and manageable data pipelines for reliable stream processing and low-latency applications.
Build Your Machine Learning Pipeline in These 4 Simple Steps - Loan Prediction Scikit-Learn Example
Aprenda a construir um pipeline completo de machine learning usando scikit-learn para previsão de empréstimos, desde a ingestão de dados até o uso do modelo salvo para previsões.
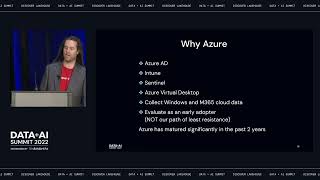
Building a Petabyte-Scale Cybersecurity Data Mesh in Azure with Delta Lake - HSBC Case Study
Explore HSBC's innovative approach to building a petabyte-scale cybersecurity data mesh in Azure, leveraging Delta Lake to address unique challenges and empower analysts with a unified, scalable platform.
Introducing MLflow for End-to-End Machine Learning on Databricks
Learn to predict life expectancy using health data with MLflow. Covers data engineering, exploration, model tuning, and deployment on Databricks' unified analytics platform powered by Apache Spark.
Frequently Bought Together Recommendations Using Embeddings - Challenges and Solutions
Explore embedding-based "frequently bought together" recommendations for e-commerce, covering model training, productionization, metrics, and serving strategies. Learn practical tips for large-scale implementation.
Introducing MLflow for End-to-End Machine Learning on Databricks
Explore end-to-end machine learning with MLflow on Databricks: from data engineering to model deployment, using health data to predict life expectancy through Spark, hyperopt, and interactive dashboards.
Accelerating the ML Lifecycle with Enterprise-Grade Feature Stores
Explore enterprise-grade feature store for ML lifecycle acceleration, addressing data engineering challenges, and empowering data scientists to streamline ML application delivery with centralized data management and instant feature serving.
Improving Broadcast Joins in Apache Spark SQL
Discover techniques to enhance broadcast joins in Apache Spark SQL, including executor-side broadcasting and memory optimization, for improved performance in large-scale ETL pipelines and complex data processing tasks.
Architect's Open-Source Guide for Data Mesh Architecture
Explore Data Mesh architecture, its principles, benefits, and implementation challenges. Learn about open-source tools like Apache Spark for building effective Data Mesh systems in real-world scenarios.
Monitoring ML Models, IoT Data, and Quality Checks on Delta Lake - Quby's Approach
Discover how Quby monitors IoT data, ML models, and data quality using Databricks. Learn about Delta Lake, MLflow, and Slack integration for efficient data processing and model performance tracking.
The "Top" Ten tinyML Commandments
Explore ten essential principles for tinyML success, covering data engineering, codesign, metrics, reproducibility, and industry collaboration, to drive innovation in embedded machine learning.
Distributed System Design for Data Engineering
Overview of distributed system design principles for data engineering, covering partitioning, replication, fault tolerance, and scalability. Includes real-world examples and best practices for building robust, large-scale data systems.
Building a Batch Processing Platform for Data Pipelines Using Argo and Kubernetes
Explore Intuit's scalable batch processing platform using Kubernetes and Argo for efficient data pipeline management, addressing scheduling, orchestration, and dependency challenges in AI and data engineering.
Prometheus in the MLOps Lifecycle
Explore Prometheus for monitoring ML deployments, addressing data drift, concept drift, and model metrics. Learn to enhance existing setups and integrate with Flyte, Seldon Core, or FastAPI.
SLA-Aware Batch Scheduling in Apache YuniKorn with Multi-Tenant Preemption
Explore SLA-aware batch scheduling and multi-tenant preemption in Apache YuniKorn for Kubernetes, addressing challenges in resource-intensive data engineering and improving workload management.