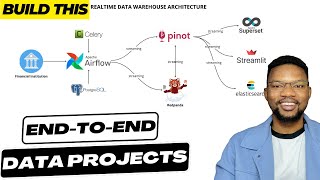
Building Realtime Data Warehouses from Scratch - End-to-End Data Engineering Project
Design and implement a real-time data warehouse with Apache Airflow, Kafka, and Pinot. Create custom hooks, ingest batch and streaming data, and visualize evolving data using Apache Superset.
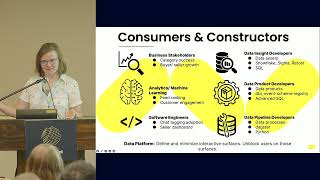
Extreme Self-Service: Turning Data Consumers into Data Constructors
Empower data consumers to create their own products with minimal training. Learn best practices, community building, SQL literacy promotion, and guard rail establishment for self-service analytics.
Behind the Hype - Architecture Trends in Data
Explore current data architecture trends with a seasoned engineer, cutting through industry hype to uncover underlying principles and ideals.
The Metadata-Driven Data Warehouse
Streamline data warehouse development using metadata-driven approaches. Learn efficient techniques for Insert/Update/Delete operations and pipeline management.
Introduction to Databricks Delta Live Tables
Accelerate data pipeline development with Databricks Delta Live Tables. Learn setup, ingestion, table creation, pipeline execution, and data validation for faster, more reliable projects.
What's New and Cool in Azure Synapse Analytics
Discover recent updates and new features in Azure Synapse Analytics for end-to-end analytics, with practical demonstrations and scenario-based applications.

Delta Live Tables - Building Reliable ETL Pipelines with Azure Databricks
Build fast, reliable, and scalable ETL pipelines using Delta Live Tables on Azure Databricks. Learn declarative approaches and see demos of simple and complex streaming pipelines.
Query Folding in Power Query: Importance for Performance
Discover query folding's importance for Power Query performance and learn factors that can hinder its effectiveness.
Why the Lakehouse? Understanding Data Lakehouse Architecture
Explore the Data Lakehouse architecture, its comparison to data warehouses, and reasons for implementation. Gain insights into technology options for planning your next data platform.
Workflows of Highly Functional App and Data Engineering Teams
Master enterprise data engineering: schema management, standards enforcement, testing, and automated deployment for scalable, high-quality solutions.
Building Tomorrow's Warehouse Today - Modern Data Warehouse Modelling Insights
Explore fundamental shifts in data warehousing architecture and processing design principles for modern, efficient data management and analysis.
Workflows of Highly Functional App and Data Engineering Teams
Master enterprise data engineering: schema management, standards enforcement, testing, and automated deployment for scalable, high-quality solutions.
Navigating the Skies of Data: A Flight Through Feature Stores
Explore Feature Stores' role in streamlining ML projects, acting as a control tower for efficient feature management in data processes.
Building Stream Processing Applications with Ruby and Meroxa - RubyConf 2022
Explore real-time stream processing using Ruby and the Turbine framework. Learn to build and deploy sophisticated applications without complex tooling or unfamiliar paradigms.
Orchestrating Scalable Data Pipelines with Apache Toree, YuniKorn, Spark, and Airflow
Explore integrated use of Apache Toree, YuniKorn, Spark, and Airflow for efficient, scalable data pipelines. Learn to leverage these projects for optimized data processing and workflow orchestration.
Efficient, Low Latency Ingestion to Large Tables via Apache Flink and Apache Iceberg
Learn efficient, low-latency data ingestion techniques using Apache Flink and Apache Iceberg for large tables. Explore integration challenges, performance optimizations, and comparisons with alternative solutions.
How to Pick the Best Data Transformation Strategy
Explore tools for combining data from multiple sources, including Azure Synapse, Spark, and Power BI Data Flows. Learn to select the optimal tool for your data environment.
Declarative ETL Pipelines with Delta Live Tables - Modern Software Engineering for Data Analysts and Engineers
Modernize ETL pipelines using Delta Live Tables for efficient data management. Learn development, production, and best practices for reliable, testable, and scalable data processing.
How to Create a High Performance Data Team - Lessons Learned from the Field
Discover key strategies for building and leading a high-performing data and analytics team, drawing from real-world experiences and proven methodologies.
Machine Learning in Astrophysics and Cosmology
Explore how astrophysics and cosmology leverage machine learning to analyze vast datasets, pioneering new methods and infrastructure for handling big data in scientific research.
Genomic-scale Data Pipelines - Building Serverless Bioinformatics Cloud Solutions
Explore genomic-scale data pipelines with cloud architects Lynn Langit and Denis Bauer. Learn about serverless bioinformatics, MedTech solutions, and cutting-edge approaches to handling large-scale genomic data.