Version Control for Lakehouse Architecture - Essential Practices and Benefits
Discover how to implement data version control using lakeFS for improved data quality, reproducibility, and experimentation in Databricks data/ML pipelines, enhancing overall product value.
Streamline Real-Time Ingestion and Serving with DLT and Online Tables
Västtrafik improves public transport efficiency using near real-time data ingestion for its Travel Planner App. Learn how Delta Live Tables and Brickstore optimize low-latency pipelines, balancing cost and performance.
Ocean Cleanup's Efforts to Remove Ocean Plastic - Leveraging Databricks
Databricks supports Ocean Cleanup's mission to remove 90% of ocean plastic by 2040, enhancing computer vision models, developing impact reporting, and streamlining data architecture for more efficient operations.
Learning New Tricks: Unilever's Dive into Unity Catalog
Explore Unilever's journey with Unity Catalog, including challenges faced, production-ready tooling, and new possibilities like Lakehouse Federation and Delta Sharing.
Building a Trusted Data Foundation for AI on Databricks
Modernize data engineering for AI with Qlik's integration of Databricks AI Functions, automating real-time data pipelines to enhance AI-driven analysis and ML model development on the Databricks platform.

Delta Live Tables in Depth - Best Practices for Intelligent Data Pipelines
Explore best practices, new features, and future developments for Delta Live Tables with Databricks experts. Learn pipeline development, data quality, and serverless compute for intelligent data pipelines.
Crisis Text Line's Data Platform for Mental Health Support
Leveraging Spark and Delta Lake on Databricks to scale mental health support, automate resource provisioning, and enable flexible data pipelines for Crisis Text Line's global operations.
Incremental Change Data Capture: A Data-Informed Journey
Explore data-driven strategies for incremental ingestion, from SaaS to databases and event streams. Learn cost-saving techniques, CDC flavors, and performance improvements for efficient data lake management.
Uber's Batch Analytics Evolution from Hive to Spark
Explore Uber's strategic migration from Hive to SparkSQL for batch analytics, including automation features, challenges faced, and efficiency gains achieved in this data processing evolution.
Building a Multimodal Data Lakehouse with the Daft Distributed Python Dataframe
Explore Daft, a next-gen distributed query engine for processing multimodal data at scale. Learn to build a multimodal data lakehouse using familiar dataframe interfaces on existing infrastructure.
Optimizing Lakehouse Architecture Costs with Intel Software and Databricks
Enhance large-scale data processing for AI with autonomous CPU optimization, cost-effective resource management, improved scalability, and streamlined Spark operations using Intel's solutions for Databricks Data Intelligence Platform.
Building Smart Industrial Automations with the Databricks API
Learn to create industrial automations using Databricks API, enabling data-driven applications and hardware triggers. Explore practical examples and simplify access to your data for tailored solutions.
Migrating and Optimizing Large-Scale Streaming Applications with Databricks
Rearchitecting a massive ad event processing system using Databricks Spark Structured Streaming, covering migration strategies, performance optimizations, and enhanced development features for real-time analytics and ad log delivery.
Data Engineers AI Survival Guide
Essential guide for data engineers navigating AI projects: from project selection to execution plans, toolsets, and skills needed for success in the rapidly evolving AI landscape.
Simplifying Data Ingestion for LLMs with Unstructured and Databricks
Learn to build a scalable solution for unstructured data ingestion in LLM applications using Unstructured and Databricks, addressing challenges and exploring efficient methods.
Moving from SAP Business Warehouse to Databricks - Insurance Company Case Study
Explore an insurance company's migration from SAP BW to Databricks, highlighting improved performance, automated ETL, enhanced self-service, and cost reduction. Learn insights and future possibilities.
GumGum Media's Data Science Journey on Databricks
Explore GumGum Media's data science evolution with Databricks, featuring insights from Sr. Engineering Manager Brendan Frick on leveraging advanced analytics for media innovation.
Data Engineering on the Data Intelligence Platform - A Comprehensive Guide
Explore data engineering on Databricks' platform: ingest, transform, and orchestrate data at scale. Learn about streaming pipelines, data quality, and AI-powered tools for real-time insights.
Data Pipelines Evolution from Batch to Streaming
Explore the evolution from batch to streaming data pipelines using Apache Flink and Kafka. Learn strategies for seamless transition, including query-based connectors, change data capture, and handling late events.
Streaming vs. Batch Processing: The Future of Data Architecture
Explore the future of data processing with industry experts as they debate streaming vs. batch, adoption challenges, and best practices for real-time data architecture.
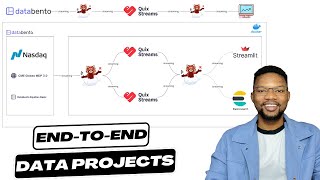
Realtime Stock Market Anomaly Detection Using Machine Learning - End-to-End Data Engineering Project
Develop an end-to-end data engineering project for real-time stock market anomaly detection using Quix Streams, Redpanda, and Docker. Learn to build a complete data pipeline and deploy an advanced ML model.