Resiliency Practices in Managing CDN - Content Delivery Network
Explore Netflix's Open Connect CDN resilience strategies, including stack failures, overload tests, and regional DNS withdrawal exercises to ensure robust content delivery worldwide.
Building and Operating a Pretty Big Storage System - My Adventures in Amazon S3
Insights into building and operating Amazon S3, exploring technical challenges, organizational aspects, and personal experiences of working on a massive-scale cloud storage service.
Meatbag Systems - How Our Reliability Culture & Practice Evolved over Time
Exploring the evolution of reliability culture through major incidents, emphasizing the human aspect in maintaining production systems and aligning reliability with customer value.
Real-Time Adaptive Controls for Resilient Distributed Systems
Explore real-time adaptive controls for resilient distributed systems, focusing on dynamic parameter tuning to enhance service resilience and reduce configuration errors in large-scale production environments.
Improving Machine Learning Development Reliability
Explore challenges and solutions for ML development reliability, focusing on unique aspects of the ML lifecycle, monitoring, and scalability in production environments.
Move Fast and Learn Things - Principles of Cognition, Teaming, and Coordination
Explore cognitive and coordinative mechanisms for resilient software engineering, drawing from psychology and management theory to enhance SRE practices and organizational effectiveness.
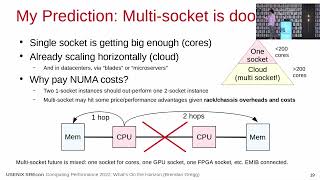
Computing Performance 2022 - What's on the Horizon
Explore the future of computing performance with insights on emerging hardware and software technologies, their impact on SRE, and predictions for improved speed and efficiency.
A Post Incident Review Review
Explore ANZx's unique post-incident review process, focusing on safety science concepts and avoiding root cause analysis or action items tracking in a regulated industry environment.
Advanced Linux Kernel Networking Monitoring
Explore advanced Linux kernel networking monitoring for containers, focusing on troubleshooting techniques and a custom tool for identifying network issues in Kubernetes environments.
How We Drained Every Backbone Router Simultaneously
Exploring Meta's 2021 outage: causes, cascading effects, and lessons learned. Insights into network infrastructure, disaster recovery, and future improvements for preventing similar incidents.
What SRE Could Be - Systems Reliability Engineering
Explore the evolution of Site Reliability Engineering (SRE) and its potential future as a systems thinking-based discipline for managing complex software production environments.
SRE in Enterprise
Explore challenges and solutions for adopting Site Reliability Engineering (SRE) in enterprise environments, based on insights from Google Cloud experts and a new O'Reilly report.
An SRE Guide to Linux Kernel Upgrades
Demystifying Linux kernel releases: Learn to safely and timely update your systems, balancing security patches with stability concerns for high-profile services and applications.
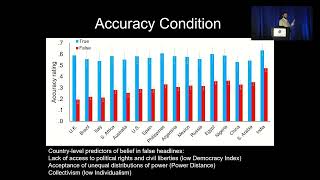
Understanding and Reducing Online Misinformation Across 16 Countries on Six Continents
Explore global misinformation trends, predictors of susceptibility, and effective interventions across 16 countries. Learn about cognitive styles, motivations, and strategies to combat false information online.
Surprise-Inspired Networking
Explore the future of networking with a focus on edge computing and the value of new information. Insights on synthesizing data at the network edge for innovative system designs.
A Postmortem of SRE Interviewing
Insights from 110+ SRE interviews: improving the hiring process for all parties involved, from application to offer acceptance, with practical tips for candidates and companies.
Taking the 737 to the Max
Explore Boeing's decision-making process for the 737 MAX, examining key choices and their consequences to gain insights on effective team decision-making and avoiding critical errors.
Using Serverless Functions for Real-time Observability
Explore how serverless functions enhance real-time observability in large-scale systems. Learn about query engine evolution, lambda management challenges, and optimizing performance with cloud storage and parallel workers.
LDPC-in-SSD - Making Advanced Error Correction Codes Work Effectively in Solid State Drives
Explore advanced error correction techniques for solid state drives, focusing on LDPC codes to improve reliability while mitigating response time delays in NAND flash memory.
Scaling Distributed Machine Learning with the Parameter Server
Explore a framework for distributed machine learning using parameter servers, enabling scalable processing of petabyte-scale data with billions of examples and parameters across various algorithms.
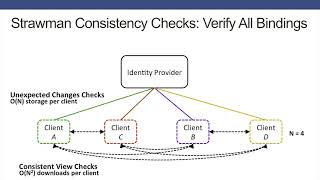
CONIKS - Bringing Key Transparency to End Users
Explore CONIKS, an innovative key verification service for end-to-end encrypted communication systems, addressing privacy and efficiency challenges in user key binding consistency and provider auditing.