Learning More from Complex Systems
Explore complex systems' traits and learn better approaches to incident analysis beyond linear root-cause methods. Gain insights from history, science, and philosophy to enhance understanding of resilience in modern organizations.
Evolution of Incident Management at Slack
Explore Slack's evolution in incident management, covering strategies for handling numerous incidents, team-wide capability building, and future directions in maintaining platform reliability.
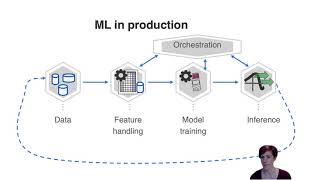
Demystifying Machine Learning in Production - Reasoning about a Large-Scale ML Platform
Explore techniques for managing and improving reliability in large-scale machine learning production systems, focusing on common failure modes, best practices, and practical strategies for SREs.
From 15,000 Database Connections to Under 100 - A Tech Debt Tale
Explore a multi-year tech debt resolution journey, focusing on reducing database connections from 15,000 to under 100. Learn strategies for handling scaling challenges in distributed systems.
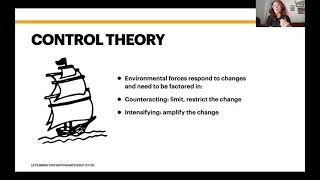
Let's Bring System Dynamics Back to CS
Explore System Dynamics for modeling feedback loops in distributed systems. Learn its history, tools, and applications to prevent outages and improve software architecture design.
MySQL and InnoDB Performance for the Rest of Us
Demystifies MySQL and InnoDB performance, covering storage engines, indexes, and query optimization. Provides practical insights for improving database efficiency and understanding SQL operations.
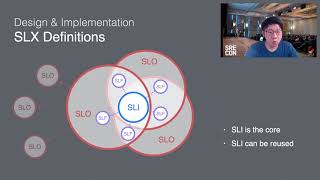
SLX - An Extended SLO Framework to Expedite Incident Recovery
Explore an extended SLO framework (SLX) for managing high-availability systems, featuring innovative concepts like SLF and SLD to build knowledge graphs and expedite incident recovery.
Optimizing Cost and Performance with Arm64
Explore how Honeycomb.io optimized cost and performance by migrating to arm64 architecture, reducing compute costs by 40% while improving latency, despite challenges in software compatibility and ecosystem complexity.
Take Me Down to the Paradise City Where the Metric Is Green and Traces Are Pretty
Explore OpenTelemetry for cloud-native observability, including its APIs and SDKs. Learn how to implement traces and metrics in Java and Go, with practical examples and insights on framework stability.
Cache Strategies with Best Practices
Explore efficient cache strategies for data-intensive services, including item management, TTL optimization, and warm-up techniques. Learn to enhance system performance and availability through real-world examples.
A Political Scientist's View on Site Reliability
Explore how political science concepts can provide fresh perspectives on site reliability, team dynamics, and simplifying complex production environments in software engineering.
Latency Distributions and Micro-Benchmarking to Identify and Characterize Kernel Hotspots
Explore kernel hotspots using latency distributions and micro-benchmarking. Learn techniques to identify and address OS scale limits for improved system performance on bare metal hardware.
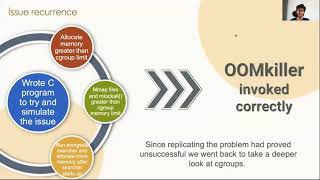
When Linux Memory Accounting Goes Wrong
Debugging Linux memory accounting issues in cgroups, exploring scenarios where misaccounting can lead to host inaccessibility and application failures despite set limits.
Engineering Onboarding
Industry experts discuss challenges, changes, and future trends in engineering onboarding, covering remote work, diversity, training methods, and strategies for improving new hire experiences.
Don't Follow Leaders or - All Models Are Wrong - and So Am I
Reflective analysis of SRE book's impact, addressing its strengths, weaknesses, and unresolved challenges in production engineering and reliability practices five years after publication.
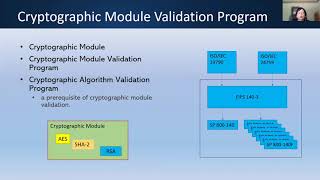
The Cornerstone for Cybersecurity - Cryptographic Standards
Introduction to NIST cryptographic standards, their applications in cybersecurity, and future challenges including quantum threats, transitions, and lightweight cryptography for constrained devices.
Why You Should Burn Down Your Datacenter
Explore datacenter optimization challenges, integrating infrastructure management with power, space, and cooling systems. Learn about industrial controls and their limitations in this thought-provoking talk.
Can Infrastructure as Code Apply to Bare Metal?
Explore applying Infrastructure as Code principles to bare metal environments, addressing challenges and showcasing proven techniques for secure and resilient physical infrastructure automation.
Lessons Learned from a Ransomware Attack
Comprehensive analysis of a real-world ransomware attack on a school district, covering timeline, damage, recovery, and preventive measures for future cybersecurity preparedness.
Beyond Firefighter vs. Safety Matches - Growing the DevSecOps Pipeline
Explore strategies for balancing specialization and generalization in DevSecOps talent development, addressing challenges in modern systems development, operations, and security.
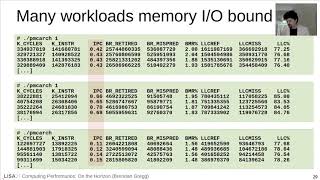
Computing Performance - On the Horizon
Explore future computing performance trends in processors, memory, storage, networking, and cloud technologies, with insights on emerging innovations and their potential impact.