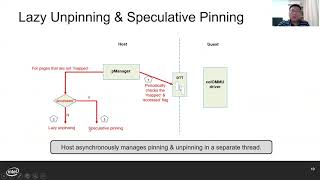
coIOMMU - A Virtual IOMMU with Cooperative DMA Buffer Tracking for Efficient Memory Management in Direct I/O
Explore efficient memory management in direct I/O virtualization through coIOMMU, a novel virtual IOMMU architecture with cooperative DMA buffer tracking for improved performance and resource utilization.
Twizzler - A Data-Centric OS for Non-Volatile Memory
Explore Twizzler, an innovative OS redesign for non-volatile memory, offering efficient data persistence, simplified programming, and improved performance over traditional systems.
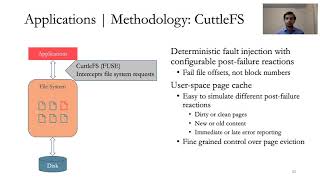
Can Applications Recover from fsync Failures?
Análisis de cómo sistemas de archivos y aplicaciones modernas reaccionan ante fallos de fsync, revelando vulnerabilidades críticas en la durabilidad de datos y sugiriendo mejoras de diseño.
Serverless in the Wild - Characterizing and Optimizing the Serverless Workload
Explore serverless computing workloads, challenges, and optimization strategies in cloud environments. Gain insights into Azure Functions' production data and learn about innovative resource management policies.
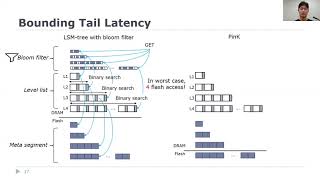
PinK - High-speed In-storage Key-value Store with Bounded Tails
Explore high-speed in-storage key-value systems with PinK, an innovative LSM-tree-based design that significantly improves performance and reduces latency in resource-constrained environments.
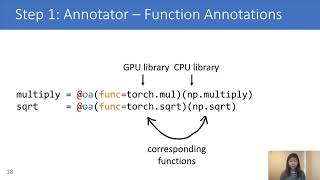
Offload Annotations - Bringing Heterogeneous Computing to Existing Libraries and Workloads
Explore offload annotations for efficient GPU computing in existing libraries, enabling seamless integration and performance gains without extensive code modifications.
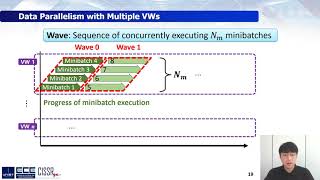
HetPipe - Enabling Large DNN Training on Heterogeneous GPU Clusters through Integration of Pipelined Model Parallelism and Data Parallelism
Explores HetPipe, a system integrating pipelined model parallelism and data parallelism for training large DNNs on heterogeneous GPU clusters, improving performance and enabling use of less powerful GPUs.
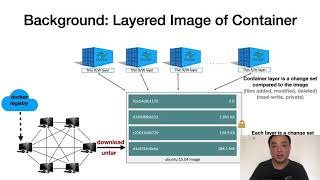
DADI - Block-Level Image Service for Agile and Elastic Application Deployment
Explore DADI, a block-level image service enhancing application deployment agility and elasticity. Learn about its instant container start, peer-to-peer architecture, and multi-runtime support.
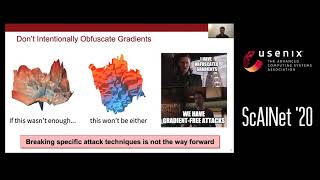
On Adaptive Attacks to Adversarial Example Defenses
Explore adaptive attacks on adversarial example defenses, examining challenges, whitebox attacks, and key observations to understand vulnerabilities in machine learning security.
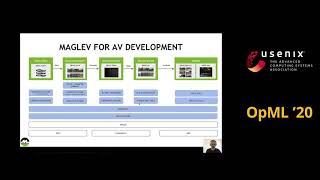
Inside NVIDIA’s AI Infrastructure for Self-Driving Cars
Explore NVIDIA's Project MagLev, an AI platform for self-driving car development, covering data management, neural network training, and large-scale validation across petabytes of data.
Scalable AutoML for Time Series Forecasting Using Ray
Explore scalable AutoML for time series forecasting using Ray, covering feature generation, model selection, and distributed hyper-parameter tuning with real-world applications and insights.
Managing ML Models at Scale - Intuit’s ML Platform
Explore Intuit's ML Platform for scalable, secure model lifecycle management using GitOps, SageMaker, Kubernetes, and Argo Workflows. Learn about feature management, cost optimization, and enterprise-level ML model deployment.
Ten Persistent SRE Antipatterns - Pitfalls on the Road to a Successful SRE Program
Explore common pitfalls in Site Reliability Engineering and learn strategies to build successful SRE programs, drawing insights from industry leaders like Netflix and Google.
Making the Most of Your SRE Toolbox - Bootstrapping Your SRE Team through Reuse
Explore strategies for repurposing existing tools and frameworks to establish an effective SRE organization, drawing from real-world experiences in building comprehensive delivery pipelines.
The Secret Lives of SREs - Controlling the Costs of Coordination across Remote Teams
Exploring hidden complexities in SRE incident response, revealing surprising findings on coordination strategies, tooling impacts, and adaptive choreography in managing service outages.
Building Service Ownership Using Documentation, Telemetry, and a Chance to Make Things Better
Explore strategies for building distributed service ownership in software teams, focusing on documentation, telemetry, and empowering teams to drive improvements in system reliability and performance.
Identifying Hidden Dependencies
Discover how Honeycomb improved system reliability through intentional node termination, uncovering bugs and progressing towards continuous experimentation for enhanced resilience and scalability.
Continuously Improving Culture through Design Decisions
Explore how technical decisions shape DevOps culture, focusing on Two Sigma's COIN platform. Learn strategies for fostering collaboration, innovation, and community in tech environments.
Avoiding Goodhart's Law - Use SLOs as Tools Not Cudgels
Explore how to effectively use SLIs, SLOs, and Error Budgets as tools for balanced risk management and productive conversations, rather than punitive measures in SRE practices.
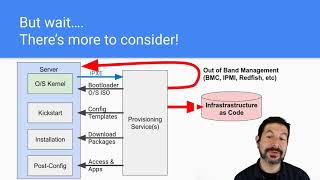
Give Your PXE Wings - Bootstrapping Explained
Demystifying system bootstrapping: explore PXE, multi-stage processes, and automation techniques for faster, simpler, and more reliable IT provisioning and day-two operations.
It's a Trap! How Abstractions Have Failed Us
Explores how excessive abstraction in tech can lead to complexity, loss of foundational knowledge, and disconnection from original problems. Offers insights on balancing abstraction with practicality.