ColPALI: Efficient Document Retrieval Using Vision Language Models for RAG Systems
Discover how ColPALI revolutionizes document retrieval by using Vision Language Models to efficiently process and retrieve visually rich documents without OCR, enhancing RAG systems performance.
Scientific Problem-Solving with GPT-4 Vision - Mathematical Formula Recognition and Python Code Generation
Discover how GPT-4 Vision transforms complex mathematical problem-solving by converting formula images into executable Python code, streamlining scientific calculations and verification processes.
Stable Diffusion XL with T2I-Adapter and ControlLoRA - Tutorial and Demo
Master advanced image generation techniques using SDXL with T2I adapters and ControlLoRA, featuring hands-on demonstrations and practical implementations for enhanced AI art creation.
AI Agents: Understanding LLM Systems and Task-Specific Tools - An Introduction
Discover the fundamentals of AI agents, their interaction with LLMs, and practical implementation methods in this beginner-friendly exploration of modern artificial intelligence.
Reversible Transformer - GPU Memory Optimization Using ReFORMER and Reversible Residual Layers
Delve into GPU memory optimization techniques for transformers, exploring reversible residual layers and locality-sensitive hashing to enhance deep neural network efficiency and performance.
BLIP-2: Connecting Vision-Language Models with Q-Former for Image Chat
Explore BLIP-2's innovative approach to combining vision and language models through Q-Former, enabling advanced image-based conversations and multimodal AI interactions.
Code Panoptic Image Segmentation with Vision Transformer and Mask2Former - A PyTorch Tutorial
Dive into advanced image segmentation using Mask2Former architecture, exploring masked attention and universal segmentation techniques for enhanced computer vision applications.

Panoptic Image Segmentation - Understanding Mask2Former
Dive into Mask2Former's universal approach to image segmentation, covering instance, semantic, and panoptic segmentation techniques with practical examples and implementations.
Reliable Object Detection and Identification in Adverse Conditions
Explore radar-based perception systems for autonomous vehicles, focusing on reliable object detection in adverse weather conditions and multi-sensor fusion techniques for enhanced safety.
Pretrain-Finetune and Uncertainty Estimation in Machine Learning - Part 1
Dive into advanced machine learning concepts, from masked language modeling and pretrained vision models to uncertainty estimation and probability calibration techniques.
Data Preparation and Transformer Models - Introduction to Text and Image Processing
Master data preparation techniques for transformers, including text and image processing, and understand the fundamentals of transformer architecture and pretraining methods.
Qwen 2.5 Math and Vision Models - Latest Open Source Developments
Explore the latest advancements in Qwen2.5-72B models, featuring specialized mathematics capabilities and enhanced vision processing with M-RoPE technology for improved AI performance and versatility.
Adapting Image-based Reinforcement Learning Policies via Predicted Reward Fine-Tuning
Explore groundbreaking research on Predicted Reward Fine-Tuning (PRFT), a novel approach solving domain shift challenges in image-based reinforcement learning and sim-to-real AI transfer.
Fine-tuning Vision Language Models with PaLiGemma-3B - A Practical Guide
Master fine-tuning techniques for Vision Language Models using PyTorch and JAX FLAX, with practical examples for PaliGemma-3B implementation on free compute platforms like Google Colab and Vertex AI.
Learning Vision Transformer (ViT) Technology: Research Methods and Resources - 2023
Discover effective strategies for learning and implementing Vision Transformer technology through top academic resources, code repositories, and research platforms like HuggingFace and Papers with Code.
Building a BLIP-2 Application: Vision Transformer and Language Model Integration
Master building a multimodal AI system that combines Vision Transformers and language models to analyze images and generate contextual responses through practical implementation of BLIP-2 architecture.
PyTorch Vision Transformer - Guide to Fine-Tuning for Object Identification
Master fine-tuning Vision Transformers (ViT) in PyTorch through hands-on coding, focusing on object identification implementation with practical examples and real-time coding demonstrations in Google Colab.
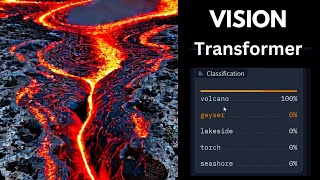
PyTorch Vision Transformer: Applying Pre-trained and Fine-tuned ViT Models for Image Classification
Master Vision Transformer implementation in PyTorch using pre-trained and fine-tuned ViT models for image classification, with hands-on practice in Google Colab and Huggingface integration.
Vision Transformer-Based Transfer Learning for Medical Image Classification 2023
Explore cutting-edge Vision Transformer technology for medical image classification, focusing on mammogram analysis and early breast cancer detection through advanced deep learning approaches.
Insights from Diverse Projects in Image Search and RAG
Explore practical insights from real-world vector search projects, covering image matching, property deduplication, and RAG implementations, with focus on DinoV2 and Ada-2 model performance.
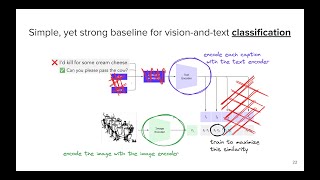
Multilingual and Multimodal Large Language Models
Explore the fascinating world of multilingual and multimodal Large Language Models, understanding their capabilities, applications, and future potential in AI development.