AI-Enhanced Medical Mask Compliance in Healthcare - Building a Safety Net with Computer Vision
Discover how computer vision and deep neural networks enhance medical mask compliance monitoring through object detection and facial landmark analysis for improved healthcare safety.
Computer Vision in Melanoma Detection - AI Applications in Dermatological Diagnosis
Explore how AI and computer vision technologies revolutionize melanoma detection in dermatology, examining implementation challenges and potential healthcare benefits.
Deploying Computer Vision Models at Scale DevOps-Free - Reducing Deployment Time and Costs
Discover how to efficiently deploy computer vision models at scale using AWS tooling and software engineering techniques to reduce deployment time and cut inference costs significantly.
Seeing Through the Lens of Transformers - A New Era in Computer Vision
Explore the revolutionary impact of transformer architecture in computer vision, from its origins in language processing to groundbreaking applications in visual tasks and self-attention mechanisms.
The Future of AI: From Language Models to Multimodal Agents and Video Processing
Explore the cutting-edge developments in AI technology, from multimodal agents to GPT-4's video capabilities, and discover how AI systems are evolving to handle diverse data types and tasks.
Stable Diffusion XL Theory and Code with Shape-Shifting ControlNet
Dive into the advanced mechanics of SDXL and ControlNet, exploring text-to-image diffusion models and shape-shifting techniques for synthetic image manipulation.
Robotics Transformer 2 (RT-2) - Vision-Language Models for Advanced Robotics
Explore how RT-2 combines Vision-Language Models with robotics, enabling advanced control systems and improved generalization through web-scale pre-training and specialized datasets.
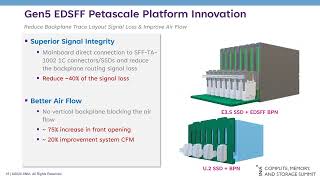
Storage Architecture Optimized for AI Workloads - High Performance Solutions for GPU Clusters
Discover how to optimize storage architecture for AI workloads, exploring high-performance solutions, capacity-optimized tiers, and real-world implementations for machine vision applications.
AI Inference Engine for Object Storage Systems
Discover how AI inference capabilities enhance object storage systems by automating metadata generation, enabling advanced object detection, and improving searchability of stored data.
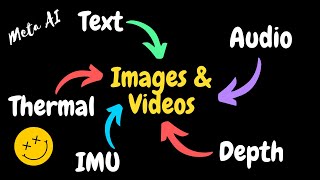
ImageBind: A Multi-Modal AI Model for Unified Embedding Space
Explore Meta AI's ImageBind technology and its groundbreaking approach to unified AI learning across six modalities, from technical architecture to practical applications and results.
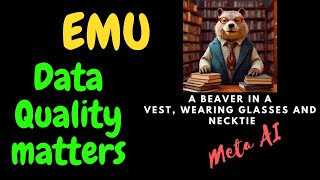
Enhancing Image Generation Models Using Photogenic Needles in a Haystack - Meta's Emu Architecture
Dive into Meta's Emu architecture and quality fine-tuning process, exploring how this modified Latent Diffusion Model achieves exceptional image generation and precise editing capabilities.
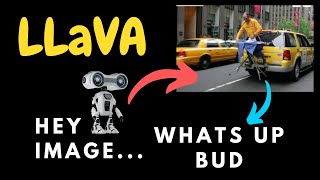
LLaVA: Large Language and Vision Assistant - Understanding the First Instruction-Following Multimodal Model
Discover how LLaVA pioneered instruction-tuned multimodal AI, combining language and vision capabilities to create a groundbreaking Large Multimodal Model for advanced visual understanding and interaction.
Lumiere: Space-Time Diffusion Model for Text-to-Video Generation
Dive into Google's Lumiere text-to-video model, exploring its innovative space-time UNet architecture and MultiDiffusion design for creating temporally consistent video generation.
Machine Learning Career Roadmap 2024 - From Beginner to Expert
Discover a comprehensive YouTube learning path for mastering Machine Learning and AI, from mathematical foundations to specialized areas like NLP and Computer Vision - all through free resources.
Stable Video Diffusion: Model Architecture and Training Pipeline
Dive into the technical architecture and training methodology of Stable Video Diffusion, exploring its three-stage process, data curation pipeline, and practical applications in AI-powered video generation.
ControlNet: Adding Conditional Control to Text-to-Image Diffusion Models
Delve into the groundbreaking ControlNet paper, exploring its architecture, classifier-free guidance, and spatial control capabilities in text-to-image diffusion models through detailed technical explanations.
Robin3D: Improving 3D Large Language Models Through Robust Instruction Tuning
Discover how Robin3D advances spatial intelligence through innovative data generation and architectural improvements for better 3D scene understanding and object relationship comprehension.

DINOv2: Data Pipeline, Model Training and Results - Meta AI's Visual Feature Learning System
Delve into Meta AI's DINOv2 architecture, exploring its data pipeline, training methodology, and innovative features for robust visual processing without supervision in just 12 minutes.
Understanding Meta AI's Segment Anything Model (SAM) - Architecture, Data Engine, and Results
Dive into Meta AI's Segment Anything Model (SAM), exploring its architecture, innovative data engine, and zero-shot transfer learning capabilities for advanced image segmentation tasks.
ChatGPT and Whisper API Tutorial - Building a Demo Application with Python
Master ChatGPT's Python API capabilities through hands-on demonstrations of text completion, chat, image generation, and speech features, culminating in building a Streamlit demo application.
Behavior Cloning and Residual Reinforcement Learning for Visual Assembly
Explore advanced imitation learning techniques combining behavior cloning with reinforcement learning for autonomous robotic systems, focusing on precise visual assembly and sim-to-real transfer applications.