Colossus and Code Breaking in World War II
Explore the groundbreaking Colossus computer and code-breaking efforts at Bletchley Park during WWII, focusing on the Lorenz cipher and its impact on strategic intelligence.
Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
How to Build a Cloud Data Platform - Part 1: Architecture
Learn to build a unified cloud data platform using Delta Lake, combining data warehouses and lakes for improved reliability, performance, and operations.
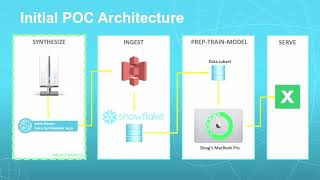
Securely Enabling Data Science in the Cloud
Explore secure cloud-based data science strategies, focusing on enabling analytics while maintaining data privacy and compliance across various cloud providers and data types.
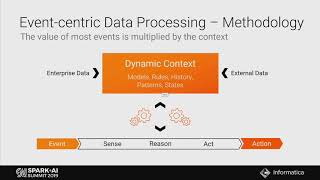
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
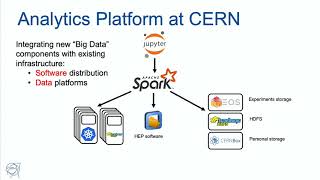
Deep Learning Pipelines for High Energy Physics Using Apache Spark and Distributed Keras
Explore CERN's Apache Spark-based data pipeline for deep learning in High Energy Physics. Learn about distributed training of neural network classifiers using BigDL and Analytics Zoo for improved event filtering at LHC experiments.
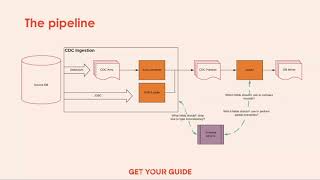
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
Apache Spark Core - Practical Optimization Techniques - Partition Shaping and Job Optimization
Explore Apache Spark optimization techniques, including partition shaping, join and aggregate optimizations, and multi-dimensional parallelism to maximize cluster utilization and eliminate data skew.
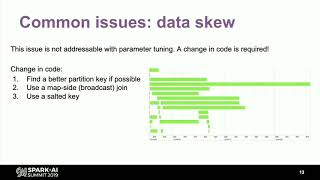
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.
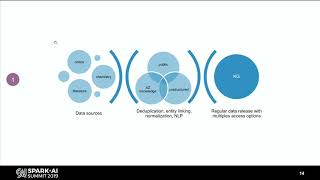
Building a Knowledge Graph with Spark and NLP for Novel Drug Recommendations
Explore drug discovery using knowledge graphs, NLP, and Spark. Learn techniques for efficient data processing, entity recognition, and relationship extraction to enhance pharmaceutical research.
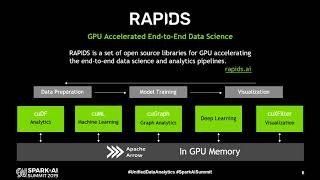
Accelerating Apache Spark with GPUs Using RAPIDS
Explore GPU acceleration for data science with RAPIDS, offering significant performance gains over CPU-only solutions. Learn its functionality, architecture, and integration with Apache Spark for large-scale computation.
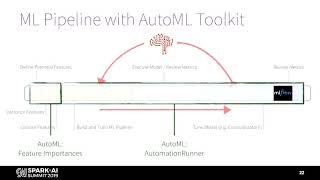
Augmenting Machine Learning with Databricks Labs AutoML Toolkit
Explore how Databricks Labs AutoML Toolkit simplifies and optimizes machine learning processes, from data preparation to model optimization, using financial loan risk data examples.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
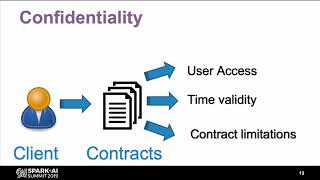
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.
How to Handle High Cardinality Predictors for Data on Museums in the UK
Explore effect and likelihood encodings for high cardinality predictors in tidymodels, using UK museum data to demonstrate practical applications.
Deploy Different Prediction Types for a Bigfoot Sighting Model
Learn to deploy various prediction endpoints for a Bigfoot sighting model using vetiver, including feature engineering, logistic regression, and natural language processing techniques.
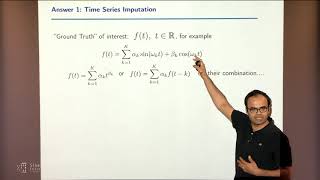
Time Series Analysis via Matrix Estimation
Explore matrix estimation techniques for time series analysis, focusing on imputation, algorithms, and theoretical foundations with practical applications in societal networks.
Why Do Our Models Learn?
Exploring biases in ImageNet and their impact on machine learning models, discussing dataset creation processes and their consequences for real-world applications of AI.
Introduction to Databricks Lakehouse Platform Architecture and Security
Explore Databricks Lakehouse Platform's architecture, focusing on data reliability, Delta Lake features, and Photon's performance enhancements for efficient data management and analytics.
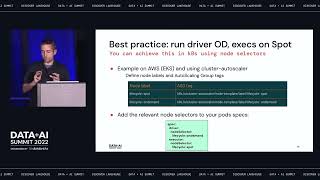
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.