Football Data Analytics: Azure End-to-End Data Engineering Project - Part 2
Extract, store, and analyze football data using Azure services and Apache Airflow. Develop end-to-end data engineering skills through hands-on implementation of a real-world project.
Reddit Data Pipeline Engineering with AWS - End-to-End Data Engineering
Build a comprehensive Reddit data pipeline using AWS services, integrating Airflow, S3, Glue, Athena, and Redshift for efficient ETL processes and analytics.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.
Realtime Algorithmic Trading with Apache Flink - End-to-End Data Engineering Project
Develop an end-to-end algorithmic trading system using Apache Flink, Kafka, and Python. Learn real-time data processing, custom algorithms, and financial market insights.
Developing gRPC Communication with Quarkus and Microprofile
Explore gRPC for efficient API development in microservices, leveraging Quarkus and Microprofile. Learn fundamentals, best practices, monitoring, error handling, and advanced features.
Developing gRPC Communication with Quarkus and Microprofile
Explore gRPC for efficient API development in microservices, leveraging Quarkus and Microprofile. Learn best practices, performance optimization, monitoring, error handling, and advanced features.
Developing Tests with Quarkus
Learn best practices for Quarkus testing, covering mocking, integration tests, test profiles, and native executable testing. Master transaction, component, and persistence testing techniques.
Beyond REST and CRUD: Integration Patterns in Microservices
Explore advanced integration patterns for microservices beyond REST and CRUD, enhancing system design and communication in distributed architectures.
Server-Side WebAssembly - Understanding Its Potential in Cloud Computing
Explore server-side WebAssembly's potential in cloud computing. Learn its basics, advantages over containers, and practical applications through a demonstration of current capabilities.
Server-Side WebAssembly - Understanding Its Potential in Cloud Computing
Explore WebAssembly's potential in cloud computing, its comparison to containers, and how to start with server-side WebAssembly. Includes a demonstration of capabilities and future possibilities.
Debezium - Building Streaming Data Pipelines with Change Data Capture
Explore Debezium's features for building streaming data pipelines using popular databases as sources, with a focus on Apache Kafka integration and alternative data sinks.
A Comprehensive Guide for Kubernetes-Native Java
Explore Kubernetes-native Java development techniques and best practices for building scalable, cloud-native applications in this comprehensive guide.
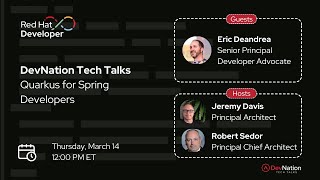
Quarkus for Spring Developers
Transition from Spring to Quarkus with ease. Learn familiar concepts, implement conventions, and explore testing with Quarkus Dev Services through live coding of a Spring application equivalent.
Optimizing Apache JVMs for Apache Kafka Performance
Optimize Apache JVMs for Apache Kafka performance. Learn about JVM internals, garbage collection, JIT compilation, and cloud-native compilers to enhance real-time data pipelines and reduce costs.
Top 6 Worst Apache Kafka JIRA Bugs
Explore six critical Apache Kafka bugs with expert Anna McDonald. Gain insights into batching, replication protocols, networking, and Scala implementation, enhancing your understanding of Kafka's inner workings.
Migrate Your Kafka Cluster with Minimal Downtime
Learn strategies and tools for migrating Kafka clusters with minimal downtime. Explore MirrorMaker, Confluent Replicator, and Cluster Linking. Gain insights on planning, execution, and overcoming challenges in Kafka migration.
Kafka, Flink, and Beyond: Current Developments and Future Innovations in Data Streaming - 2023
Explore recent advancements, upcoming improvements, and innovative applications in Kafka and Flink data streaming. Gain insights from industry leaders on tiered storage, queues, use cases, and two-phase commit protocol.
Diving into the World of Service Mesh and Istio - Part 1
Explore Istio service mesh for microservices. Learn installation, security, traffic control, and inter-service communication. Gain practical skills for developers and operators new to Istio.