How Datadog is Transforming Time Series Forecasting with Toto
Discover how Toto, a Time Series-Optimized Transformer, revolutionizes forecasting through advanced architecture and trillion-point training data, enabling precise zero-shot predictions for observability metrics.
Automatically Instrument Your Go Source Code with Orchestrion
Explore Orchestrion, an extensible tool for automatic Go code instrumentation. Learn about parsing, code analysis, distributed tracing, and using annotations for cross-cutting concerns.
Continuous Profiling in Cloud Native Applications
Explore continuous profiling in cloud-native environments, discussing implementation strategies, challenges, and its integration with service mesh and observability tools.
Imagined Dragons: Building an Imagination-Powered Music Recommendation Platform
Explore building an AI-powered music recommendation platform using LLMs. Learn prompt engineering, chatbot memory management, and open-source tool creation for innovative mixtape generation.
Better Reliability with Service Level Objectives (SLOs) - Defining and Implementing SLIs
Learn to define and implement Service Level Objectives (SLOs) effectively, including choosing indicators, setting agreements, and discussing realistic availability for improved reliability.
Scalable Strategies for Migrating to OpenTelemetry
Strategies for migrating to OpenTelemetry: planning, gradual rollout, transitioning from Datadog, deploying Collector at scale for metrics and trace collection, and exploring new applications.
Monitoring: A New Approach
Learn a modern approach to monitoring systems, covering tools, collectors, aggregators, visualizers, and notifiers for effective system oversight and management.
How We Managed a Massive-scale Incident at Datadog
Explore Datadog's response to a massive global outage, including technical challenges, solutions, and incident management strategies for coordinating 500+ engineers over 2+ days.
Building Confidence in Kubernetes Controllers - Lessons Learned from Using E2e-Framework
Explore e2e-framework for testing Kubernetes components, with insights from Datadog and Crossplane's adoption. Learn implementation strategies, benefits, and potential challenges.
Hacking Kubernetes to Migrate In-Tree Volumes to CSI
Explore the process of migrating in-tree volumes to CSI in Kubernetes, including custom scripts, API server patching, and strategies for minimizing risk and downtime during the transition.
JVM and TLS - eBPF's Out-of-Comfort Zone
Explore eBPF's application in observability, focusing on capturing encrypted TLS traffic in JVM apps. Learn about limitations, alternative strategies, and a Datadog PoC for overcoming challenges in cloud native observability.
Kubernetes at Datadog Scale
Explore Datadog's journey scaling Kubernetes clusters, uncovering challenges, contributions, and insights for growing from small to large-scale deployments.
Unleashing Chaos and Breaking Containers
Explore chaos engineering principles and practices for container reliability through live demonstrations, failure injections, and success metrics.
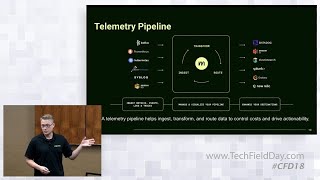
Understand and Optimize Logs, Metrics, Traces, and Events with the Mezmo Telemetry Pipeline
Master telemetry data optimization techniques for DevOps and SREs, covering data profiling, signal isolation, and dynamic pipelines to enhance observability platform performance and reduce costs.
클라우드 MSP 서비스의 실용적인 자동화 전략 - 노코드 플랫폼 활용 사례
Discover how to enhance Cloud MSP service quality through no-code automation strategies, featuring practical implementation cases and future service transformation insights from SK C&C's expertise.
Managing Expectations During Large-Scale Infrastructure Migration
Gain insights on managing expectations during large-scale infrastructure migrations. Learn strategies for effective communication, understanding human motivations, and navigating challenges in transforming deployment practices.
Adapting XDS Control Plane for Proxyless gRPC - Datadog's Experience
Explore xDS control plane adaptation for proxyless gRPC, enhancing service discovery, configuration centralization, and advanced load balancing features in large-scale systems.
Optimizing Telemetry Data Analysis and Log Management with Mezmo
Master telemetry data optimization techniques for DevOps and SREs - from data profiling and cost management to real-time monitoring and sensitive data handling in observability platforms.
AWS Observability as Code - Leveraging Datadog
Explore AWS observability using Datadog, covering challenges, fundamentals, implementation as code, and advanced techniques for effective platform engineering and monitoring.
Subsetting in gRPC - Implementation at Datadog
Explore Datadog's implementation of subsetting in gRPC to scale distributed systems. Learn about benefits, implementations, load balancing, and efforts to upstream changes.
DeepBrew 2.0 - Starbucks Enterprise Managed ML Platform
Plataforma empresarial para operacionalizar soluciones de IA/ML a escala, con automatización, servicios gestionados y mejores prácticas. Utiliza Databricks, MLflow, Azure y herramientas de monitoreo para un desarrollo eficiente.