Developing Scalable Machine Learning Pipelines for Gaming Industry
Explore scalable ML pipelines in gaming, leveraging Apache Spark for data-driven product development and improved user acquisition through advanced LTV modeling.
Democratizing Data - Leadership Insights from Rolls-Royce's CIDO - Episode 1
Explore data democratization with Rolls-Royce's CIDO Stuart Hughes. Learn about disruptive leadership, simplified data architecture, and empowering data teams to unlock the true potential of data.
Designing and Implementing a Real-time Data Lake with Dynamically Changing Schema
Learn to build a robust streaming ETL pipeline that handles dynamically changing schemas and new event types without downtime, using Delta Lake and Databricks for real-time data lake implementation.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Scaling Machine Learning Feature Engineering in Apache Spark at Facebook
Explore advanced techniques for scaling ML feature engineering in Apache Spark, including Feature Injection and Feature Reaping, with optimizations for improved performance and efficiency at Facebook's scale.
Building a Cloud Data Lake with Databricks and AWS - Best Practices and Implementation
Explore building a cloud data lake using Databricks and AWS. Learn about data lake architecture, AWS services, Delta Lake for reliability and performance, and best practices for implementation.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
Stateful Streaming with Apache Spark - Updating Decision Logic at Runtime
Learn how to implement stateful streaming with Spark, focusing on updating decision logic at runtime for real-time offer personalization in loyalty programs like PAYBACK.
Demystifying Delta Lake - Data Reliability for Data Lakes
Explore Delta Lake's reliability features for data lakes with Apache Spark creator Michael Armbrust. Learn about ACID transactions, metadata handling, and unified data processing.
SQL Analytics and the Lakehouse Architecture - Data + AI Summit EU 2020 Keynote
Explore lakehouse architecture, Delta Lake, and SQL Analytics for unified data management. Learn how this approach combines data warehouse capabilities with data lake flexibility, enabling faster analytics and decision-making.
How Apache Spark 3.0 and Delta Lake Enhance Data Lake Reliability
Explore Apache Spark 3.0 and Delta Lake's enhancements for data lake reliability, including ACID transactions, schema enforcement, and time travel. Learn about performance improvements and new features in Databricks Runtime 7.0 Beta.
Run Queries Instantly in Optimized Environments - Databricks Data Platform Overview
Discover how Databricks empowers data teams with instant query execution, optimized environments, and enhanced security, accelerating innovation while maintaining governance and compliance.
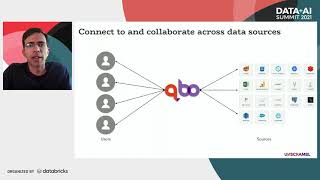
Natural Language Query and Conversational Interface to Apache Spark
Explore conversational analytics with Apache Spark, enabling natural language queries for data insights. Learn about NLP-to-SQL translation and its integration with dialog management and visualization.
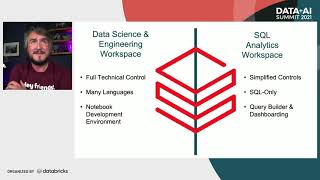
Getting Started with Databricks SQL Analytics
Explore Databricks SQL Analytics: set up SQL endpoints, query workspaces, create dashboards, and connect BI tools. Learn how this tool enhances the Lakehouse architecture for SQL-savvy data analysts.
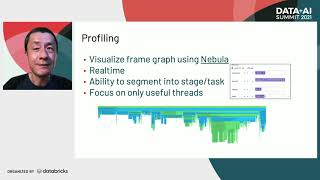
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
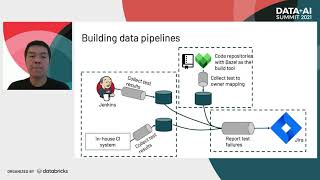
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
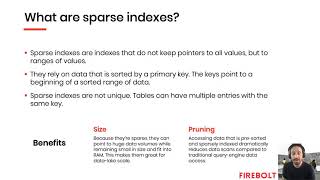
Low-Latency & High-Concurrency Analytics Over Data Lakes
Explore advanced techniques for achieving low-latency, high-concurrency analytics on large-scale data lakes. Learn about optimized storage, indexing, and practical approaches to handle massive data volumes efficiently.
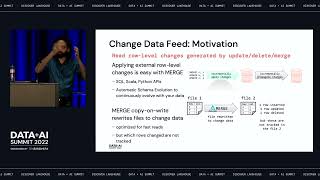
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
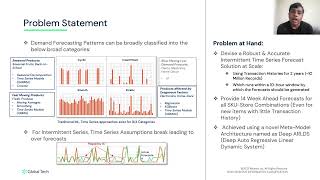
Intermittent Demand Forecasting at Scale Using Meta-Modeling - Deep Auto-Regressive Linear Dynamic Systems
Discover Walmart's innovative solution for predicting demand of slow-moving items using meta-modeling, combining linear dynamic systems and deep auto-regressive networks for accurate forecasts across thousands of SKUs and stores.
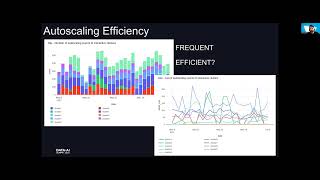
Databricks and Enterprise Observability with Overwatch - Understanding Cost, Utilization, and Workloads
Explore Overwatch's capabilities for monitoring Databricks platform costs, utilization, and workloads. Learn implementation, use cases, and solutions to common observability challenges.
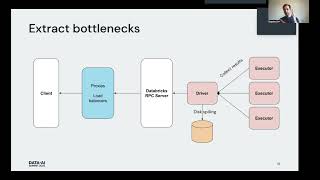
Cloud Fetch: High-Bandwidth Connectivity for BI Tools - Databricks
Explore high-bandwidth connectivity for BI tools using Cloud Fetch, a parallel data extraction mechanism that significantly speeds up query result retrieval from Databricks SQL endpoints.