Fine-tuning Optimizations - DoRA, NEFT, LoRA+, and Unsloth
Explore advanced fine-tuning techniques like DoRA, NEFT, LoRA+, and Unsloth to optimize language models. Learn implementation, comparisons, and practical applications through code examples and demonstrations.
Full Fine-Tuning vs LoRA and QLoRA - Comparison and Best Practices
Explore full fine-tuning vs (Q)LoRA techniques, comparing VRAM usage, training time, and quality. Learn parameter selection, tips for QLoRA, and step-by-step guidance for TinyLlama and Mistral 7B fine-tuning.
Very Few Parameter Fine-Tuning with ReFT and LoRA
Explore advanced fine-tuning techniques ReFT and LoRA for efficient parameter optimization in transformer models. Learn implementation, comparison, and practical tips for improved model performance.
Transformers from Scratch - Part 2: Building and Training a Weather Prediction Model
Dive deep into advanced transformer concepts, exploring encoder-decoder architectures, GPT-4o, and positional embeddings. Apply knowledge to weather prediction and analyze model performance.
Improving LLM Accuracy with Monte Carlo Tree Search
Explore Monte Carlo Tree Search to enhance LLM accuracy, focusing on boosting Llama 3 8B performance. Learn implementation, testing, and limitations through code examples and mathematical problem-solving.
RAG with Verified Citations - Advanced Inference Techniques
Explore advanced RAG techniques with verified citations, including BM25 and cosine similarity methods. Learn to implement and leverage one-click document RAG for improved accuracy.
Predibase: A Low-Code Deep Learning Platform Built for Scale
Explore Predibase: a low-code deep learning platform combining large-scale ML with state-of-the-art architectures for NLP, computer vision, and tabular data, built on Ludwig and Ray for scalable, end-to-end solutions.
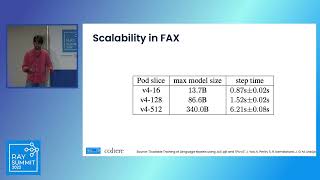
Scalable Training of Language Models Using Ray, JAX, and TPUv4
Explore challenges and design decisions for scalable language model training, with quantitative analysis of efficiency improvements using Ray, JAX pjit, and TPUv4.
Hugging Face and Ray AIR Integration for Scalable Machine Learning
Explore Hugging Face and Ray AIR integration for scalable model training and data loading. Learn to create end-to-end workflows from data ingest to inference and serving.
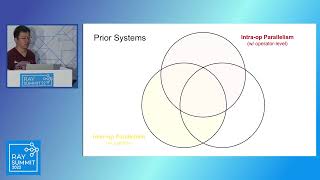
Alpa: Simple Large Model Training and Inference on Ray
Explore Alpa, a Ray-native library for automated model-parallel training of large deep learning models, optimizing execution plans and scaling complex architectures efficiently.
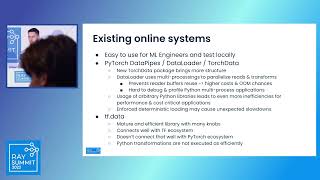
Cruise.data - A New Dataset Processing Pipeline for Cruise ML
Explore Cruise.data, a novel ML data pre-processing framework combining tf.data, PyTorch, and large-scale processing capabilities for efficient and scalable dataset handling in autonomous vehicle development.
Large-Scale Deep Learning to Augment Production RL Workloads at Riot Games
Learn to leverage large-scale deep learning for building game bots, predicting outcomes, and optimizing training processes in game development. Explore supervised learning techniques and scaling with Ray tools.
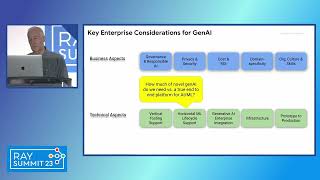
Making Your Enterprise GenAI Ready and GenAI Enterprise Ready
Prepare your organization for GenAI challenges and opportunities. Learn best practices for integrating GenAI capabilities with enterprise security, privacy, and guardrails. Explore Google Cloud's innovative GenAI solutions for enterprise environments.
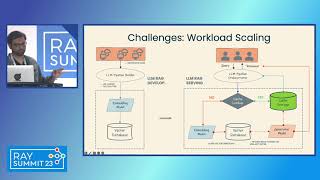
Enterprise Vector-based Information Retrieval and Prompt Engineering at Scale Using Open Source on AWS
Build enterprise-scale vector-based information retrieval systems using open source technologies on AWS, addressing challenges in Retrieval Augmented Generation for accurate, hallucination-free results.
Building Context-Aware Reasoning Applications with LangChain and LangSmith
Explore context-aware reasoning in LLM applications. Learn about cognitive architectures, LangChain, and LangSmith for building differentiated AI products. Gain insights on evaluation and practical techniques.
Fast LLM Serving with vLLM and PagedAttention
Explore vLLM, an open-source library for fast LLM inference using PagedAttention. Learn how it achieves higher throughput and its implementation for efficient AI model serving.

Perplexity AI: Building the World's Best LLM-Powered Search Engine in 6 Months
Explore the engineering challenges and opportunities in building Perplexity.ai, an LLM-powered answer engine, with insights from founder Aravind Srinivas on rapid development and resource optimization.
Easily Scale to Production-Ready Generative AI with NVIDIA and Anyscale
Scale generative AI to production with NVIDIA and Anyscale's partnership. Learn how their combined technologies optimize performance, lower costs, and enable secure deployment of AI services at scale.
Embeddings and Vectors: The Key to Production AI
Explore how teams program AI with data using embeddings and vectors, and learn about future approaches for building production AI applications.
Understanding the Landscape of Latest Large ML Models
Explore the evolving landscape of large ML models, from ChatGPT to open-source projects. Learn how teams use W&B to accelerate development and stay ahead in the rapidly advancing field of AI.
Enabling End-to-End LLMOps on Michelangelo with Ray
Explore Uber's extension of Michelangelo for end-to-end LLMOps, leveraging Ray for scalable development with hundreds of A100 GPUs and integrating open-source techniques for efficient custom LLM creation.