Document Similarity: Langchain Sentence Transformers and Chroma - Spanish
Aprende a clasificar documentos usando Langchain con Sentence Transformers de HuggingFace y Chromadb. Explora técnicas avanzadas de procesamiento de lenguaje natural y similitud documental.
Llama 2, Ollama and Pinecone: Searching in Vector Stores
Instala y utiliza OLLAMA y Pinecone para crear embeddings con LLama2 7B, subir contenido a la base de vectores y realizar consultas eficientes.
VertexAI Embeddings, Pinecone, y Langchain - Creación de un Componente de Recuperación
Aprende a crear un componente de recuperación utilizando VertexAI Embeddings, Pinecone y Langchain para aplicaciones de aprendizaje automático y ciencia de datos.
Integración de NVIDIA NIM con Langchain para RAG Q&A
Explora la integración de NVIDIA NIM con Langchain para crear un componente RAG Q&A utilizando Faiss, mejorando tus habilidades en inteligencia artificial y procesamiento de lenguaje natural.
Langchain: Conversational QA Tool with Gemini, Langchain, and Faiss - Part 2 (Español)
Aprende a mejorar la gestión de la historia y la conciencia contextual en chatbots utilizando Gemini, Langchain y Faiss.
Unlock the Power of Embeddings with Vector Search - Future of Data & AI - Data Science Dojo
Explore embeddings and vector search for unstructured data analysis. Learn to build semantic text and reverse image search systems using Milvus, with real-world applications and best practices.
Vector Databases Explained - Insights, Applications, and Pinecone Tutorial
Explore vector databases, embeddings, and advanced search techniques. Learn how to leverage Pinecone for powerful vector search solutions, with real-world applications and hands-on experience.
Enterprise LLM Applications - Not Just a Technological Challenge
Explore prevalent approaches and architecture for building custom large language model applications, including tools and technologies for enterprise use cases and challenges.
Building a Multi-million Dollar AI Business - Founders Reveal Success Strategies - Part 1
Insights from AI startup founder on building successful tech businesses, from early passion to raising millions. Covers entrepreneurship challenges, company culture, investor relations, and industry differentiation.

Creating an AI-Powered Financial Advisor with Spring AI and RAG
Master building an AI-powered financial document analyzer using Spring AI and RAG (Retrieval Augmented Generation). Implement vector databases, document processing, and intelligent data retrieval in Java applications.
Virtual Data Path Acceleration (vDPA) Integration with Kolla-Ansible OpenStack Deployment
Discover how to enhance OpenStack networking performance through vDPA integration with Kolla-Ansible, exploring implementation strategies, benefits, and real-world performance improvements.
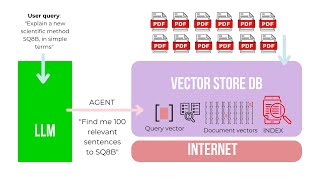
How to Import and Query Large PDF Collections in Language Models
Discover practical techniques for integrating and querying thousands of PDF documents with large language models to enable efficient corporate data analysis and Q&A capabilities.

Teaching Vector Databases at Scale
Discover how vector databases are being integrated into university curricula and online learning platforms, with insights on implementing RAG patterns and scaling database education.
Building the Ultimate Hybrid Search with Qdrant - A Hands-on Tutorial
Master advanced semantic search techniques by transforming dense embedding pipelines into hybrid systems with Qdrant's latest features, including ColBERT models and universal search endpoints.
How Vector Search with Qdrant Improves Workplace Efficiency
Discover how vector search technology and Qdrant power modern work environments, exploring implementation, scaling challenges, and practical applications in AI-driven business solutions.
Indexify Unveiled: A Scalable Content Extraction Engine for Multimodal Data
Discover how Indexify enables scalable content extraction and real-time knowledge base creation for AI workflows, focusing on unstructured data processing and hybrid search capabilities.
Superpower Your Semantic Search Using Vector Database - From Model Architecture to Deployment
Discover how to enhance matching systems using vector databases, focusing on implementation, deployment, and optimization for improved search performance and scalability in production environments.
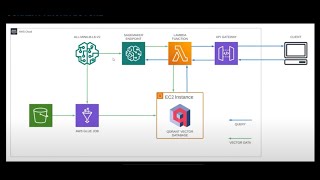
High-Performance Entity Matching Solution Using Vector Embeddings and AWS
Discover how to build a high-performance hotel matching system using vector embeddings, AWS infrastructure, and Qdrant for efficient data processing and improved accuracy in the travel industry.
Binary Quantization Methods for Vector Database Optimization
Dive into vector database optimization through binary quantization, exploring compression techniques, search speed improvements, and practical implementation strategies for efficient vector similarity search.
Building a Semantic Search App for Music Using Qdrant Cloud
Learn to develop a semantic search application using Qdrant Cloud's Python SDK to efficiently search through thousands of songs across different music genres.
Music Recommendation System with Qdrant Vector Search and Audio Embeddings
Learn to build a music recommendation engine using Qdrant's vector search capabilities, audio embeddings, and metadata to create personalized song suggestions.