Unlocking Real-World LLM Use Cases - Techniques for Accurate Results
Explore real-world LLM applications, overcome limitations, and leverage techniques like RAG to ground results. Learn to bridge LLMs with enterprise Gen AI apps using vector-supported databases.
Navigating via Retrieval Evaluation to Demystify LLM Wonderland
Explore retrieval evaluation's crucial role in LLM applications, focusing on its impact on response quality. Delve into the link between retrieval accuracy and answer quality, emphasizing thorough evaluation methods.
Solving LLM Data Problems with Vector Databases - Part 2
Explore vector databases' role in LLM apps, focusing on solving data issues and democratizing access to this technology for efficient billion-scale vector search.
vDPA-net Live Migration with Shadow Virtqueue
Explore vDPA device migration using Shadow Virtqueue. Learn about high-performance data processing offloading, unified interfaces, and simplified workload scaling across different device types.
Question Answering over Documents with RAG - Lecture 6.4
Explore Retrieval-Augmented Generation (RAG) to enhance LLMs with external data, improving accuracy and relevance in corporate settings. Learn to set up and query a RAG system using sample employee data.
Developing Local AI Copilots with LangChain, NVIDIA NIM, and FAISS - LLM App Development
Learn to build a local AI copilot using LangChain, NVIDIA NIM, and FAISS. Covers document processing, vector storage, inference with Llama 3, and LangChain orchestration for responsive LLM applications.
Retrieval-Augmented Generation: Enhancing AI Models - Lecture 7
Explore Retrieval-Augmented Generation (RAG): theory, components, and practical implementation. Enhance AI models' capabilities with this comprehensive overview for beginners and enthusiasts alike.
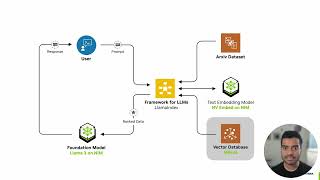
Building LLM Assistants with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to create a Q&A chatbot using NVIDIA NIM for embeddings, Milvus for storage, Llama3 for inference, and LlamaIndex for seamless integration in this comprehensive tutorial.
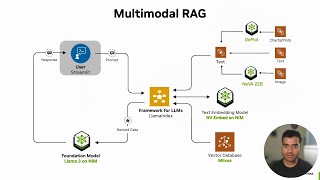
Building Multimodal AI RAG with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to build a multimodal AI RAG application using LlamaIndex, NVIDIA NIM, and Milvus. Covers document processing, vector database integration, inference with Llama 3, and seamless orchestration for efficient Q&A experiences.
RAG from Scratch with Llama 3.1 - Building a Custom Data Chatbot
Hands-on tutorial for building a RAG system from scratch using Llama 3.1, Groq API, Sqlite-vec, and FastEmbed. Learn to create a chatbot with custom data without external libraries.
Building a Production Scale, Totally Private, OSS RAG Pipeline with DBRX, Spark, and LanceDB
Discover how to create a secure, scalable AI pipeline using open-source tools DBRX, Spark, and LanceDB. Learn to implement private generative AI solutions for enterprises without compromising data security or performance.

Chunking Strategies in RAG - Optimizing Data for Advanced AI Responses
Explore advanced chunking strategies for RAG applications, including character, recursive, document-based, semantic, and agentic methods to optimize AI responses and improve data processing efficiency.
Creating an Autonomous AI App with AutoRAG and PhiData
Learn to build an AutoRAG system with PhiData, enhancing AI's decision-making for relevant responses. Covers setup, knowledge base creation, querying, and UI development for improved AI interaction.

RAG from the Ground Up with Python and Ollama - Building a Document Interaction System
Build a RAG system with Python and Ollama: parse documents, create embeddings, implement relevance scoring, and enable LLM interaction with your own datasets.
KubeVirt vDPA Workflow - From Host to Pod to Domain
Explore KubeVirt vDPA workflow, from host to pod to domain, with insights on cloud native computing and virtualization technologies for enhanced network performance and efficiency.
Web Dev Challenge: Building AI-Powered Apps Beyond Chatbots - Episode 1
Web developers compete to create innovative AI-powered apps using Astra DB in a 4-hour challenge, showcasing unique applications beyond traditional chatbots.
A Fun and Absurd Introduction to Vector Databases
Explore vector databases for AI applications, natural language interfaces, and advanced search capabilities. Learn to translate data into vectors and master querying techniques.
Vector Databases 101 - How Do They Work?
Explore vector databases' functionality, applications, and architecture. Learn about similarity search, indexing techniques, and real-world use cases in machine learning and AI.
Retrieval, Search and Knowledge in the Age of LLMs and Vector Databases
Explore vector embeddings' impact on information compression, search, and knowledge retrieval. Learn how enterprises can leverage this technology to enhance customer understanding and interaction.
Making RAG Work - Building Robust Retrieval Augmented Generation Systems
Dive into practical techniques for implementing robust RAG systems, exploring common pitfalls, optimization strategies, and design principles for production-ready LLM applications.
Multimodal RAG with LangChain, VertexAI, Gemini Pro and Chroma
Aprende a construir aplicaciones RAG multimodales utilizando LangChain, VertexAI y Chroma para procesar eficientemente datos no estructurados como PDFs e imágenes.