How to Code Long-Context LLMs - LongLoRA Implementation with Llama 2 100K
Dive into fine-tuning techniques for extending LLM context lengths using LongLoRA, featuring practical implementation on Llama 2 and Flash Attention 2 optimization for handling extensive sequences.
Reinforcement Learning: From Policy Optimization to Multi-Agent Systems
Explore reinforcement learning fundamentals, from reward systems and policy optimization to transformer architectures in robotics and multi-agent systems, with practical implementation insights.
Introduction to KERAS 3 Core for PyTorch and JAX
Explore KERAS 3's framework-agnostic capabilities for building neural networks and transformers across TensorFlow, PyTorch, and JAX platforms with advanced customization options.
Textbooks Are All You Need - Understanding Microsoft's Phi-1.5 Model
Discover Microsoft's Phi-1.5, a compact yet powerful transformer-based language model that achieves remarkable performance despite its smaller size compared to other recent LLMs.
LongNet: Understanding Transformer Scaling to 1 Billion Tokens - A Technical Overview
Dive into Microsoft's LongNet transformer architecture, exploring how dilated attention mechanisms enable processing of billion-token sequences and advance the field towards artificial general intelligence.
Machine Learning Career Roadmap 2024 - From Beginner to Expert
Discover a comprehensive YouTube learning path for mastering Machine Learning and AI, from mathematical foundations to specialized areas like NLP and Computer Vision - all through free resources.
Getting Started with HuggingFace Transformers - Pipeline, Tokenizer, and Model Development
Master HuggingFace Transformers library fundamentals, from pipelines and tokenizers to models and Hub integration, enabling you to effectively work with and fine-tune Large Language Models.
LoRA: Low-Rank Adaptation for Parameter-Efficient Large Language Model Fine-Tuning
Discover how LoRA enables efficient fine-tuning of large language models through low-rank adaptation, from fundamental concepts to practical implementation in transformer architectures.
How ChatGPT is Trained - Model and Training Explained
Delve into the technical foundations and training methodology behind ChatGPT, exploring its model architecture, reinforcement learning principles, and step-by-step training process.
Understanding Grokking - A New Performance Phase in Large Language Models
Discover how extended training of LLMs leads to "grokking" - a breakthrough phase where models develop superior generalization abilities and form geometric patterns in embedding spaces.
NEFTune - Improving LLM Performance Through Noisy Embeddings Fine-Tuning
Discover how NEFTune's innovative instruction fine-tuning method enhances LLM performance through noisy embeddings, with practical implementation in HuggingFace TRL.
Fine-tuning Flan-T5 LLM with HuggingFace Accelerate - Tutorial
Learn how to fine-tune Flan-T5 LLM using HuggingFace Accelerate for multi-GPU environments, with step-by-step guidance on preprocessing and implementation for specific downstream tasks.
Creating Perfect YouTube Subtitles with Whisper Speech-to-Text AI
Learn how to create accurate multilingual YouTube subtitles using Whisper AI's speech-to-text technology, with step-by-step Python implementation and optional language fine-tuning capabilities.
Fine-tuning T5 LLM for Text Generation and Summarization - Complete Tutorial
Master T5 LLM fine-tuning techniques for text summarization through hands-on coding in Google Colab, using practical examples and real-time implementation with Hugging Face.
BLIP-2: Connecting Vision-Language Models with Q-Former for Image Chat
Explore BLIP-2's innovative approach to combining vision and language models through Q-Former, enabling advanced image-based conversations and multimodal AI interactions.
The Art of Text to Vector Transformation - A Comprehensive Look at AI and NLP Transformers
Dive into the fundamentals of converting text to mathematical vectors, understanding tokenization methods like BERT and BPE for NLP applications and AI transformer models.
Running Flan-T5-XL Model on Google Colab - A Free Self-Explaining Language Model
Discover how to implement and optimize the Flan-T5-XL language model on Google Colab, exploring its capabilities in reasoning, essay writing, and translation tasks while working within free resource constraints.
Domain-Specific AI Models - Creating Customized BERT and SBERT Models for Business Applications
Discover how to effectively train and fine-tune BERT and SBERT models for specialized domains, focusing on medical and biochemical terminology, with practical solutions for business applications.
Feature Vectors - Understanding BERT and SBERT Transformer Models
Dive into feature vectors and their crucial role in BERT and SBERT transformer models, exploring vectorization techniques, Python implementation, and practical applications in NLP.

Panoptic Image Segmentation - Understanding Mask2Former
Dive into Mask2Former's universal approach to image segmentation, covering instance, semantic, and panoptic segmentation techniques with practical examples and implementations.
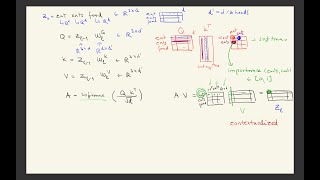
Pairwise Feature Importance and Effective Attention in Self-Attention Networks
Dive into advanced concepts of attention mechanisms, exploring effective attention computation, norm-based analysis, and practical applications in neural networks.