No Train No Gain - Revisiting Efficient Training Algorithms for Transformer-based Language Models
Delve into efficient training algorithms for Transformer models, exploring dynamic architectures, batch selection, and optimizers while examining their effectiveness against baseline methods.
Synthesizer - Rethinking Self-Attention in Transformer Models
Explores alternative attention mechanisms in Transformer models, proposing the Synthesizer model that learns synthetic attention weights without token-token interactions, showing competitive performance across various NLP tasks.

Pytorch Transformers from Scratch - Attention Is All You Need
Implement Pytorch Transformers from scratch, exploring the "Attention is all you need" paper. Learn attention mechanisms, encoder-decoder architecture, and practical application.
Emerging Properties in Self-Supervised Vision Transformers - Paper Explained
Explore DINO: self-supervised vision transformers with emerging properties like segmentation mask prediction and high-quality features for k-NN classification. In-depth analysis of methodology, results, and visualizations.
Attention Is All You Need - Transformer Paper Explained
Detailed walkthrough of the original transformer architecture, covering tokenization, embeddings, attention mechanisms, and decoding, with a focus on machine translation applications.
Developing a Deep Learning Project - Case Study on Transformer
Explore the development process of a transformer model, from project planning to implementation challenges, with insights on time management, data handling, and optimization techniques.

The Spelled-Out Intro to Language Modeling - Building Makemore
Comprehensive tutorial on building a bigram character-level language model, covering tensor operations, neural networks, and PyTorch fundamentals for natural language processing tasks.
DeBERTa - Decoding-Enhanced BERT with Disentangled Attention
Explore DeBERTa, an advanced BERT model with disentangled attention and enhanced mask decoder, surpassing RoBERTa in NLP tasks. Learn about its architecture, improvements, and performance gains.
Nyströmformer- A Nyström-Based Algorithm for Approximating Self-Attention
Explore Nyströmformer, a novel algorithm for approximating self-attention in Transformers with linear complexity, enabling processing of longer sequences and improving scalability in natural language tasks.
Feedback Transformers - Addressing Some Limitations of Transformers with Feedback Memory
Explores Feedback Transformers, an architecture that improves on standard Transformers by allowing higher-level representations to inform lower-level processing, enhancing performance on complex reasoning and long-range dependency tasks.
Transformer Memory as a Differentiable Search Index - Machine Learning Research Paper Explained
Explore a novel approach to information retrieval using a single Transformer model that encodes corpus information in its parameters, enabling direct query-to-document mapping without external indices.
Train Short, Test Long - Attention With Linear Biases Enables Input Length Extrapolation
ALiBi: A novel attention mechanism enabling transformers to process longer sequences than trained on. Uses linear biases instead of position encodings, improving efficiency and extrapolation capabilities.
XCiT- Cross-Covariance Image Transformers - Facebook AI Machine Learning Research Paper Explained
Explore XCiT, a novel Transformer architecture for computer vision using cross-covariance attention. Learn about its linear complexity, scalability, and performance across various vision tasks.
Long Form Question Answering in Haystack
Explore long-form question answering using Haystack, covering setup, data indexing, and generating responses. Learn to implement QA systems for efficient information retrieval in organizations.
Spotify's Podcast Search Explained
Explore Spotify's innovative podcast search system using natural language processing and learn to implement a similar solution with transformer models and vector search techniques.
Building Transformer Tokenizers - Dhivehi NLP #1
Learn to build an effective WordPiece tokenizer for Dhivehi, a low-resource language, overcoming unique challenges in NLP application. Explore tokenizer components, implementation, and usage for this fascinating language.
A Gentle Visual Intro to Transformer Models
Explore key concepts of Transformer models, including encoder, decoder, and attention, through a visual and accessible explanation by ML expert Jay Alammar.
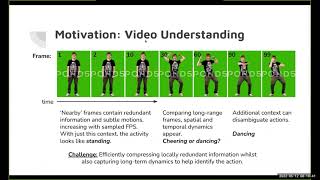
UniFormer
Explore video understanding with UniFormer, a novel approach addressing inefficiencies in video transformers for improved performance and pose estimation.
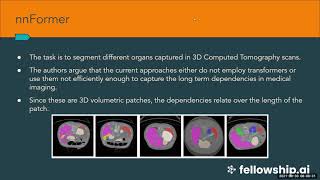
Not Another Transformer, NNFormer Explained!
Explore nnFormer, a novel AI model architecture, its envelope, mass data handling, and experimental results in this comprehensive overview.

Neural Nets for NLP 2017 - Attention
Comprehensive exploration of attention mechanisms in neural networks for NLP, covering various types, improvements, and applications, with a focus on the Transformer model.
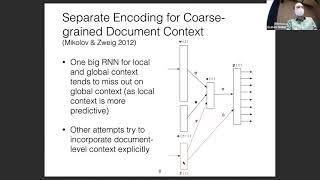
CMU Advanced NLP: Document-Level Modeling
Explore advanced NLP techniques for long documents, including feature extraction, coreference resolution, and discourse parsing. Gain insights into state-of-the-art models and their applications.