Accelerate PyTorch Workloads with PyTorch/XLA
Optimize PyTorch performance on Google Cloud AI Accelerators using XLA compiler. Learn about high-speed training and inference for LLaMA 2 and LLM fine-tuning with PyTorch Lightning.
Workload-Optimized and AI-Powered Infrastructure for Google Cloud
Optimize AI workloads and enterprise applications with purpose-built infrastructure. Learn about supercomputing innovations, TPUs, GPUs, and AI-powered assistance for efficient operations.
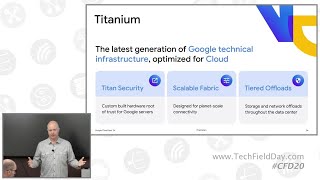
Running Enterprise Workloads in Google Cloud - Optimizing Infrastructure and Performance
Discover how Google Cloud optimizes enterprise infrastructure through Titanium technology, offering enhanced performance, reliability, and cost efficiency for VMware, SAP, and Microsoft workloads.
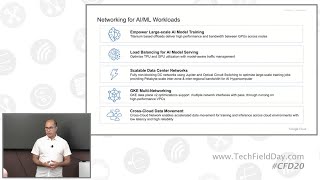
Google Cloud Network Infrastructure for AI and Machine Learning
Discover how Google Cloud's advanced network infrastructure enables efficient AI/ML workloads through dual-network architecture, hardware acceleration, and intelligent load balancing for optimal performance and scalability.
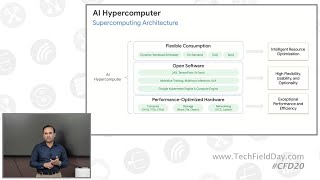
AI Workloads and Hardware Accelerators - Introducing the Google Cloud AI Hypercomputer
Discover how Google Cloud's AI Hypercomputer revolutionizes AI workload management with advanced GPUs, TPUs, and dynamic scheduling, enabling efficient, scalable, and sustainable enterprise AI solutions.
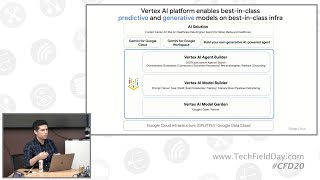
Introduction to Google Cloud Vertex AI Platform - Enterprise AI Development and Deployment
Discover how Vertex AI leverages TPUs and transformer architecture to enable multimodal AI processing across text, images, audio, and video, with enterprise-ready features for secure, customizable AI implementation.
Accelerate AI Inference Workloads with Google Cloud TPUs and GPUs
Optimize AI inference using Google Cloud's TPUs and GPUs. Compare accelerators for various workloads, deploy efficiently, and implement cost-effective strategies for high-performance model deployment.
Accelerate AI Training Workloads with Google Cloud TPUs and GPUs
Explore key considerations for choosing TPUs and GPUs, optimize AI training workflows, and discover best practices for performance and cost-effectiveness on Google Cloud.
Take Large Scale AI from Research to Production with Google Cloud's AI Hypercomputer
Discover Google Cloud's AI Hypercomputer: a supercomputing architecture optimizing hardware, software, and consumption models for efficient AI deployment at scale. Gain insights from Kakao Brain and Nuro's experiences.
Brag Your RAG with MLOps - Building Scalable GenAI Solutions on Kubernetes
Discover how to build and deploy scalable RAG applications using LangChain, Canopy, and PostgreSQL Vector database on Kubernetes, while implementing effective MLOps strategies for GenAI solutions.

Building Scalable AI Infrastructure with KubeRay and Kubernetes
Master scalable AI infrastructure deployment using KubeRay and Kubernetes, covering gang scheduling, distributed checkpointing, and integration with cloud providers for efficient AI workload management.
WebAssembly Based AI as a Service on the Edge with Kubernetes
Discover how to deploy machine learning models as serverless functions using WebAssembly and Kubernetes at the edge, focusing on WasmEdge runtime and WASI for optimal performance and security.