Using Python to Power Serverless Applications
Explore best practices for building serverless solutions with Python, focusing on API calls, streaming data, and ML inference. Learn techniques for production-grade systems with observability.
Choosing the Right Database for Your Next Project - Looking at Options Beyond PostgreSQL and MySQL
Explore diverse database options beyond PostgreSQL and MySQL, covering relational, data warehouse, analytics, and machine learning solutions to find the best fit for your Python project.
Introduction to Azure Data Bricks - Cloud
Explore Azure Databricks for big data processing, advanced analytics, and real-time insights. Learn platform basics, architecture, and integration with Azure components for data-driven solutions.
Getting Started with Combine
Comprehensive introduction to Apple's Combine framework, covering reactive programming concepts, key components, and practical applications in iOS development.
Real-Time Object Detection with Pravega and Flink
Explore real-time object detection using Pravega and Apache Flink, leveraging Dell EMC Streaming Data Platform and ObjectScale for enterprise-grade streaming and storage on VMware Cloud Foundation.
Data in Motion - Streaming Static Data Efficiently in Akka Persistence
Explore efficient streaming of static data in Akka Persistence, focusing on architecture, implementation, and performance tuning for distributed systems and enterprise applications.
Akka Streams for High Throughput Data Processing
Explore high-throughput data processing with Akka Streams, comparing it to Akka Actors. Learn best practices, optimization techniques, and when to switch to Streams for improved performance in large-scale data transfer systems.
Onyx: Functional, Distributed Data Processing for Clojure
Explore Onyx's masterless coordination for distributed data processing in Clojure. Learn about its architecture, consensus mechanisms, and fault tolerance in network partitions and machine failures.
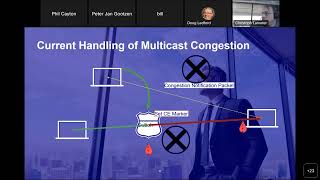
Congestion Management for Multicast on ROCE v2 - Implementing Backpressure Mechanisms
Explore RDMA multicast migration from InfiniBand to Ethernet (ROCE v2), focusing on congestion management techniques like ECN and Cisco Pause Frames for reliable data transmission.
Efficient Detection of Multivariate Correlations in Static and Streaming Data
Discover efficient algorithms for detecting multivariate correlations in data systems, exploring novel approaches that outperform existing methods by analyzing static and streaming datasets.
High Throughput Data Processing with GenStage
Explore Elixir's building blocks for efficient data ingestion, covering backpressure, partitioning, retries, and batching techniques for large-scale processing.
Creating Self-Service, High-Velocity Data Cultures
Discover processes, platforms, and personnel needed to transform data culture into self-service, proactive insights. Learn to leverage data as a competitive advantage across business facets.
Apache Kafka Real-Time Personalization Architecture
Explore real-time personalization architecture using Apache Kafka and Spark for advanced content recommendation systems in data engineering and AI.
State Reader API: The New "Statestore" Data Source for Structured Streaming
Explore Databricks' State Reader API for accessing and analyzing Structured Streaming's internal state data, aiding development and troubleshooting of stateful workloads in Apache Spark 4.0.0.
Accelerating Adoption of Data Lake for Streaming and Machine Learning Use Cases
Discover tools and features for efficient Databricks adoption in ML and streaming, focusing on automation and operational efficiency to accelerate implementation of Delta and Spark compute workloads.
Honeywell Intelligrated's IoT Streaming Lakehouse for Warehouse Automation
Explore Honeywell Intelligrated's journey in launching IoT streaming services for warehouse automation, utilizing Databricks Lakehouse for data governance, processing, and AI-driven solutions.
Seamless Flow: Evolving From Batch to Streaming Data Flows Using DLT
Explore how 84.51° leverages Delta Live Tables to evolve data flows from batch to streaming, combining real-time and historical data for enhanced retail insights and customer-centric strategies.
From Zero to Hero with Kafka Connect
Explore Kafka Connect's power in integrating data systems, from basics to advanced techniques for efficient and scalable data pipelines.
Bulletproof Java Enterprise Applications for The Hard Production Life
Strategies for building resilient Java Enterprise applications in production, covering circuit breakers, bulkheads, backpressure, and telemetry using MicroProfile and service meshes.
The Data Lakehouse for Streaming Data - A Talk for Everyone Who Loves Data
Explore data lakehouses: combining data lakes and warehouses for reliable, flexible data management. Learn about open-source projects, streaming data support, and see a live Twitter sentiment analysis demo.

Real-Time Analytics for Small Data Teams
Discover strategies for implementing real-time analytics with limited resources. Learn from Materialize's adoption experience and optimize data workflows for efficiency and cost-effectiveness.