
Unlocking the Power of Apache Flink - An Introduction in 4 Acts
Explore Apache Flink's core principles for real-time data processing, including shared-nothing architecture, event-time processing, and state snapshots, through practical examples and demos.
Streaming vs. Batch Processing: The Future of Data Architecture
Explore the future of data processing with industry experts as they debate streaming vs. batch, adoption challenges, and best practices for real-time data architecture.
Is Flink SQL a Database? Understanding Apache Flink SQL
Explore Apache Flink SQL's unique approach to stream processing, adapting database concepts like queries and materialized views for real-time data analysis and processing.
Scaling Business with Real-Time ML in Microsoft Fabric Real-Time Analytics
Leverage ML on real-time data to scale business operations using Microsoft Fabric Real-time Analytics. Deep-dive into technical aspects for optimizing performance and decision-making.
Stream Processing Solution for the Enterprise - Apache Flink Implementation and Support
Explore enterprise-level stream processing with Apache Flink. Learn about lifecycle management, SQL development, multi-tenancy, security, and deployment options for robust, scalable solutions.
Producing Apache Kafka Messages Using Apache Flink and Java
Learn to produce Apache Kafka messages using Apache Flink and Java in this comprehensive walkthrough. Covers Flink job setup, Kafka configuration, data generation, serialization, and execution verification.
Event Time and Watermarks in Apache Flink
Explore event time, processing time, and watermarks in Apache Flink for effective stream processing and window operations.
Realtime Stock Market Anomaly Detection Using Machine Learning - End-to-End Data Engineering Project
Develop an end-to-end data engineering project for real-time stock market anomaly detection using Quix Streams, Redpanda, and Docker. Learn to build a complete data pipeline and deploy an advanced ML model.
Introduction to Databricks Delta Live Tables
Accelerate data pipeline development with Databricks Delta Live Tables. Learn setup, ingestion, table creation, pipeline execution, and data validation for faster, more reliable projects.
Building Stream Processing Applications with Ruby and Meroxa - RubyConf 2022
Explore real-time stream processing using Ruby and the Turbine framework. Learn to build and deploy sophisticated applications without complex tooling or unfamiliar paradigms.
Data Enrichment Patterns with Apache Flink
Explore common data enrichment patterns for streaming data using Apache Flink. Learn implementation techniques for static, API-based, and change data stream scenarios, with insights into Flink's state management.
Understanding Stream-Table Duality Using Kafka, Flink SQL and Debezium Format
Explore stream-table duality using Kafka, Flink SQL, and Debezium format. Learn about CDC events, SQL queries on changelog data, and practical applications through a demo.
Unlocking Financial Data with Real-Time Pipelines Using Apache Technologies
Discover how to build powerful real-time data pipelines using Apache Flink, NiFi, Kafka, and Iceberg for processing financial data efficiently, enabling swift decision-making and regulatory compliance.
Reinventing Kafka in the Data Streaming Era
Explore Apache Kafka's evolution in modern data streaming, from core architecture to cloud-native innovations and exactly-once semantics for real-time enterprise applications.
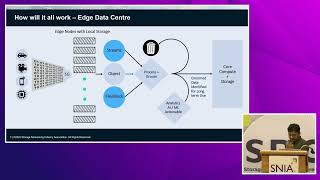
Cloud Native Storage Services for Edge Computing - Understanding Data Sources and Architectures
Explore cloud-native storage architectures for edge computing, covering data types, storage services, and operating models across far edge, enterprise edge, and network edge environments.
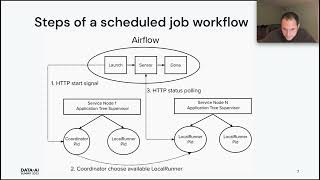
Elixir for Data Engineering - Batch and Stream Processing
Discover how Elixir can revolutionize data engineering with distributed processing, Airflow integration, and Kafka event handling. Learn practical examples for efficient batch and stream processing.
Demystifying Stream Processing with Apache Kafka
Demystifying stream processing with Apache Kafka, exploring key features, benefits, and challenges. Introduces Kafka Streams library, highlighting its unique design decisions and tradeoffs in the stream processing landscape.
Reactive Streams - Handling Data-Flows the Reactive Way
Explore reactive streams for handling data flows, focusing on back-pressure and distributed processing. Learn principles, examples, and implementations using Akka and Java 8.

Full-Stack Flux Architecture in React.js - React.js Conf 2015
Explore full-stack Flux architecture, its advantages in scaling actions and queries, and how it can revolutionize backend development for more efficient and scalable web applications.
RocksDB Usage at LinkedIn - FollowFeed and Apache Samza
Explore LinkedIn's use of RocksDB in FollowFeed and Apache Samza, covering architecture, performance, and real-world experiences with this powerful database system.
Building WASM-Powered Distributed Stream Platform
Explore WASM-powered distributed stream processing with Fluvio, enabling efficient in-line computation and deployable anywhere. Learn about SmartModule integration and its benefits for various use cases.