Better Understanding of Non-convex Methods in Machine Learning
Exploring non-convex optimization in machine learning, focusing on matrix completion and neural network architectures. Insights into algorithmic approaches for complex, high-dimensional models.
Neural Networks For Your Dog
Learn to build neural networks from scratch in Python, covering perceptrons, gradient descent, and deep learning concepts through simple, engaging explanations and hands-on coding.
What You Always Wanted to Know About Deep Learning, but Were Afraid to Ask
Demystifying deep learning concepts like back-propagation, gradient descent, and neural networks. Practical guide to training a model for object recognition using TensorFlow and Keras.
Turtles! Hill Climbing! Hammers! Paper Bags!
Explore optimization techniques through turtle graphics, from hill climbing to simulated annealing, laying the groundwork for understanding neural networks and machine learning concepts.
A Gentle Introduction to Data Science
Explore data science fundamentals, from AI's influence to practical machine learning in Python. Covers key concepts, problem-solving applications, and essential Python tools for aspiring data scientists.
Where Does Negative Transfer Come From? On the Implicit Bias of SGD in Multi-Task Learning
Explore negative transfer in multi-task learning, examining task conflict, optimization temperature, and SGD's implicit bias. Gain insights into generalization challenges in neural networks.
The Long-Run Distribution of Stochastic Gradient Descent: A Large Deviations Approach
Explore the long-run behavior of stochastic gradient descent in non-convex problems, analyzing state space visitation patterns and energy level distributions.
Stochastic Algorithms for Constrained Continuous Optimization
Explore stochastic-gradient-based algorithms for constrained continuous optimization, focusing on interior-point and sequential-quadratic-programming methods with convergence guarantees and practical applications.
Hessian-Aware Stochastic Differential Equation Modeling of SGD
Explore a novel SDE model for SGD that incorporates Hessian information, improving accuracy in capturing escaping behaviors and achieving exact recovery for quadratic objectives.
The First Optimal Distributed SGD in the Presence of Data, Compute and Communication Heterogeneity
Explore optimal time complexities for parallel optimization methods with heterogeneous data, compute, and communication. Gain insights into efficient distributed SGD algorithms.
Phase Diagram of Stochastic Gradient Descent in High-Dimensional Two-Layer Neural Networks
Explore the phase diagram of Stochastic Gradient Descent in high-dimensional two-layer neural networks, focusing on its behavior and implications.
Haskell for Choice-Based Learning in Machine Learning Programming
Explore language design for machine learning, focusing on choice-based learning. Combine algebraic effects, handlers, and selection monad to create powerful frameworks for decision-making models and optimization techniques.

Methods of Optimization in Machine Learning
Explore optimization techniques for machine learning models, including gradient descent and stochastic methods. Learn to adjust hyperparameters and minimize cost functions effectively.
Non-convex SGD and Lojasiewicz-type Conditions for Deep Learning
Explore non-convex SGD and Lojasiewicz-type conditions for deep learning in this mathematical conference talk by Kevin Scaman at CIRM.
Functional Programming and Scala for Machine Learning - YOW! 2015
Explore how functional programming and Scala can revolutionize machine learning, offering strongly-typed solutions for efficient algorithm implementation and scalable data processing.
SGD and Weight Decay Secretly Compress Your Neural Network
Explore how SGD and weight decay techniques compress neural networks, enhancing efficiency and performance in deep learning models.

Stochastic Gradient Descent Methods with Biased Estimators
Explore recent advancements in stochastic gradient descent methods, focusing on biased estimators for large-scale optimization and minimax problems in machine learning applications.
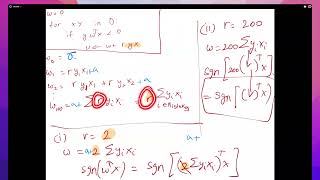
Least Mean Square Regression for Machine Learning - Lecture 11
Dive into least mean square regression, exploring loss function minimization and gradient descent methods for effective linear regression implementation and optimization.
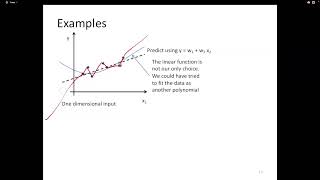
Linear Regression and Least Mean Square Method - Lecture 11
Master linear regression fundamentals through least mean square method, loss function minimization, and gradient descent techniques for practical machine learning applications.
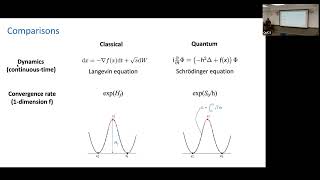
Quantum Speedups for Nonconvex Optimization via Quantum Tunneling Walks
Explore quantum speedups for nonconvex optimization using quantum tunneling walks. Learn how this approach outperforms classical algorithms in specific landscapes with high, thin barriers between minima.
Random Matrices and Dynamics of Optimization in Very High Dimensions - Lecture 3
Explorez les dynamiques d'optimisation en très haute dimension et leur application en apprentissage automatique, en mettant l'accent sur les matrices aléatoires et les statistiques résumées.