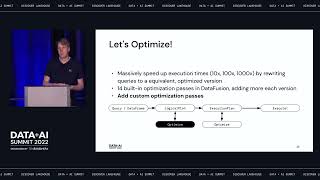
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Using SQL Views in Databricks and Apache Spark - Lesson 12
Learn to create and utilize SQL views in Databricks for efficient data analysis and pipeline reuse. Explore common table expressions, aggregations, and case statements for advanced querying techniques.
Cyber & Data - What is Data?
Explore data types, formats, and structures in cybersecurity. Learn parsing, encoding, compression, and file analysis techniques for effective data handling and security.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
Slowly Changing Dimensions Type 2 in Data Lakes - Tech Chat
Explore Slowly Changing Dimensions Type 2 in data lakes using Delta Lake, focusing on market segmentation for a climbing eCommerce site. Learn to track historical and current data effectively.
Orchestration Made Easy with Databricks Workflows
Discover Databricks Workflows: a managed orchestration service for streamlined data pipelines. Learn to create, run, and monitor reliable workflows, implement recovery actions, and explore new features for efficient data management.
Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.
How to Become a Practical Data Scientist with Kaggle Learn
Discover a comprehensive, free path to becoming a practical data scientist using Kaggle Learn's step-by-step courses, covering Python, machine learning, data visualization, and more.
Introducing Prestissimo: Presto's Next-Gen Query Execution Engine
Explore Prestissimo, Presto's new C++ query execution engine, offering improved performance, reliability, and efficiency for data analytics and open data lakehouses.
Getting Started with Delta Lake
Learn to create a Lakehouse architecture with Delta Lake, an open-source storage framework. Explore data reliability challenges, hands-on examples, and benefits for big data use cases in modern data engineering.
Breaking Out of the Proprietary Cage - Real-time Data Warehouses in Open Source
Explore real-time data warehouses in open source, focusing on ClickHouse's architecture, performance optimization, and integration patterns for modern analytics applications.
Real-time Trade Data Processing and Machine Learning at Giga-Scale with Hazelcast and FINOS Perspective
Explore scalable real-time trade data processing using Hazelcast and FINOS Perspective. Learn to architect high-performance applications combining streaming data, reference data, and machine learning for front and back office use-cases.
Ace the SQL and Data Science Interview - Complete Interview Prep - SQL Interview Tips and Tricks
Expert insights on acing data science and SQL interviews, covering technical questions, case studies, and strategies to stand out in the competitive job market.
MySQL Up and Running - MySQL Tutorial for Beginners - Learn SQL
Learn to set up and use MySQL for data science, covering RDBMS basics, deployment, interfacing, and practical dataset examples. Gain essential SQL skills for working with structured data in real-world scenarios.
Data Manipulation with Dplyr
Learn efficient data manipulation using dplyr in R. Master essential functions for filtering, aggregating, and joining datasets, enhancing your data analysis skills with practical examples.
Microsoft Access 2021 - Beginner to Advanced Tutorial Course
Comprehensive training on database creation, management, and advanced features in Microsoft Access 2021, covering interface customization, data import, relationships, and macros for efficient data handling.
Data Analytics and Generative AI
Explore how generative AI revolutionizes data analytics, streamlining tasks, transforming workflows, and ensuring ethical practices. Gain practical insights and real-world applications for data professionals.
Simplify End-to-End MLOps with PostgresML
Discover how SQL and PostgresML simplify MLOps workflows, streamlining AI/ML project management from development to deployment and monitoring in production environments.

Data Science: Complete Roadmap to Become a Data Scientist
Comprehensive roadmap to becoming a data scientist, covering essential skills, tools, and resources. Includes job prospects, learning strategies, and recommended books for career advancement.
Algebraic Structures in Logic and Query Evaluation - Lecture 3
Explore algebraic structures in logic and query evaluation, focusing on advanced concepts and their applications in database theory and AI.