Hardware Aware Training for Efficient Keyword Spotting - tinyML Research Symposium 2021
Explore hardware-aware training for efficient keyword spotting, focusing on Legendre Memory Unit networks to achieve state-of-the-art accuracy and power efficiency on various hardware platforms.
Practical Adversarial Attack Against Speech Recognition Platforms
Explore techniques for adversarial attacks on speech recognition systems, focusing on Amazon Echo and Kodi. Learn about blackbox approaches and philosophical implications.
The Digital Hearth: An Automated Group Speech-to-Text System for Community Conversations
Explore an innovative group conversation recording device designed to capture and analyze community discussions, featuring offline operation and advanced speech recognition capabilities.
Common Voice: Mozilla's Multilingual Speech Dataset Initiative
Mozilla's Common Voice initiative expands to multiple languages, aiming to crowdsource diverse voice datasets for speech technology development. The project seeks global participation to make voice recognition accessible in various languages.
Mozilla's DeepSpeech and Common Voice Projects - Open and Offline-Capable Voice Recognition
Explore Mozilla's DeepSpeech and Common Voice projects for open, offline voice recognition. Learn about data preparation, development, and multilingual support in this FOSDEM presentation.
Tricks Learned from Scaling WhisperSpeech Models to 80k+ Hours of Speech
Scaling WhisperSpeech: Insights on optimizing AI models for high-quality text-to-speech, covering GPU utilization, multi-GPU training, data handling, and hardware considerations.
Local Tiny AI Vision Language Model - Impressive Capabilities
Explore a compact, local AI vision-language model capable of text analysis, video interpretation, and speech-to-speech conversion, showcasing impressive capabilities in various tests.

AI for Everyone - Learn Modern Artificial Intelligence from Scratch
Learn to effectively use AI for daily tasks and build amazing apps, covering basics to advanced topics like prompt engineering, GPU usage, and app development.
Community Driven Data Collection and Consent in AI
Exploring ethical AI data collection through community-driven models, focusing on consent and linguistic diversity. Examines Common Voice project and alternative approaches for a more inclusive AI future.
Future of Intelligent Cluster Ops - LLM-Powered Kubernetes Controllers
Explore AI-powered Kubernetes controllers using LLMs for automated cluster operations, upgrades, and troubleshooting. Witness live demos of speech-enabled controllers for auditing, chaos simulation, and security scanning.
Voice AI for Work and Life - Transforming Communication and Efficiency
Explore AI's potential to revolutionize communication by capturing voice data, enhancing efficiency, and introducing AI avatars for improved knowledge sharing and organizational transparency.
What's New in Wolfram Image and Audio Processing - Recent Developments and Applications
Explore cutting-edge AI advancements in image and signal processing, including segmentation, OCR, and speech technologies, with powerful neural network applications.
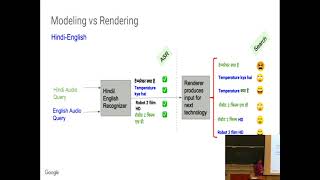
Transliteration-Based Approaches for Multilingual and Code-Switched Languages
Explore innovative approaches for multilingual ASR systems, focusing on code-switching challenges and transliteration-based solutions to improve accuracy and scalability in diverse linguistic environments.
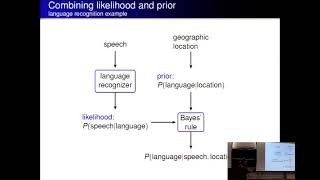
Binary and Multiclass Calibration in Speaker and Language Recognition
Explore probabilistic classification calibration in speaker and language recognition, focusing on cross-entropy's role in optimizing classifier performance across diverse applications.
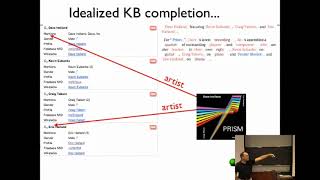
Low-Pass Semantics with a Bit of Discourse - November 2013
Explore advances in natural language processing and the challenge of creating systems that understand text, with insights on leveraging distributional regularities for effective analysis.
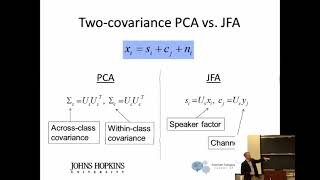
Recent Progress in Acoustic Speaker and Language Recognition - October 2013
Explore recent advancements in speaker and language recognition, focusing on GMM subspace methods, pattern classification, and Bayesian approaches for improved performance and domain adaptation.
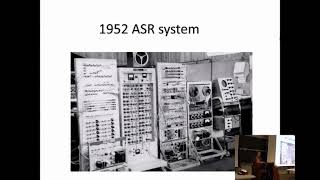
Neural Networks for Speech Recognition - 2013
Explore the evolution of neural networks in speech recognition, from early experiments to modern hybrid HMM/MLP approaches, with insights from a leading expert in the field.
Towards a Computational Model of Human Speech Recognition
Explore computational approaches to speech recognition based on distinctive features, incorporating statistical learning models guided by human speech production and perception.
My Adventures With Speech - 2013
Explore a 40-year journey in speech research, delving into personal insights, challenges, and breakthroughs in understanding human communication through speech.
Clean Label Poisoning Attacks: From Classification to Speech Recognition
Explore poisoning attacks in speech recognition, from adversarial manipulations to innovative defenses. Uncover strategies, mechanisms, and future research in AI security.
Deep Learning of Generative Models - 2014
Explore generative models in deep learning with Yoshua Bengio, covering motivations, applications, and fundamental challenges in AI and machine learning.