It's the Culture: Why Scrum is More Than a Few Roles - ETE 2012
Explore Scrum's cultural impact, values, and practices for hyper-productive teams. Learn how to implement Scrum effectively and avoid potential pitfalls in agile development.
Breaking Down Silos and Fostering Open Collaboration in Organizations
Learn strategies to break organizational silos, foster collaboration, and drive innovation by applying open-source principles within your company. Discover how to create synergies, leverage resources, and promote cross-team cooperation for better outcome…
The Future of Data Science Notebooks Is Collaborative
Explore the evolution of data science notebooks, their challenges, and the future of collaborative tools for modern data scientists. Learn about key trends and opportunities in this rapidly evolving field.
How Companies Are Using Tachyon, a Memory Centric Distributed Storage
Explore Tachyon, a memory-centric distributed storage system for fast big data processing. Learn about its benefits, use cases, and integration with popular frameworks like Spark and Hadoop.

Do These Pandas Alternatives Actually Work?
Benchmark comparison of Pandas alternatives: Dask, Modin, Ray, and Vaex. Evaluates speed performance on large datasets, offering insights for data scientists seeking faster Python data processing options.
Data Analyst Setup for Productivity - Python, R, SQL
Explore a data analyst's productivity setup, including Miniconda, Python environments, VSCode, R Studio, and essential hardware recommendations for efficient data analysis workflows.
Robot Framework Beginner Tutorial - First Selenium Test
Learn to create your first Selenium test using Robot Framework in Eclipse. Step-by-step guide covers installation, project setup, and test case creation for beginners.
Robot Framework Beginner Tutorial - Getting Started With Robot Framework Step by Step
Learn to set up Robot Framework from scratch, including installation, configuration, and helpful tips for beginners. Gain practical knowledge to start automating tests efficiently.
Robot Framework Beginner Tutorial - Jenkins
Learn to run Robot Framework tests in Jenkins for continuous integration, covering setup, job creation, and execution of automated tests.
Gatling Beginner Tutorial - Show Gatling Results on Grafana Dashboard
Learn to visualize Gatling performance test results on Grafana dashboards. Covers Grafana setup, Gatling plugin installation, data source configuration, and dashboard creation for effective result analysis.
Designing Your Tech Stack - Stay Organized with Office 365 Tools
Discover efficient organization techniques using Office 365 tools like Outlook, OneDrive, SharePoint, and Teams. Enhance collaboration, file management, and productivity in this practical workshop.

Data Processing Fundamentals - Extended Filtering with Multiple Datasets
Learn advanced data filtering techniques in Python, including category-based filtering, handling multiple datasets, and optimizing code with inline methods for efficient data processing.
Data Processing Fundamentals - Data Access and Filtering
Learn Python data processing techniques including data loading, reading, and value-based filtering. Gain practical skills in handling and manipulating datasets efficiently.
Introduction, Principles and Origin of Dagster
Introduction to Dagster: A data orchestrator for the entire application lifecycle. Covers principles, development, deployment, and monitoring. Includes demo and code snippets showcasing Dagit UI and Dagster programming model.
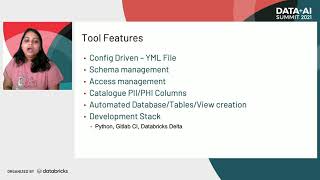
Automated Metadata Management in Data Lakes - A CI/CD Driven Approach
Discover a CI/CD-driven approach to automated metadata management in data lakes, focusing on balancing development speed, governance, and schema evolution for rapidly growing organizations.
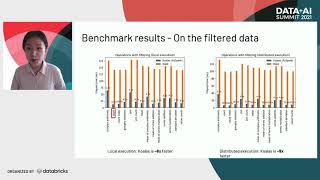
Koalas: Scaling Pandas APIs on Apache Spark - Performance and Comparison with Dask
Explore Koalas: pandas-like APIs for big data on Apache Spark. Compare performance with Dask, learn about recent updates, and understand its scalability for data science tasks.
Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
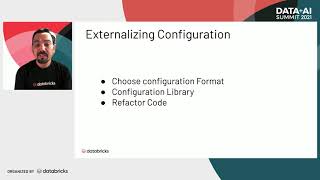
Dumb-Proofing Data Pipelines: Techniques for Configurable and Maintainable ETL - Databricks
Techniques to create configurable, maintainable data pipelines. Learn to externalize configurations, validate inputs, and leverage Scala features for robust, easily deployable ETL processes.
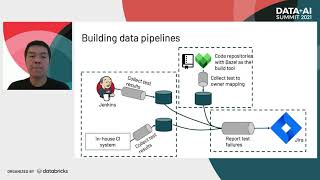
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.