Intrinsics - Low-Level Engine Development with Burst - Unite Copenhagen
Explore low-level engine development using Burst Compiler's expanded capabilities, including CPU intrinsics, SIMD optimization, and performance comparisons with C++.
CPU-Friendly Code
Explore CPU architecture, cache locality, branch prediction, and OS concepts to optimize code performance and efficiency beyond Big-O notation.
C++ Performance in Practice - Align, Vectorise, Cache, Jump!
Explore hardware-driven C++ performance optimization techniques including memory alignment, SIMD, cache-friendliness, and branch prediction with code examples and benchmarks.
Adventures in SIMD-Thinking
Explore SIMD capabilities in modern hardware, focusing on SSE, AVX, and AVX-512 instruction sets. Learn to leverage C++ for improved performance in real-world computing problems through vertical thinking.
SIMD Libraries in C++
Explore SIMD libraries in C++, including std::simd for C++26. Learn about application-level libraries, developer libraries, and design trade-offs for exploiting SIMD in modern C++ development.
JS Responsibilities
Explore JavaScript's future with Brendan Eich as he discusses ES6, ES7, Object.observe, asm.js, value objects, operator overloading, SIMD, and threads in this insightful talk.
Hardness of Scheme-Switching Between SIMD FHE Schemes - Session II
Explore the challenges of scheme-switching in SIMD FHE schemes, focusing on theoretical aspects and potential implications for post-quantum cryptography.
ARM64 SVE Concepts and Integration into DPDK
Explore Arm64's Scalable Vector Extension (SVE) concepts and learn how to integrate this powerful SIMD feature into DPDK libraries for enhanced performance and hardware adaptability.
Combining Rust and DPDK: Security, Stability, and Performance Optimization
Explore how Rust APIs can enhance DPDK functionality through improved security, user experience, and performance optimization while processing network packets efficiently.
Memory Wall Mitigation and Acceleration of AI Workloads Using CXL Near Memory Computing
Explore CXL-based Near Memory Compute architectures for hyperscale environments, focusing on acceleration solutions for data-intensive workloads and memory optimization techniques.
Zero-Overhead Parallel Scans for Multi-Core CPUs - ARRAY 2024
Explore efficient parallel scans for multi-core CPUs, achieving zero overhead and improved single-threaded performance in array languages.
Insights and Experiences of Packaging Python Binary Extensions
Explore challenges and solutions for packaging Python binary extensions in scientific computing, focusing on portability and performance across diverse platforms.
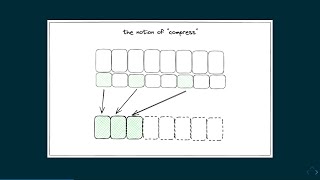
Advanced SIMD Algorithms in Pictures - Lecture
Explore advanced SIMD algorithms for memcmp, copy_if, and set_intersection through visual explanations. Gain insights into vectorized implementations without prior SIMD knowledge.
Advanced SIMD Algorithms in Pictures
Explore non-trivial SIMD algorithms like strcmp, set_intersect, and sort through visual explanations. Demystify vectorized algorithms for those with basic CS knowledge.
Heterogeneous Accelerator Toolkit (HAT) Update - Project Babylon and GPU Acceleration in Java
Explore updates on Java's Heterogeneous Accelerator Toolkit (HAT) project, focusing on GPU acceleration, programming models, and integration with Babylon and Panama FFM. Includes demos and future plans.
Fast C++ Using SIMD Types with Generic Lambdas and Filters - Lecture
Optimize C++ performance using SIMD types, generic lambdas, and filters. Learn to generate high-performance code competitive with standard libraries, exploring vectorization techniques and branching strategies.
Optimizing Code on Arm: VectorCamp's Approach to SVE and SVE2 Intrinsics
Explore VectorCamp's optimization techniques for SVE and SVE2 intrinsics, enhancing code performance on Arm architecture.
Java Parsing Optimization: Processing 1 Billion Rows of Weather Data
Explore Java optimization techniques to parse 1 billion rows of weather data, covering parallelism, memory-mapped files, SWAR, bit twiddling, and Graal native compilation for impressive performance gains.
std::simd - Expressing Inherent Parallelism Efficiently Via Data-parallel Types
Explore efficient data-parallelism using std::simd in C++26, learning to optimize compute-intensive workloads and design data structures for high-throughput execution.
Implementing Understandable World Class Hash Tables in C++ - CppCon 2022
Explore world-class hash table implementation in C++, focusing on Robin Hood hashing, parallel computation, and SIMD operations. Learn to optimize performance while maintaining code clarity and understandability.
Compile-Time Sparse Matrices - Optimizing Memory and Performance
Explore compile-time sparse matrices for efficient memory use and performance in C++ linear algebra. Learn to incorporate sparseness information, reduce storage, and optimize operations automatically.