Deploying SRE Training Best Practices to Production - What We Learned
Explore best practices for SRE training, including sequential learning, hands-on experiences, and continuous education. Learn from Google's insights on building effective SRE teams and fostering a culture of reliability.
Latency SLOs Done Right
Explore three approaches to accurately calculate latency SLOs using histograms for correct quantiles. Learn to frame SLOs effectively for improved service level management and monitoring.
SLOs for Data-Intensive Services
Explore the journey of defining effective SLOs for data-intensive services, focusing on search engines. Learn about monitoring processes, consistency, and automated mitigation strategies for complex systems.
Identifying Hidden Dependencies
Discover how Honeycomb improved system reliability through intentional node termination, uncovering bugs and progressing towards continuous experimentation for enhanced resilience and scalability.
Avoiding Goodhart's Law - Use SLOs as Tools Not Cudgels
Explore how to effectively use SLIs, SLOs, and Error Budgets as tools for balanced risk management and productive conversations, rather than punitive measures in SRE practices.
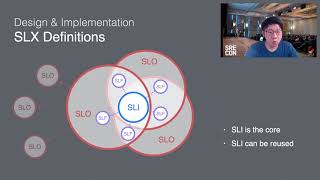
SLX - An Extended SLO Framework to Expedite Incident Recovery
Explore an extended SLO framework (SLX) for managing high-availability systems, featuring innovative concepts like SLF and SLD to build knowledge graphs and expedite incident recovery.
Optimizing Cost and Performance with Arm64
Explore how Honeycomb.io optimized cost and performance by migrating to arm64 architecture, reducing compute costs by 40% while improving latency, despite challenges in software compatibility and ecosystem complexity.
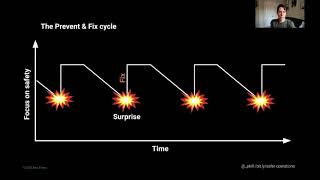
Are We Getting Better Yet? - Progress Toward Safer Operations
Exploring progress in safer operations, this talk delves into effective incident analysis, organizational learning, and strategic investments for improved reliability and team well-being.
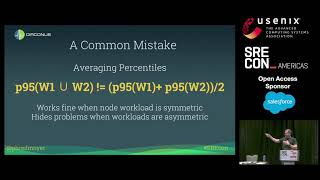
Latency SLOs Done Right
Explore correct approaches to calculating latency SLOs using histograms and mathematically accurate quantiles, improving service level objectives for more effective monitoring and performance management.
A Post Incident Review Review
Explore ANZx's unique post-incident review process, focusing on safety science concepts and avoiding root cause analysis or action items tracking in a regulated industry environment.
Fast & Simple Deployments for Code & Infra
Learn how Honeycomb optimized deployments using CircleCI, Terraform, Chef, and custom scripts. Discover strategies for faster, safer releases and risk mitigation through Service Level Objectives.
Rolling out Error Budgets Across a 1000 Person Global Engineering Org
Discover how Zendesk implemented error budgets and SRE practices to improve reliability across a global engineering team, addressing outages and change freezes while maintaining innovation.
Not All Minutes Are Equal - The Secret Behind SLO Adoption Failure
Uncover the truth behind SLO adoption failures, learn to calculate and prove their value, and understand key differences in measurement methods for better system reliability insights.
How SRE Makes Electric Vehicles
Applying SRE principles to electric vehicle manufacturing: Automation, CI/CD, Observability, and SLOs in a complex production line involving humans and robots.
The Map Is Not the Territory - How SLOs Lead Us Astray, and What We Can Do about It
Explore SLO limitations in complex services, understand failure modes, and learn best practices for robust SLO construction to improve reliability and decision-making in modern systems.
SLO Burn - Reducing Alert Fatigue and Maintenance Cost in Systems of Any Size
Discover strategies to reduce alert fatigue and maintenance costs in systems of any size using Service Level Objectives (SLOs) and symptom-based alerting with Prometheus.
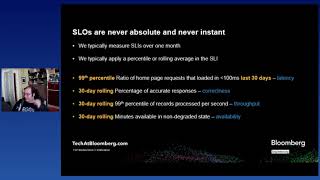
The Spec You Never Knew You Needed
Explore service level objectives and System Reliability Engineering, comparing them to functional specs for improved system performance, error handling, and data integrity.
Cultivating Production Excellence
Explore strategies for taming complex distributed systems through collaborative practices, observability, service level objectives, and risk analysis to achieve production excellence.

Cultivating Production Excellence
Explore practices for production excellence: stakeholder involvement, observability collaboration, Service Level Objectives, and risk-based improvement prioritization in complex distributed systems.
DataOps as a Service - Applying DevOps Practices to Data Engineering
Explore DevOps practices in data engineering, addressing challenges and showcasing the Versatile Data Kit for implementing DataOps principles.
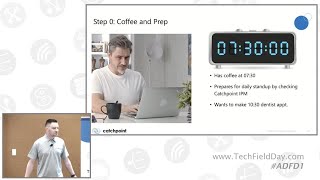
End-to-End Incident Analysis and Resolution with Catchpoint
Explore end-to-end incident management with Catchpoint Platform, from symptom detection through root cause analysis to implementing preventive measures for improved system reliability.