Bridging the Gap: Deep Learning and Causality
Explore the intersection of deep learning and causality, focusing on bridging the gap between these fields. Gain insights into recent advancements and their applications in computational genomics.
Provably Efficient Reinforcement Learning with Linear Function Approximation - Chi Jin
Explore efficient reinforcement learning with linear function approximation, covering key concepts like sample efficiency, value-based algorithms, and exploration in multi-armed bandits and linear MDPs.
Inference of Utilities and Time Preference in Sequential Decision-Making
Explore utility inference and time preference in sequential decision-making, focusing on mathematical finance applications and advanced analytical techniques.
Risk-Sensitive Bandits - Arm Mixtures Optimality and Regret-Efficient Algorithms
Delve into risk-aware sequential decision-making through distortion riskmetrics, exploring optimal arm mixture strategies and new algorithms for tracking these mixtures in multi-armed bandit problems.
Toward Generalizable Embodied AI for Machine Autonomy
Explore recent advancements in machine autonomy, focusing on generalizable embodied AI through sequential decision-making, simulation environments, and human-AI collaboration.
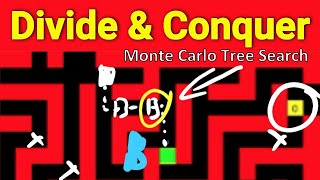
Divide-and-Conquer Monte Carlo Tree Search for Goal-Directed Planning - Paper Explained
Explores a novel AI planning approach using divide-and-conquer Monte Carlo Tree Search, proposing intermediate goals to break complex problems into manageable sub-tasks for more efficient problem-solving.
Better Learning from the Past - Counterfactual - Batch RL
Explore counterfactual and batch reinforcement learning for improved decision-making under uncertainty, with focus on generalization bounds and policy optimization techniques.
Off-Policy Policy Optimization
Explore advanced reinforcement learning techniques, focusing on off-policy optimization, batch methods, and sequential decision-making in deep learning contexts.
What Are the Statistical Limits of Offline Reinforcement Learning With Function Approximation?
Explore statistical limitations in offline reinforcement learning with function approximation, covering realizability, coverage, policy evaluation, and practical considerations.
Task-Driven Network Discovery via Deep Reinforcement Learning on Embedded Spaces
Explore task-driven network discovery using deep reinforcement learning on embedded spaces. Learn about improving network observability and optimizing data collection for accurate analysis.
Decision Diagrams for Efficient Inference and Optimization in Expressive Discrete-Continuous Domains
Explore extended algebraic decision diagrams (XADDs) for representing piecewise functions, enabling efficient computations and novel solutions in probabilistic inference, optimization, and decision-making.
Adaptive Sampling via Sequential Decision Making - András György
Explore adaptive sampling methods using multi-armed bandit algorithms and MCMC samplers to optimize resource allocation and improve sample quality in machine learning applications.
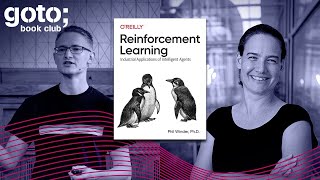
How to Leverage Reinforcement Learning
Explore reinforcement learning's key concepts, industry applications, and potential impact on business strategies. Gain insights into problem definition, interpretability challenges, and real-life implementations of RL algorithms.
How to Leverage Reinforcement Learning
Explore reinforcement learning's key concepts, industry applications, and implementation challenges with experts Phil Winder and Rebecca Nugent. Gain insights on problem definition, getting started, and managing risks in RL projects.
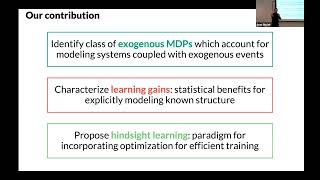
Hindsight Learning for MDPs with Exogenous Inputs
Explore data-efficient algorithms for resource management problems using Hindsight Learning in Exo-MDPs, outperforming traditional methods in various applications including cloud resource allocation.
Foundation Models and the Transfer of Embodied Autonomy
Explore challenges in developing foundation models for sequential decision-making, including transfer learning, and discuss future research directions in embodied autonomy.
High-Dimensional Prediction for Sequential Decision Making
Explore efficient algorithms for online high-dimensional predictions, enabling no-regret guarantees, fairness, and uncertainty quantification in multiclass settings for improved decision-making.
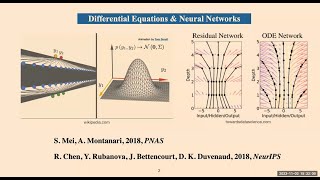
Continuous-in-time Limit for Bandits
Explore the connection between Hamilton-Jacobi-Bellman equations and multi-armed bandit problems, and discover an efficient algorithm for solving MAB challenges.
Adversarial Bandits: Theory and Algorithms
Explore adversarial multi-armed bandit theory, algorithms, and recent advances in data-dependent regret guarantees, structural bandits, and more. Compare full-information and bandit feedback in online learning.
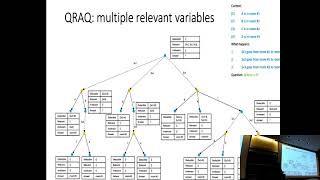
Deep Reinforcement Learning for Sequential Decision Making Tasks with Natural Language Interaction
Explore deep reinforcement learning applications in natural language tasks, focusing on querying ambiguous texts and navigating 3D mazes with unseen instructions using hierarchical architectures.
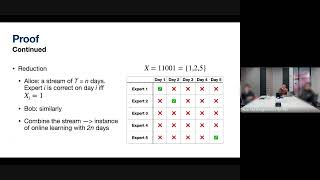
Online Prediction in Sub-linear Space
Explore innovative algorithms for online learning with expert advice, focusing on sub-linear memory solutions and their implications for sequential decision-making.