
SETFIT Few-Shot Learning for SBERT Text Classification - Part 43
Discover how SETFIT's few-shot learning approach revolutionizes text classification, outperforming GPT-3 while using SBERT Sentence Transformers for efficient processing with limited training data.
Beyond AI Vector Database - Neural Search Implementation with GPT-4 and ChatGPT
Discover how to build a cost-effective neural search system using tokenizers, embedders, and similarity calculations as an alternative to Azure Cognitive Search for domain-specific AI applications.
A Practical Approach for Few Shot Learning with SetFit - Haystack EU 2023
Explore SetFit for few-shot learning in classification and ranking, with a focus on legal research applications. Discover its potential to outperform GPT-3 in label-scarce settings.
Today Unsupervised Sentence Transformers, Tomorrow Skynet - How TSDAE Works
Explore unsupervised fine-tuning for sentence transformers using TSDAE. Learn to train models without labeled data, ideal for domains and languages with limited resources.
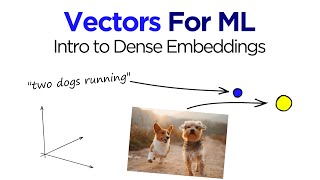
Intro to Dense Vectors for NLP and Vision
Explore dense vector representations in NLP and computer vision, from word2vec to modern transformer models, with practical Python implementations and applications.
Document Similarity: Langchain Sentence Transformers and Chroma
Explore document similarity using Langchain, HuggingFace Transformers, and Chromadb. Learn to create embeddings and implement vector storage for efficient text analysis and classification.
Practical LLM Fine-Tuning for Semantic Search
Explore fine-tuning LLMs for semantic search in specialized domains. Learn data requirements, training techniques, and practical insights to enhance search capabilities using open-source tools.